<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://andyatkinson.com/feed/by_tag/PostgreSQL.xml" rel="self" type="application/atom+xml" /><link href="https://andyatkinson.com/" rel="alternate" type="text/html" /><updated>2026-08-26T22:55:48+00:00</updated><id>https://andyatkinson.com/feed/by_tag/PostgreSQL.xml</id><title type="html">Software Engineer, Author, High Performance PostgreSQL for Rails</title><subtitle>Andrew Atkinson Software Engineer blog about PostgreSQL, Ruby on Rails, Elasticsearch, Kubernetes, and Vim. Andrew is the Author of Ruby bestseller High Performance PostgreSQL for Rails</subtitle><author><name>Andrew Atkinson</name></author><entry><title type="html">PostgreSQL 18: 23x Faster Inserts With UUID v7</title><link href="https://andyatkinson.com/postgresql-18-uuidv7" rel="alternate" type="text/html" title="PostgreSQL 18: 23x Faster Inserts With UUID v7" /><published>2026-08-26T11:50:00+00:00</published><updated>2026-08-26T11:50:00+00:00</updated><id>https://andyatkinson.com/postgresql-18-uuidv7</id><content type="html" xml:base="https://andyatkinson.com/postgresql-18-uuidv7"><![CDATA[<div class="summary-box">
<strong>📌 Overview</strong>
<p>We recently switched to version 7 (v7) uuid primary keys and saw significantly faster inserts for some tables.</p>
<p>The databases were running Postgres 18.4 and mostly used v1 with some v4 uuid values for primary keys.</p>
<p>Changing the column default involved running a single alter table command, but did require an exclusive lock on the table, blocking <em>everything</em> including selects.</p>
<p>To solve that, we used a short lock timeout and lots of retries.</p>
<p>The biggest speedup was 23x faster average execution time for a multi-row insert query called 12,000 times per minute on a table with billions of rows.</p>
</div>

<div style="
  max-width: 420px;
  margin: 2rem auto;
  padding: 1.25rem 1.5rem;
  background: #fff8b3;
  color: #333;
  border-left: 6px solid #f4d03f;
  border-radius: 3px;
  box-shadow: 3px 4px 10px rgba(0,0,0,0.15);
  font-family: sans-serif;
  transform: rotate(-1deg);
  position: relative;
">

  <div style="
    position: absolute;
    top: -10px;
    right: 20px;
    width: 70px;
    height: 22px;
    background: rgba(255,255,255,0.5);
    transform: rotate(4deg);
    border: 1px solid rgba(0,0,0,0.05);
  "></div>

  <strong style="display:block; margin-bottom:0.5rem;">
    Want to talk Postgres in person? 🐘
  </strong>

  <p style="margin:0; line-height:1.5;">
  This September and October I'll be in Austin, TX and NYC, check my <a href="/pgrailsbook">Book</a> page for upcoming appearances.
  </p>
</div>

<h2 id="history-and-trade-offs-with-uuids">History and trade-offs with UUIDs</h2>
<p>The system uses UUID primary keys throughout. I typically recommend starting with bigint and sequences over <a href="avoid-uuid-version-4-primary-keys">UUID v4 primary keys</a>, although here uuid v1 was used. Insert performance is not as bad for v1 compared with v4.</p>

<p>Still though, v7 brings better performance than both for inserts and can also result in smaller indexes with fewer page splits meaning less CPU and IO.</p>

<p>What drives bad performance for v4 and to a lesser extent v1? Let’s do a quick refresher. As new table rows are inserted and a primary key is defined, primary key values are maintained in sorted order in a b-tree index. Just like table rows, index entries in Postgres are stored in fixed size 8kb pages.</p>

<p>Postgres needs to know in which page to place the new index entry. For sorted order, the first bytes of new uuid values are compared.</p>

<p>For v4 given new values are very random and not monotonically increasing (they lack “monotonicity”), values can be earlier or later, meaning they’re unlikely to be placed into the same recently accessed page. This is bad for caching!</p>

<p>When new values are monotonically increasing, the recently accessed page is “hot” in the Postgres buffer cache (in memory copy of the on-disk page).</p>

<p>When Postgres is not able to use the hot index page for the newly inserted value, that page could be outside the buffer cache, not in the OS cache, and ultimately result in a much slower disk read which increases latency.</p>

<p>Besides the worse insert performance, since v4 values are scattered to more pages, this means there are more “page splits” when new inserts are attempted in full pages. Page splits cause more latency from increase WAL and IO.</p>

<p>We experimented and benchmarked with <a href="https://github.com/andyatkinson/pg_scripts/tree/main/uuid_experiments">v1, v4, and v7 uuid formats</a> and we leveraged the research and write-ups from external sources like the ones below.</p>

<ol>
  <li><a href="https://www.tigerdata.com/blog/how-sequential-uuidv7-boosts-ingestion-performance">How Sequential UUIDv7 Boosts Ingestion Performance</a></li>
  <li><a href="https://alan.is/insights/simplicity-and-power-of-uuid-v7/">Simplicity and power of UUID v7</a></li>
  <li><a href="https://www.umangsinha.in/blog/postgresql-uuid-performance-benchmark">PostgreSQL UUID Performance: Benchmarking Random (v4) and Time-based (v7) UUIDs</a></li>
</ol>

<p>Benchmarks are great, but what kind of real world results did we see?</p>

<h2 id="what-kinds-of-improvements-did-we-see">What kinds of improvements did we see?</h2>
<p>We decided to make this the new default unless v4 was needed for more randomness. After all qualified tables were changed, I began going through insert queries for each changed table. For many of the tables, there wasn’t an obvious change.</p>

<p>However, for a handful we saw an immediate and significant improvement. I picked 5 with speedups of 6x, 8x, 9x, 20x, and 23x.</p>

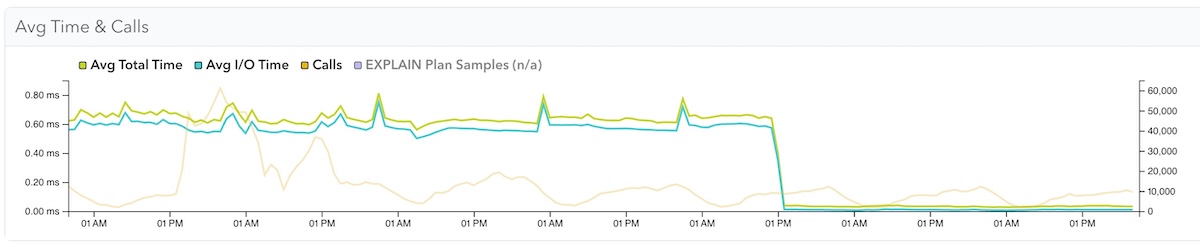
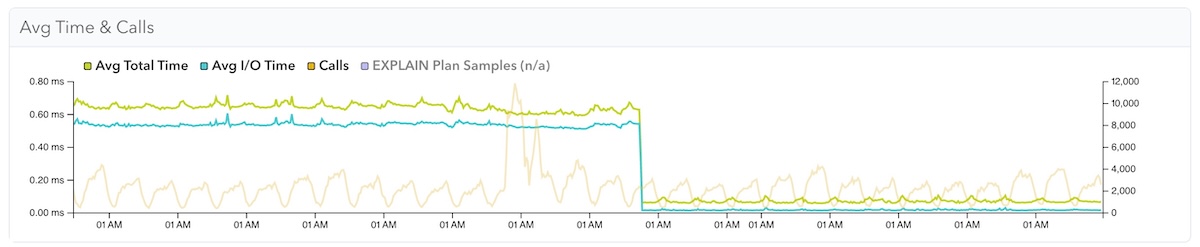
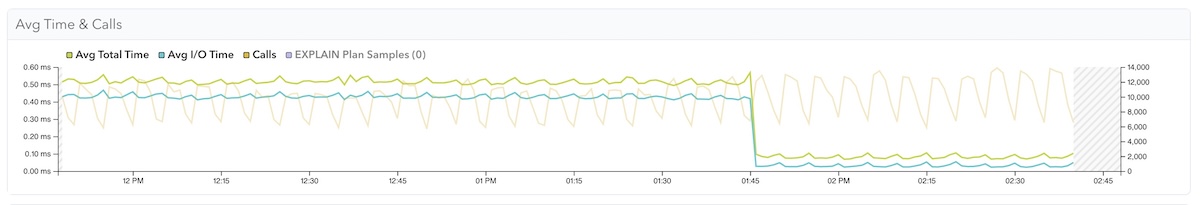
<p>The PgAnalyze graphs for the 23x, 9x, and 6x queries are shown below.</p>

<table class="styled-table">
  <thead>
    <tr>
      <th></th>
      <th>Calls/min</th>
      <th>Indexes</th>
      <th>Original time</th>
      <th>New</th>
      <th>Reduction</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Table A</td>
      <td>12,000</td>
      <td>2 (+1 PK)</td>
      <td>0.7ms</td>
      <td>0.03ms</td>
      <td>📉 23x</td>
    </tr>
    <tr>
      <td>Table B</td>
      <td>2000</td>
      <td>1 (+1 PK)</td>
      <td>0.6ms</td>
      <td>0.07ms</td>
      <td>📉 9x</td>
    </tr>
    <tr>
      <td>Table C</td>
      <td>9500</td>
      <td>2 (+1 PK)</td>
      <td>0.50ms</td>
      <td>0.08ms</td>
      <td>📉 6x</td>
    </tr>
  </tbody>
</table>

<p>Showing PgAnalyze insert query graphs for tables A, B, C:
<img src="/assets/images/uuidv7-4-table-do-pganalyze.jpg" alt="" />
<br />
<small>Table A - 23x reduction. 0.7ms to 0.03ms, 12000 calls/min</small></p>

<p><img src="/assets/images/uuidv7-3-table-c-pganalyze.jpg" alt="" />
<br />
<small>Table B - 9x reduction. 0.6ms to 0.07ms, 2000 calls/min</small></p>

<p><img src="/assets/images/uuidv7-2-table-th-pganalyze.jpg" alt="" />
<br />
<small>Table C - 6x reduction. 0.50ms to 0.08ms, 9500 calls/min</small></p>

<p>Now that we’ve seen the results, let’s talk about how this was done and the challenges.</p>

<h2 id="auditing-where-the-uuids-came-from">Auditing where the UUIDs came from</h2>
<p>The UUID values came from various sources:</p>

<ul>
  <li>The <code class="language-plaintext highlighter-rouge">uuid_generate_v1()</code> function from the <a href="https://www.postgresql.org/docs/current/uuid-ossp.html"><code class="language-plaintext highlighter-rouge">uuid-ossp</code> module</a></li>
  <li>The function <code class="language-plaintext highlighter-rouge">gen_random_uuid()</code> <a href="https://www.postgresql.org/docs/current/functions-uuid.html">added in Postgres 13</a> that generates v4 UUIDs natively</li>
  <li>UUID v4 values sent by a client application, which meant the column default function was not used</li>
</ul>

<p>We replaced most of these with the <code class="language-plaintext highlighter-rouge">uuidv7()</code> function in Postgres 18. To do that, we needed to run a single <code class="language-plaintext highlighter-rouge">alter table ... alter column</code> statement per table.</p>

<p>The statement ran fast, so no problem, right?</p>

<h2 id="how-did-the-switch-go">How did the switch go?</h2>
<p>One wrinkle we found was that modifying the column default while fast, required an <code class="language-plaintext highlighter-rouge">access exclusive</code> lock.</p>

<p>This lock type conflicts with <em>every</em> read and write operation including regular <code class="language-plaintext highlighter-rouge">select</code> statements.</p>

<p>For our highest queried tables, they’re queried constantly, so this was a problem. There was almost never a “window” to perform this operation, and we didn’t want to take downtime for this switch.</p>

<p>While heavily queried tables were a challenge, infrequently queried tables did not pose a problem for this alter table statement at all.</p>

<p>For those, we could use our migrations framework (Active Record in Ruby on Rails) and perform the <code class="language-plaintext highlighter-rouge">alter table</code> using a regular old migration.</p>

<p>For those, we did add some safeguards, by creating an explicit transaction and using <code class="language-plaintext highlighter-rouge">set local</code> to control timeout values. We’d set short timeouts for the <code class="language-plaintext highlighter-rouge">alter table</code> to give up quickly if it didn’t work or ran too long.</p>

<p>From psql:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">BEGIN</span><span class="p">;</span>

<span class="k">SET</span> <span class="k">LOCAL</span> <span class="n">lock_timeout</span> <span class="o">=</span> <span class="s1">'50ms'</span><span class="p">;</span>
<span class="k">SET</span> <span class="k">LOCAL</span> <span class="n">statement_timeout</span> <span class="o">=</span> <span class="s1">'100ms'</span><span class="p">;</span>

<span class="k">ALTER</span> <span class="k">TABLE</span> <span class="n">my_table</span> <span class="k">ALTER</span> <span class="k">COLUMN</span> <span class="n">id</span> <span class="k">SET</span> <span class="k">DEFAULT</span> <span class="n">uuidv7</span><span class="p">();</span>

<span class="k">COMMIT</span><span class="p">;</span>
</code></pre></div></div>

<p>For the higher activity tables, we’d need some retries. We’d use a manual psql session:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SET</span> <span class="n">lock_timeout</span> <span class="o">=</span> <span class="s1">'50ms'</span><span class="p">;</span>
<span class="k">SET</span> <span class="n">statement_timeout</span> <span class="o">=</span> <span class="s1">'100ms'</span><span class="p">;</span>
<span class="k">ALTER</span> <span class="k">TABLE</span> <span class="n">my_table</span> <span class="k">ALTER</span> <span class="k">COLUMN</span> <span class="n">id</span> <span class="k">SET</span> <span class="k">DEFAULT</span> <span class="n">uuidv7</span><span class="p">();</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">alter table</code> would commit if it grabbed the lock within 50ms, or we’d get an error that the <code class="language-plaintext highlighter-rouge">lock_timeout</code> was reached.</p>

<p>The benefit of the manual approach was we could retry until successful and backfill a Rails migration to keep everything in sync. A more sophisticated solution might have automated retries within Ruby.</p>

<p>However, for our most heavily queried tables, we wanted even more control over the retries.</p>

<p>How did we do that?</p>

<h2 id="bringing-in-the-big-retry-machinery">Bringing in the big retry machinery</h2>
<p>Sometimes one or two retries would do the job. Great, we’d move on.</p>

<p>However, for our most heavily queried table that didn’t work.</p>

<p>What ended up working was using the same strategy of retries, but just adding more sophistication with looping and backoffs.</p>

<p>Claude helped me cook up the PL/pgSQL looping retry function below, I did some testing and was ready to try it. It has these features:</p>
<ul>
  <li>Try up to 50 times (max attempts is configurable)</li>
  <li>Add a pause in between retries, with a jittered backoff of 50-250ms</li>
</ul>

<p>From psql:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SET</span> <span class="n">statement_timeout</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span>
<span class="k">SET</span> <span class="n">lock_timeout</span> <span class="o">=</span> <span class="s1">'100ms'</span><span class="p">;</span>

<span class="k">DO</span> <span class="err">$$</span>
<span class="k">DECLARE</span>
  <span class="n">attempt</span>      <span class="nb">INT</span> <span class="p">:</span><span class="o">=</span> <span class="mi">0</span><span class="p">;</span>
  <span class="n">max_attempts</span> <span class="nb">INT</span> <span class="p">:</span><span class="o">=</span> <span class="mi">50</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">LOOP</span>
    <span class="n">attempt</span> <span class="p">:</span><span class="o">=</span> <span class="n">attempt</span> <span class="o">+</span> <span class="mi">1</span><span class="p">;</span>
      <span class="k">BEGIN</span>
        <span class="k">EXECUTE</span> <span class="s1">'ALTER TABLE my_table ALTER COLUMN id SET DEFAULT uuidv7()'</span><span class="p">;</span>
        <span class="n">RAISE</span> <span class="n">NOTICE</span> <span class="s1">'Succeeded on attempt %'</span><span class="p">,</span> <span class="n">attempt</span><span class="p">;</span>
        <span class="n">EXIT</span><span class="p">;</span>
      <span class="n">EXCEPTION</span> <span class="k">WHEN</span> <span class="n">lock_not_available</span> <span class="k">THEN</span>
        <span class="n">IF</span> <span class="n">attempt</span> <span class="o">&gt;=</span> <span class="n">max_attempts</span> <span class="k">THEN</span>
          <span class="n">RAISE</span> <span class="n">EXCEPTION</span> <span class="s1">'Failed to acquire lock after % attempts'</span><span class="p">,</span> <span class="n">attempt</span><span class="p">;</span>
        <span class="k">END</span> <span class="n">IF</span><span class="p">;</span>
      <span class="n">PERFORM</span> <span class="n">pg_sleep</span><span class="p">(</span><span class="mi">0</span><span class="p">.</span><span class="mi">05</span> <span class="o">+</span> <span class="n">random</span><span class="p">()</span> <span class="o">*</span> <span class="mi">0</span><span class="p">.</span><span class="mi">2</span><span class="p">);</span>  <span class="c1">-- jittered backoff, 50-250ms</span>
    <span class="k">END</span><span class="p">;</span>
  <span class="k">END</span> <span class="n">LOOP</span><span class="p">;</span>
<span class="k">END</span> <span class="err">$$</span><span class="p">;</span>
</code></pre></div></div>

<p>By using the function above, we were able to find a small window to perform the <code class="language-plaintext highlighter-rouge">alter table</code> after several dozen quick retries!</p>

<h2 id="actively-cancelling-lock-holding-queries">Actively cancelling lock-holding queries</h2>
<p>In cases where even many retries won’t work, and we don’t want downtime, we may be left with needing to actively monitor lock holder queries and to cancel them (assuming that’s ok).</p>

<p>Thanks to Ants Aasma from the community PostgreSQL Slack for this idea.</p>

<p>We didn’t end up needing to do this, but here was my prep for this. It’s still useful to review lock holder queries.</p>

<p>First we’d inspect live queries:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span>
  <span class="n">pid</span><span class="p">,</span> <span class="k">state</span><span class="p">,</span> <span class="k">left</span><span class="p">(</span><span class="n">query</span><span class="p">,</span><span class="mi">100</span><span class="p">),</span> <span class="n">xact_start</span><span class="p">,</span> <span class="n">state_change</span><span class="p">,</span>
  <span class="n">age</span><span class="p">(</span><span class="n">clock_timestamp</span><span class="p">(),</span> <span class="n">xact_start</span><span class="p">)</span> <span class="k">AS</span> <span class="n">tx_duration</span>
<span class="k">FROM</span>
  <span class="n">pg_stat_activity</span>
<span class="k">WHERE</span>
  <span class="k">state</span> <span class="o">!=</span> <span class="s1">'idle'</span>
<span class="k">ORDER</span> <span class="k">BY</span> <span class="n">xact_start</span><span class="p">;</span>
</code></pre></div></div>

<p>And identify queries holding locks:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span>
  <span class="n">blocked_locks</span><span class="p">.</span><span class="n">pid</span> <span class="k">AS</span> <span class="n">blocked_pid</span><span class="p">,</span>
  <span class="n">blocking_locks</span><span class="p">.</span><span class="n">pid</span> <span class="k">AS</span> <span class="n">blocking_pid</span><span class="p">,</span>
  <span class="n">blocked_activity</span><span class="p">.</span><span class="n">query</span> <span class="k">AS</span> <span class="n">blocked_statement</span><span class="p">,</span>
  <span class="n">blocking_activity</span><span class="p">.</span><span class="n">query</span> <span class="k">AS</span> <span class="n">current_statement_in_blocking_process</span>
<span class="k">FROM</span>
  <span class="n">pg_catalog</span><span class="p">.</span><span class="n">pg_locks</span> <span class="n">blocked_locks</span>
<span class="k">JOIN</span>
  <span class="n">pg_catalog</span><span class="p">.</span><span class="n">pg_stat_activity</span> <span class="n">blocked_activity</span>
  <span class="k">ON</span> <span class="n">blocked_activity</span><span class="p">.</span><span class="n">pid</span> <span class="o">=</span> <span class="n">blocked_locks</span><span class="p">.</span><span class="n">pid</span>
<span class="k">JOIN</span> <span class="n">pg_catalog</span><span class="p">.</span><span class="n">pg_locks</span> <span class="n">blocking_locks</span>
  <span class="k">ON</span> <span class="n">blocking_locks</span><span class="p">.</span><span class="n">locktype</span> <span class="o">=</span> <span class="n">blocked_locks</span><span class="p">.</span><span class="n">locktype</span>
  <span class="k">AND</span> <span class="n">blocking_locks</span><span class="p">.</span><span class="n">relation</span> <span class="k">IS</span> <span class="k">NOT</span> <span class="k">DISTINCT</span> <span class="k">FROM</span> <span class="n">blocked_locks</span><span class="p">.</span><span class="n">relation</span>
  <span class="k">AND</span> <span class="n">blocking_locks</span><span class="p">.</span><span class="n">pid</span> <span class="o">!=</span> <span class="n">blocked_locks</span><span class="p">.</span><span class="n">pid</span>
<span class="k">JOIN</span> <span class="n">pg_catalog</span><span class="p">.</span><span class="n">pg_stat_activity</span> <span class="n">blocking_activity</span>
  <span class="k">ON</span> <span class="n">blocking_activity</span><span class="p">.</span><span class="n">pid</span> <span class="o">=</span> <span class="n">blocking_locks</span><span class="p">.</span><span class="n">pid</span>
<span class="k">WHERE</span> <span class="k">NOT</span> <span class="n">blocked_locks</span><span class="p">.</span><span class="k">granted</span><span class="p">;</span>
</code></pre></div></div>

<p>If we find them, we could cancel them to create a window to run our <code class="language-plaintext highlighter-rouge">alter table</code>. That could mean bad user experience so you’d need to figure that out for your database.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">pg_cancel_backend</span><span class="p">(</span><span class="n">blocking_pid</span><span class="p">);</span>
</code></pre></div></div>

<p>We’d likely want to stack up our <code class="language-plaintext highlighter-rouge">alter table</code> operation to occur immediately after. Fortunately we didn’t end up needing to do this, but I’d be interested to hear the stories from others with heavily queried databases.</p>

<h2 id="downsides-of-uuid-v7">Downsides of uuid v7</h2>
<p>Since uuid v7 values use a timestamp in their first bits, this timestamp can be easily decoded. This can be viewed as “leaking” or exposing the creation time of the record via that timestamp, which could be a downside for your database. You’ll have to decide that. v4 UUIDs do not expose the creation time.</p>

<h2 id="wrap-up">Wrap Up</h2>
<p>We found some significant speedups for insert queries after switching to <code class="language-plaintext highlighter-rouge">uuidv7()</code> primary keys, for a relatively low effort change. A nice ROI.</p>

<p>The only wrinkle was the exclusive lock <code class="language-plaintext highlighter-rouge">alter table ... alter column</code> required, but we solved that with short lock related timeouts and many retries.</p>

<p>Although this didn’t benefit 100% of our tables, the gains for some were significant and uuid v7 has become our new default choice for uuid primary keys.</p>

<p>Thanks to the Postgres core team for creating this new capability within Postgres. The availability in core made it possible to adopt on AWS RDS which supports a limited amount of extensions.</p>

<p>Thanks for reading, and until next time.</p>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><summary type="html"><![CDATA[📌 Overview We recently switched to version 7 (v7) uuid primary keys and saw significantly faster inserts for some tables. The databases were running Postgres 18.4 and mostly used v1 with some v4 uuid values for primary keys. Changing the column default involved running a single alter table command, but did require an exclusive lock on the table, blocking everything including selects. To solve that, we used a short lock timeout and lots of retries. The biggest speedup was 23x faster average execution time for a multi-row insert query called 12,000 times per minute on a table with billions of rows.]]></summary></entry><entry><title type="html">From Christmas Outage to #1 App Store Ranking: An Aura Frames Postgres Scaling Retrospective</title><link href="https://andyatkinson.com/postgresql-rds-scaling-aws-christmas-day-peak" rel="alternate" type="text/html" title="From Christmas Outage to #1 App Store Ranking: An Aura Frames Postgres Scaling Retrospective" /><published>2026-06-16T13:15:00+00:00</published><updated>2026-06-16T13:15:00+00:00</updated><id>https://andyatkinson.com/rds-postgresql-scaling-aws-christmas-day</id><content type="html" xml:base="https://andyatkinson.com/postgresql-rds-scaling-aws-christmas-day-peak"><![CDATA[<div class="summary-box">
<strong>📌 Overview</strong>
<p>
On Christmas Day 2024, Postgres infrastructure powering the Aura Frames API had problems under peak load, being unavailable for three hours and disrupting the experience for new customers. The team knew it would need improvements to handle the surge for Christmas 2025 and beyond.</p>
<p>
One year later, much of the resource intensive data access was reworked, the Postgres infrastructure was upsized, and this approach not only survived, but thrived, providing reliable service through the holiday season. </p>
<p>
The sum of Transactions Per Second (TPS) across the DBs peaked at 226,000, with more than 100K TPS sustained for 10 hours and repeating on multiple days after Christmas, with an average query time of 25 microseconds.
</p>
<p>The improved reliability meant customers could smoothly set up new frames and add photos, and they did it more than ever, with the Aura Frames app reaching #1 in U.S. and Canadian Apple and Android App Stores on Christmas Day.</p>
<p>
In this post we’ll look back at the months of planning and execution that went into achieving that outcome!
</p>
<p>
A second post in this series will dig into the Ruby on Rails side, while this one will focus on Postgres.
</p>
</div>

<h2 id="whats-aura-frames">What’s Aura Frames?</h2>
<p><a href="https://auraframes.com">Aura Frames</a> (Aura Home, Inc.) is the company behind modern, high-quality, Wi-Fi connected digital photo frames that customers love.</p>

<p>The frames are easy to use via free iOS and Android apps, don’t require a subscription, and offer unlimited cloud storage for photos and videos. Once set up, family members can be invited to contribute photos and videos via the app from anywhere. Typically Aura frames have an average of 4 contributors adding content.</p>

<p>In 2025, more than 1 billion photos were shared to Aura frames globally.</p>

<p>While public engineering blog posts are limited, Aura was featured on the AWS Storage Blog in the past. Link: <a href="https://aws.amazon.com/blogs/storage/how-aura-improves-database-performance-using-amazon-s3-express-one-zone-for-caching/">How Aura improves database performance using Amazon S3 Express One Zone for caching</a>.</p>

<h2 id="disclosures">Disclosures</h2>
<p>I began working with Aura in 2025. Aura does not have a public engineering blog, so we discussed me writing a post here where I regularly write about Postgres, Ruby on Rails, and scaling databases.</p>

<p>This post was written by me and I do not speak for the company. The company had the opportunity to review and make minor edits before publication.</p>

<p>The Christmas Day outage was a painful reality of scaling fast, and I appreciate Aura’s willingness to discuss it here.</p>

<p>I’m biased, but from my view the company is dedicated to continually improving the customer experience, in part with strategic investments in technical infrastructure.</p>

<p>With that covered, let’s take a look at how the frames are used and what drives the traffic.</p>

<h2 id="what-causes-the-sharp-increase-in-traffic">What causes the sharp increase in traffic?</h2>
<p>On Christmas Day, millions of customers set up hundreds of thousands of new Aura frames. The backend platform needs to work well for both existing customers and handle the load from new customer activity. For new customers it’s especially critical they have a good experience from their first moments with the product.</p>

<p>While the holiday timing is predictable, the rate of new frames and new photos added each year increases, adding a new amount of pressure to infrastructure components. Postgres is not easily horizontally scalable, and is costly to operate.</p>

<p>The average amount of increased peak TPS for all DBs on Christmas Day was ~4.5x, with the biggest being ~18x the normal value. To meet this demand, advanced financial planning and vertical scaling were needed. Resources were all shrunk back down after to save on costs.</p>

<h2 id="scaling-over-the-years">Scaling over the years</h2>
<p>The team has executed a variety of scaling tactics over the last half decade by employees and in conjunction with Postgres consultants. Scaling efforts often focused on reducing pressure on Postgres within the constraints of a single primary instance, while preserving its operational simplicity. (See: <a href="https://blog.danslimmon.com/2023/08/11/squeeze-the-hell-out-of-the-system-you-have/">Squeeze the hell out of the system you have</a> for a similar philosophy).</p>

<p>Scaling is more straightforward on the stateless, HTTP side. Aura uses AWS and has leveraged Auto Scaling Groups (ASGs), which can scale up to thousands of EC2 instances running the web application stack, image processing, PgBouncer, and other services.</p>

<p>For Postgres, vertical scaling of a single primary instance was leveraged as long as possible.</p>

<p>Here’s a look at the primary database instance at peak for Christmas Day 2024. Note that the db.r6g.48xlarge instance was the largest instance available for RDS.</p>
<table class="styled-table">
  <thead>
    <tr>
      <th>Postgres Version</th>
      <th>RDS Instance Class</th>
      <th>vCPU</th>
      <th>Memory (GiB)</th>
      <th>Storage Type</th>
      <th>DLV</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>14.x</td>
      <td>rb.r7i.48xlarge</td>
      <td>192</td>
      <td>1536</td>
      <td>io2</td>
      <td>⚠️</td>
    </tr>
  </tbody>
</table>

<p>Without a larger instance to move to, the team could not rely on vertical scaling for Christmas 2025 and beyond.</p>

<p>⚠️  For Christmas 2024, the team had a Dedicated Log Volume (DLV) in place for replication from the main instance. Replication management was one of the main challenges. A DLV reduces latency and improves reliability for replication.</p>

<p>Quoting from <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_PIOPS.dlv.html">AWS Docs on Using a Dedicated Log Volume (DLV)</a>:</p>
<blockquote>
  <p>A DLV moves PostgreSQL database transaction logs … to a storage volume that’s separate from the volume containing the database tables.</p>
</blockquote>

<p>While replication lag is “normal” (asynchronous streaming replication) and varies due to write pressure, vacuum activity, and more, performance on the primary had not previously been affected by replication lag before.</p>

<p>Unfortunately that changed during peak load on Christmas 2024. More details are below in the Christmas 2024 Retrospective section.</p>

<p>Before diving into that, let’s briefly cover some of the generic challenges of reaching the scalability limits of a single instance.</p>

<h2 id="postgres-scaling-challenges-and-solutions">Postgres Scaling Challenges and Solutions</h2>
<p>The use of Postgres at Aura faced all kinds of common Postgres scaling challenges.</p>

<ul>
  <li>Insert latency. To help reduce latency, foreign key constraints are not used. Indexes on high write tables are minimized. Indexes are periodically rebuilt (<code class="language-plaintext highlighter-rouge">reindex concurrently</code>).</li>
  <li>Replication. The product needs read-after-write behavior and can have high replication lag, so read replicas have historically not been used for read queries. Read queries run on the primary.</li>
  <li>Buffer cache and high cache hit rates. It’s critical to have page and index content for key queries in the buffer cache to achieve sub-millisecond query durations. Buffer cache memory access also reduces storage device IOPS.</li>
  <li>IOPS spikes that exceed the max Provisioned IOPS are problematic, resulting in queuing and high latency.</li>
  <li>The team faced CPU spikes in the single primary configuration, during vacuum, reproduced in load testing. High query latency across the DB would follow.</li>
  <li>During peak load periods, the system needs to handle tens of thousands of client connections from the application.</li>
  <li>The application tracks per-user counts that constantly change. For example, social media-style likes, comments, and activity feeds. These counts are stored in Memcached when possible, with connections managed by HAProxy.</li>
  <li>Autovacuum triggered vacuums during busy periods are disruptive. To minimize disruption, Autovacuum is throttled to run slower (<code class="language-plaintext highlighter-rouge">autovacuum_vacuum_cost_limit</code>, <code class="language-plaintext highlighter-rouge">autovacuum_vacuum_cost_delay</code>). Tables with heavy dead tuple growth are vacuumed manually in a low activity period overnight, not by Autovacuum.</li>
  <li>Index bloat. The database uses a primary key data type that isn’t 100% ideal for minimizing bloat. Indexes are periodically rebuilt, but that process adds a lot of IOPS pressure so the timing needs coordination and PIOPS need to be upsized.</li>
  <li>Configuration complexity. Postgres parameters (GUCs) are modified beyond what RDS provides sparingly. One exception is Autovacuum parameters which are monitored and adjusted often to help control spikes in IOPS.</li>
  <li>Background work state and queue style data could be managed separately. The team had previously created a separate Postgres database to manage the state of background work.</li>
</ul>

<h2 id="christmas-2024-retrospective">Christmas 2024 Retrospective</h2>
<p>Unfortunately on Christmas Day 2024, the team, platform, and customers faced a significant outage. A root cause analysis revealed that the main contributor was running out of space on the DLV, due to the growth of write-ahead logs (WAL) filling it up.</p>

<p>The team had provisioned a <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_PIOPS.dlv.html">Dedicated Log Volume (DLV)</a> offering lower latency as a dedicated volume for WAL log storage.</p>

<p>The team traced the root cause back to a change introduced in RDS Postgres 14.1 (the prior year ran Postgres 13.x which used S3 for WAL archival), which began using replication slots for replication.</p>

<p>“We weren’t aware RDS had changed in-region replication to use replication slots by default in Postgres 14.1. This caused the amount of WAL stored on the primary to be unbounded when the replica lagged.”</p>

<p>(AWS source: <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_PostgreSQL.Replication.ReadReplicas.Monitor.html">RDS “Monitoring replication slots for your RDS for PostgreSQL DB instance”</a>) “RDS for PostgreSQL 14.1 and higher versions use replication slots for in-Region read replicas.”</p>

<p>The Postgres docs describe the benefits of replication slots: “Replication slots provide an automated way to ensure that the primary server does not remove WAL segments until they have been received by all standbys” in <a href="https://www.postgresql.org/docs/17/warm-standby.html#STREAMING-REPLICATION-SLOTS">26.2.6. Replication Slots</a>.</p>

<p>The trade-off can be severe, as there’s the possibility of unbounded slot growth for inactive (or heavily lagging) slots, resulting in pg_wal filling the storage volume and causing Postgres to shut down. There’s a big “Caution” about this in the documentation, which looks new since Postgres version 17.</p>

<p>This is documented in community Postgres under <a href="https://www.postgresql.org/docs/16/disk-full.html">Disk Full Failure</a> (Docs for Postgres 16.x) or under “No space left on device” <a href="https://wiki.postgresql.org/wiki/ENOSPC">ENOSPC</a> on the wiki.</p>
<blockquote>
  <p>The server will crash and run crash recovery.</p>
</blockquote>

<p>One way to limit the growth is to set <a href="https://postgresqlco.nf/doc/en/param/max_slot_wal_keep_size/"><code class="language-plaintext highlighter-rouge">max_slot_wal_keep_size</code></a> (<a href="https://www.postgresql.org/docs/current/runtime-config-replication.html">Postgres replication docs</a>) (new in 13, default value is <code class="language-plaintext highlighter-rouge">-1</code> which means uncapped). <code class="language-plaintext highlighter-rouge">wal_keep_size</code>, <code class="language-plaintext highlighter-rouge">max_slot_wal_keep_size</code>, and <code class="language-plaintext highlighter-rouge">max_wal_size</code> were all updated going forward. Why set these? In a worst case, the replica would become unusable but not cause the primary to shut down.</p>

<p>With the replication issue solved going forward, the team faced a second issue, problematic occasional CPU spikes during vacuum. The issue was reproducible under load testing. A variety of theories were explored, evidence collected within the constraints of RDS, but no very strong causes and sources of evidence were discovered.</p>

<p>RDS Postgres limits access to the underlying host OS making it impossible to directly use <a href="https://perfwiki.github.io/main/">Linux profiling tools like perf</a> (as compared with something like running community Postgres on EC2).</p>

<p>Given this experience and the unsolved issue, the team began exploring moving to multiple Postgres instances, beyond a single instance. This would bring new complexity, but expanded capacity.</p>

<p>Proofs of concept for sharding from the application were explored. The team preferred mature solutions and a high degree of owner-operator control, thus a custom solution with Ruby on Rails framework capabilities had the lowest friction.</p>

<p>Ruby on Rails <a href="https://guides.rubyonrails.org/active_record_multiple_databases.html#horizontal-sharding">Horizontal Sharding</a> was partially built out and could have been a viable solution, but ultimately was not chosen.</p>

<p>With more than half of 2025 gone, Christmas Day 2025 was looming and daunting. An additional constraint on possible solutions was what could be built and supported in a matter of a few months by a small team.</p>

<p>The clock was ticking!</p>

<h2 id="postgres-christmas-2025">Postgres Christmas 2025</h2>
<p>The solution that seemed to fit the best would be a custom solution, rewriting a lot of the application query layer, taking direct control of key queries, high call volume, on big tables, and distributing the work to more instances.</p>

<p>To prepare, the top 10 tables by write operations and size were analyzed. All queries for those tables would need to be analyzed for incompatible elements that don’t work across a database boundary, like joins and some subqueries.</p>

<p>Ultimately the 10 tables were distributed to 7 new primary instances (making 8 in total), some DBs with as few as 1 table. All reads and writes continued to flow from the same Ruby on Rails codebase, not new microservices. To achieve that we’d use <a href="https://guides.rubyonrails.org/active_record_multiple_databases.html">Active Record Multiple Databases</a> support. That meant that each primary database would get the full <em>accoutrement</em>, including its own named config, the option of a read replica, and the ability to manage schema definition DDL changes (Rails “Migrations”). The production configuration would be mirrored in all lower environments so that the extensive unit test suite would run across all 8 databases. The only difference in the development environment was the 8 databases ran on one Docker Postgres container.</p>

<p>With the plan in place, it was time to start coding! We got started in earnest around August 2025 with 3 months to execute and validate the plan ahead of Christmas.</p>

<p>With each instance dedicated to one or a couple of tables, there was much more CPU, Memory, and IOPS available in total. This allowed each of the instances to be over provisioned temporarily before Christmas, adding headroom, availability, and reliability.</p>

<p>We determined the query workload for the biggest table by size, row count, call frequency and % of IO would still fit ok on a single big instance, without needing to shard the table rows.</p>

<p>Here’s what the instances were scaled up to for Christmas 2025. (Older generation: Graviton2 ARM and DDR4 memory)</p>
<table class="styled-table">
  <thead>
    <tr>
      <th>Postgres Version</th>
      <th>RDS Instance Class</th>
      <th>vCPU</th>
      <th>Memory (GiB)</th>
      <th>Storage Type</th>
      <th>DLV</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>17.6</td>
      <td>db.r8g.48xlarge</td>
      <td>192</td>
      <td>1536</td>
      <td>io2</td>
      <td>✅</td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r8g.48xlarge</td>
      <td>192</td>
      <td>1536</td>
      <td>io2</td>
      <td>✅</td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r8g.48xlarge</td>
      <td>192</td>
      <td>1536</td>
      <td>io2</td>
      <td>✅</td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r6g.16xlarge</td>
      <td>64</td>
      <td>512</td>
      <td>gp3</td>
      <td></td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r6g.16xlarge</td>
      <td>64</td>
      <td>512</td>
      <td>gp3</td>
      <td></td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r6g.16xlarge</td>
      <td>64</td>
      <td>512</td>
      <td>gp3</td>
      <td></td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r6g.16xlarge</td>
      <td>64</td>
      <td>512</td>
      <td>gp3</td>
      <td></td>
    </tr>
    <tr>
      <td>17.6</td>
      <td>db.r6g.16xlarge</td>
      <td>64</td>
      <td>512</td>
      <td>gp3</td>
      <td></td>
    </tr>
  </tbody>
  <tfoot>
    <tr class="summary-row">
      <td></td>
      <td><strong>Totals</strong></td>
      <td>896 vCPU (<strong>~4.7x ↗</strong>)</td>
      <td>7168 GiB (<strong>~4.7x ↗</strong>)</td>
      <td></td>
      <td></td>
    </tr>
  </tfoot>
</table>

<p>With ~4.7x more CPU, Memory, and more IOPS, the expanded capacity provided plenty of power through Christmas! We’ll look at how we scaled down to reduce costs after Christmas in an upcoming section.</p>

<p>Let’s look at the sharding strategy in more detail.</p>

<h2 id="workload-driven-whole-table-sharding">Workload-driven “Whole table sharding”</h2>
<p>We ended up using the term “whole table sharding” and the tables picked tended to have the most writes, the most rows, and be the most challenging to vacuum quickly or rebuild indexes for.</p>

<p>We were able to gradually modify all the application queries and get everything rolled out where it was backwards compatible, then we could cut over.</p>

<p>To transition the row data, wanting to initially replicate it, we tried using <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Appendix.PostgreSQL.CommonDBATasks.pglogical.html">AWS pglogical</a> and logical replication directly but the initial replication was too slow.</p>

<p>We may revisit that in the future, however we ultimately decided on <em>physical</em> replication which copied the whole instance, before cutting over to the new one. While more wasteful initially, we knew we could operate that approach reliably and with a minimal amount of downtime.</p>

<p>The major downside of this approach was that we had to repeat it 7 times, duplicating the entire database, consuming a ton of extra space temporarily.</p>

<p>We decided the trade-off was worth it; we could re-provision new instances and reduce space after Christmas by using the <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/blue-green-deployments.html">AWS Blue/Green deployments</a>. More on that later.</p>

<p>Let’s look at some metrics from Christmas 2025.</p>

<h2 id="postgres-and-infra-metrics-christmas-2025">Postgres and Infra Metrics Christmas 2025</h2>
<p>All Postgres instances were upgraded to 17.6 in the Fall of 2025. TPS measured by <a href="https://odarix.com/">Odarix</a>. PgBouncer, Memcached, HAProxy metrics from CloudWatch. Query and schema details from PgAnalyze.</p>

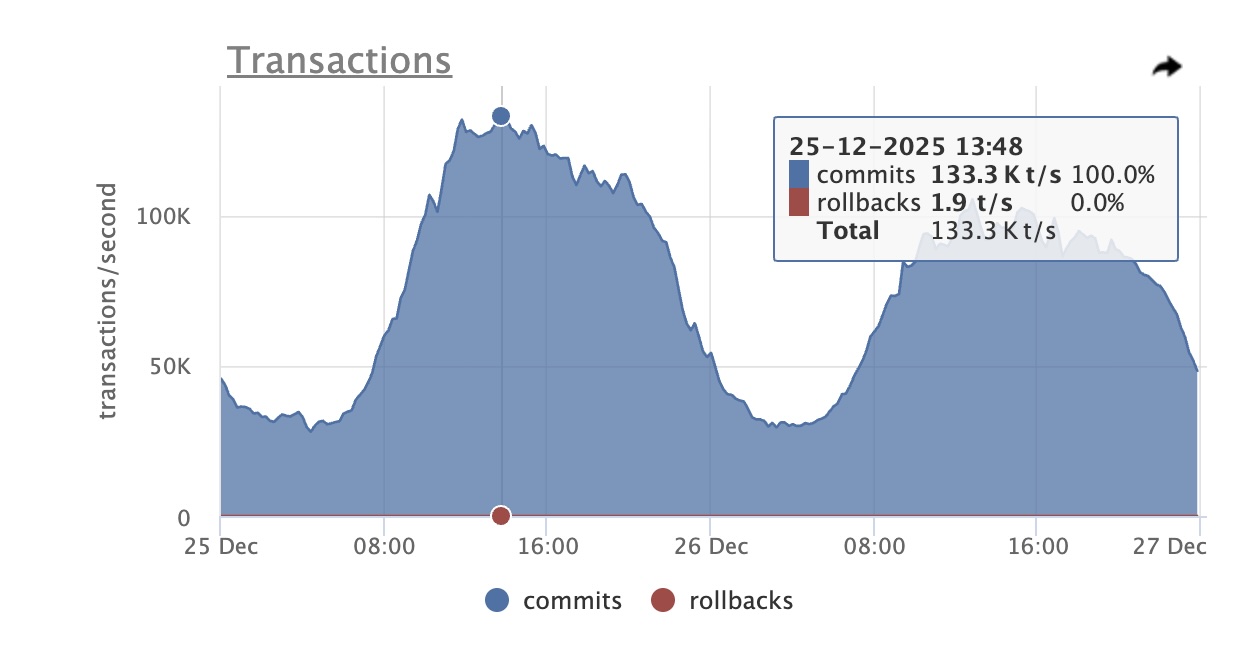
<p><img src="/assets/images/aura-tps-peak-christmas-2025.jpg" alt="Main DB 133K TPS Peak Christmas Day Odarix Screenshot" />
<small>Main DB 133K TPS Peak Christmas Day Odarix Screenshot</small></p>

<table class="styled-table">
  <thead>
    <tr>
      <th>Metric</th>
      <th>Normal</th>
      <th>Christmas Day</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Main DB TPS Peak</td>
      <td>40K</td>
      <td>133K (<strong>3.3x ↗</strong>)</td>
      <td></td>
    </tr>
    <tr>
      <td>All DB TPS Peak Sum</td>
      <td>50K</td>
      <td>226K (<strong>4.5x ↗</strong>)</td>
      <td></td>
    </tr>
    <tr>
      <td>Average query time</td>
      <td></td>
      <td>25 microseconds</td>
      <td></td>
    </tr>
    <tr>
      <td>Largest table</td>
      <td></td>
      <td></td>
      <td>7TB</td>
    </tr>
    <tr>
      <td>Total space</td>
      <td></td>
      <td></td>
      <td>30TB</td>
    </tr>
    <tr>
      <td>Largest row count</td>
      <td></td>
      <td></td>
      <td>7B (Billion)</td>
    </tr>
    <tr>
      <td>PgBouncer Instances (Sum)</td>
      <td>73</td>
      <td>230 (<strong>~3.1x ↗</strong>)</td>
      <td></td>
    </tr>
    <tr>
      <td>PgBouncer Client Connections</td>
      <td>7.3K</td>
      <td>~40K (<strong>~5.5x ↗</strong>)</td>
      <td></td>
    </tr>
    <tr>
      <td>Biggest Dead Tuple Growth</td>
      <td>8M</td>
      <td>80M (<strong>~10x ↗</strong>)</td>
      <td>~4 hrs. Vacuum to process</td>
    </tr>
    <tr>
      <td>Memcached Instances</td>
      <td>21</td>
      <td>36 (<strong>1.7x ↗</strong>)</td>
      <td></td>
    </tr>
    <tr>
      <td>Memcached Connections</td>
      <td>9.3K</td>
      <td>~30K (<strong>3.2x ↗</strong>)</td>
      <td></td>
    </tr>
  </tbody>
</table>

<p>Traffic grows in the week before Christmas, but on Christmas day (December 25) it really takes a sharp upward trajectory. The peak load period lasts for more than 10 hours on Christmas Day, with the main DB receiving more than 100K TPS from 10:00 to 20:00 US Central Time.</p>

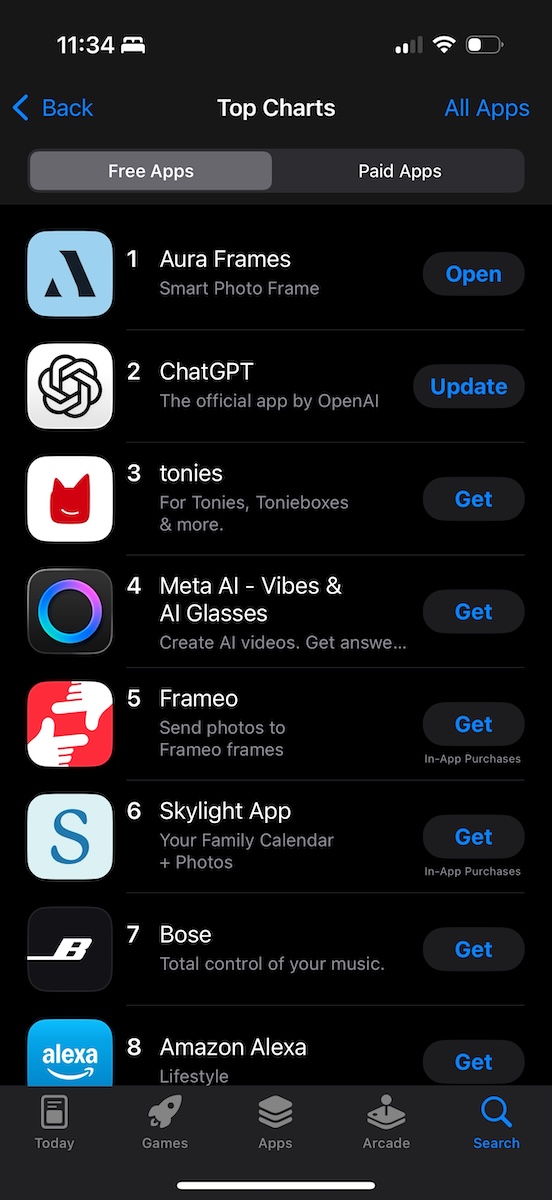
<p>Employees noticed the free Aura Frames iOS and Android apps moving up in the App Store ranks. Excitement built into the evening as the Aura Frames app moved into the top 10, top 5, and eventually reached the #1 rank. 🎉 I grabbed the screenshot below at around 11:30 PM CT December 25.</p>

<p><img src="/assets/images/aura-christmas-2025.jpg" alt="Aura Frames #1 App U.S. App Store Christmas Day" />
<br />
<small>Screenshot showing the Aura Frames app at the #1 rank in the U.S. Apple App Store</small></p>

<h2 id="switchover-to-new-dbs">Switchover to New DBs</h2>
<p>Let’s look at how the actual switchover happened. To switch over to new server instances, effectively “relocating” the tables, it was critical to not lose any write operations and to minimize user-facing downtime.</p>

<p>The steps were roughly as follows:</p>

<p><strong>Switchover preparation steps:</strong></p>
<ol>
  <li>For the primary database, create a new replica. It will need as much allocated space as the primary instance. Use physical replication.</li>
  <li>Set up AWS SSM parameters for the new database to be used by Ruby on Rails and PgBouncer.</li>
  <li>Create a new PgBouncer Auto Scaling Group (ASG) for the new DB. Set the SSM parameter to the network load balancer endpoint.</li>
  <li>Route application traffic through the new PgBouncer but have it continue to point at the original DB via an environment variable. Changing this param would be the sole change in the brief downtime period.</li>
</ol>

<p><strong>Switchover steps</strong>:</p>
<ol>
  <li>Bring all PgBouncer instances down (set ASG desired capacity to 0). No connectivity to DB now, no writes, fully down.</li>
  <li><a href="https://github.com/andyatkinson/pg_scripts/commit/f91b3855a81e1387f1f795d31a7ee8612a2fd394">Wait for replication lag to reach zero</a>. Promote the read replica to be a primary instance and wait for restart. Now it’s ready for traffic.</li>
  <li>Change the environment variable for PgBouncer described above to now point at the newly promoted primary instance.</li>
  <li>Bring PgBouncer instances back, setting the ASG desired capacity back to the original value.</li>
</ol>

<p>This process involved 5-10 minutes of user-facing downtime. We performed it in an off-peak time to minimize user-facing problems. Much of the frame activity occurs in the background, so the main impact is app use. Thanks to the customer support team for helping through this period internally and externally.</p>

<p><strong>Clean up of unneeded tables (due to physical replication):</strong>
As mentioned, due to the choice of physical replication, the majority of the tables on each instance were not needed and should be removed.</p>
<ol>
  <li>Drop the relocated tables from the main DB. Carefully review this with team members. Initially rename table, double check again, then drop the renamed table.</li>
  <li>Drop all unneeded tables replicated to the new whole-table shard DBs, which was most of them. This was partly scripted, and partly done manually for review and close monitoring.</li>
</ol>

<p>With all the unneeded tables cleaned up, we now had way more allocated space than needed. Provisioned space costs money. <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/blue-green-deployments.html">AWS launched Blue/Green Deployments</a> which has made it easier to replace instances with newly configured ones.</p>

<p>We set up a Blue/Green Deployment with the Blue as the newly promoted primary, and the Green would be a replacement instance with less space provisioned. Once replication was caught up, we cut over to Green. This process was smooth, and the result was right-sized space and cost.</p>

<h2 id="reflecting-back-on-the-plan">Reflecting back on the plan</h2>
<p>Some of the key contributors to successfully delivering this plan:</p>
<ol>
  <li>Having an extensive test suite running tests continuously (CI) catching regressions as code was refactored, along with PR reviews from long-tenured team members (invaluable)!</li>
  <li>As refactorings happened in large batches, slicing out smaller chunks as smaller PRs for easier review, and less risk as releases.</li>
  <li>Using a canary release process for widespread changes, released to a single instance vs. the whole fleet, which helped validate correctness with a small blast radius for issues that were difficult to verify in unit tests or outside of the production environment.</li>
  <li>Having an extensive pre-production load testing capability to validate the accumulated changes under high load, across most of the API surface area of the platform, drilling into identified performance regressions.</li>
  <li>Having a large AWS infrastructure budget 😅 to work with and strategic spending, in order to over-provision instance sizes and IOPS temporarily to gain more reliability, thanks in part to being a profitable company!</li>
  <li>Having comprehensive CloudWatch metrics, dashboards, web, and Postgres logs for analysis (<a href="https://aws.amazon.com/athena/">AWS Athena</a>), time-series metrics galore (formerly StatHat), and best-in-class Postgres observability (<a href="https://pganalyze.com">PgAnalyze</a>), to empower backend engineers with data access layer visibility.</li>
  <li>Running recent versions of Postgres and Ruby on Rails, unlocking useful features for bigger scale platforms.</li>
  <li>Experienced, long-tenured colleagues helping guide changes, focusing on high leverage opportunities, while generously sharing their knowledge and experience.</li>
</ol>

<h2 id="thank-you-and-looking-forward">Thank You and Looking Forward</h2>
<p>While the biggest payoff was seeing Postgres operate reliably through peak holiday traffic, it was equally rewarding to work with great engineers, be well supported by leadership, and benefit from years of accumulated scalability engineering all over the codebase. A special thank you to Josh, Ronnie, and EJ.</p>

<p>For 2026 we’re forming plans to further improve Postgres reliability, scalability, and cost efficiency.</p>

<p>If these types of posts are interesting to you, please consider subscribing to my blog or buying my book (details below).</p>

<p>If you’re an engineer reading this, thinking that these types of challenges would be fun to work on, please get in touch!</p>

<p>What’s next? Check out Part 2 which covers the Ruby on Rails side of the house.</p>

<p>And as always, please contact me with any questions or suggestions. Thanks for reading.</p>

<div style="
  max-width: 420px;
  margin: 2rem auto;
  padding: 1.25rem 1.5rem;
  background: #fff8b3;
  color: #333;
  border-left: 6px solid #f4d03f;
  border-radius: 3px;
  box-shadow: 3px 4px 10px rgba(0,0,0,0.15);
  font-family: sans-serif;
  transform: rotate(-1deg);
  position: relative;
">

  <div style="
    position: absolute;
    top: -10px;
    right: 20px;
    width: 70px;
    height: 22px;
    background: rgba(255,255,255,0.5);
    transform: rotate(4deg);
    border: 1px solid rgba(0,0,0,0.05);
  "></div>

  <strong style="display:block; margin-bottom:0.5rem;">
    Related Reading
  </strong>

  <p style="margin:0; line-height:1.5;">
    If you're interested in Ruby on Rails details for peak traffic on Christmas Day 2025,
    you may also enjoy
    <a href="how-aura-frames-scales-for-peak-load-ruby-on-rails" style="color:#005bbb; font-weight:600; text-decoration:none;">
    Scaling Rails at Aura Frames: Splitting to 8 Primaries and Reaching #1 in the App Store
    </a>.
  </p>
</div>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><category term="SQL" /><category term="Performance" /><summary type="html"><![CDATA[📌 Overview On Christmas Day 2024, Postgres infrastructure powering the Aura Frames API had problems under peak load, being unavailable for three hours and disrupting the experience for new customers. The team knew it would need improvements to handle the surge for Christmas 2025 and beyond. One year later, much of the resource intensive data access was reworked, the Postgres infrastructure was upsized, and this approach not only survived, but thrived, providing reliable service through the holiday season. The sum of Transactions Per Second (TPS) across the DBs peaked at 226,000, with more than 100K TPS sustained for 10 hours and repeating on multiple days after Christmas, with an average query time of 25 microseconds. The improved reliability meant customers could smoothly set up new frames and add photos, and they did it more than ever, with the Aura Frames app reaching #1 in U.S. and Canadian Apple and Android App Stores on Christmas Day. In this post we’ll look back at the months of planning and execution that went into achieving that outcome! A second post in this series will dig into the Ruby on Rails side, while this one will focus on Postgres.]]></summary></entry><entry><title type="html">Scaling Rails at Aura Frames: Splitting to 8 Primary DBs and Reaching #1 in the App Store</title><link href="https://andyatkinson.com/how-aura-frames-scales-for-peak-load-ruby-on-rails" rel="alternate" type="text/html" title="Scaling Rails at Aura Frames: Splitting to 8 Primary DBs and Reaching #1 in the App Store" /><published>2026-06-16T13:15:00+00:00</published><updated>2026-06-16T13:15:00+00:00</updated><id>https://andyatkinson.com/aura-frames-scaling-peak-load-ruby-on-rails</id><content type="html" xml:base="https://andyatkinson.com/how-aura-frames-scales-for-peak-load-ruby-on-rails"><![CDATA[<div class="summary-box">
<strong>📌 Overview</strong>
<p>Ruby on Rails has helped make it possible to scale out the database layer, meeting the demands of millions of Aura Frames customers enjoying their digital photo frames.</p>
<p>In late 2025, the team added additional primary databases to expand capacity for peak write and read load ahead of Christmas Day, the busiest day of the year for the company. Rails manages queries and schema changes for each primary database within the same codebase, and now with the additional capacity of many primary databases.</p>
<p>With 8 primary databases in total, each server instance can be vertically scaled ahead of peak load. When load returns to normal levels, instances are scaled down for cost savings.</p>
<p>The team leveraged native support for Multiple Databases and the <code>disable_joins: true</code> feature in Active Record, the ORM for Ruby on Rails. The disable_joins feature replaces SQL joins, issuing multiple SELECT statements to combine data in the application from different databases.</p>
<p>This post looks back at the technical details of that plan, as well as a variety of additional data layer scaling tactics, that culminated in a successful Christmas 2025 season, with peak U.S. and Canadian Apple App Store and Google Play Store rankings of #1.</p>
</div>

<h2 id="building-with-ruby-on-rails">Building With Ruby on Rails</h2>
<p>The Aura Frames platform has been built with Ruby on Rails since the beginning (more than 10 years ago!). Christmas 2025 was the busiest day of the year for the company and technical platform, serving a peak of 41 million API requests per hour (~11.4K requests per second), and processing a peak of 11.8 million background jobs per hour (~3300 jobs/second). On the database side, the sum of DB peak transactions per second (TPS) was 226K.</p>

<p>For an introduction to the Aura Frames company and products, and a deeper dive on the Postgres side of things, please check out <a href="/postgresql-rds-scaling-aws-christmas-day-peak#postgres-scaling-challenges-and-solutions">Part 1</a> of this series.</p>

<p><strong>Brief Recap from Part 1</strong>: Besides Ruby on Rails, Aura Frames uses PostgreSQL and AWS as key technologies.</p>

<p>Due to not being easily scalable horizontally for write operations, the database layer of PostgreSQL and Active Record often became a bottleneck. The team relied on vertically scaling the single primary server instance through Christmas of 2024.</p>

<p>The largest instance available for RDS at the time was the 48x family (192 vCPU, 1.5 TB RAM). Even with that jumbo-sized instance, the platform had reliability issues at peak load on Christmas 2024, driving a need to re-design for reliability improvements before Christmas 2025.</p>

<p>To handle greater levels of peak traffic reliably, the team decided to introduce application-level sharding using multiple primary databases. Several alternative approaches were considered. One goal was to leverage the existing code as much as possible, with minimal changes, and control the sharding distribution from the application level.</p>

<p>Another choice was whether to do traditional sharding at the row level, which distributes rows across multiple instances with databases having the same schema.</p>

<p>Fortunately Ruby on Rails was enhanced through more than 15 years of development, to support the needs of mature, scaled-up platforms with billions of rows and terabytes of data.</p>

<p>Before getting into the solution details, let’s look at some technical metrics from Christmas Day 2025 to help set context.</p>

<h2 id="technical-metrics">Technical Metrics</h2>
<p>On Christmas Day, the Aura Frames platform sees a 4-5x increase in load. Below are some HTTP and background jobs oriented metrics that Rails developers might find interesting.</p>
<table class="styled-table">
  <thead>
    <tr>
      <th>Metric</th>
      <th>Peak Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>HTTP Requests (1pm CT) at Load Balancer</td>
      <td>41 million requests/hour</td>
    </tr>
    <tr>
      <td>Average Response Time (10am to 9pm CT)</td>
      <td>650 milliseconds</td>
    </tr>
    <tr>
      <td>Cloudfront Global Requests</td>
      <td>33,675,000 requests/hour</td>
    </tr>
    <tr>
      <td>Image Processing EC2 Instances Count</td>
      <td>2990</td>
    </tr>
    <tr>
      <td>API EC2 Instances Count</td>
      <td>1849</td>
    </tr>
    <tr>
      <td>Background Job Processing Rate</td>
      <td>11.8 million jobs/hour (~3300 jobs/second)</td>
    </tr>
  </tbody>
</table>

<p>An exciting development for the team was seeing the free iOS and Android Aura Frames app rise in ranking throughout the day.</p>

<p>Late on Christmas Day, the app reached a peak rank of #1 among all free apps in the U.S. and Canadian App Stores, beating apps from big companies like OpenAI (ChatGPT) and Meta (Meta AI)!</p>

<p><img src="/assets/images/aura-christmas-2025.jpg" alt="Aura Frames #1 App U.S. App Store Christmas Day" />
<br />
<small>Screenshot showing the Aura Frames app at the #1 rank in the U.S. Apple App Store</small></p>

<p>Although there is a lot of interesting history from how the Aura Frames Ruby on Rails codebase evolved over a decade, in this post we’ll focus on changes made from mid-2025 to prepare for the surge of traffic on Christmas Day, as well as some general data layer scaling tactics.</p>

<h2 id="getting-started-with-multiple-databases">Getting Started With Multiple Databases</h2>
<p>From earlier, you learned that the Aura Frames platform was expanded from a single primary application DB to a total of 8.</p>

<p>To do that, heavy refactoring was performed to Active Record query layer code.</p>

<p>Queries for tables must not span a database boundary, and given some of the big tables were being moved to a new database, queries would break.</p>

<p>The development environment uses a Docker Postgres container. To keep things simple locally, all 8 databases run within the single container, but are spread out as separate Postgres databases. This meant that queries still “broke” (helpfully) when they spanned a database boundary, making them easy to find through unit tests and manual testing.</p>

<p>The gist of the changes were pretty straightforward: find breaking queries, unravel joins or other incompatible SQL, and change connections for those queries to access the correct database. Their query results were then passed around in Ruby as input to queries in other databases.</p>

<p>With hundreds of failing tests to sift through, the refactoring work took a long time as test failures were addressed one by one, but progress was easy to measure.</p>

<p>Eventually, weeks later, all tests were passing! The nice property about this design was the same query changes without SQL joins could be performed on the existing main DB, meaning the query changes were backwards compatible and could be rolled out on the single primary DB.</p>

<p>Some of the main changes were evaluating all Active Record relationships (<code class="language-plaintext highlighter-rouge">has_many</code>, <code class="language-plaintext highlighter-rouge">belongs_to</code>, etc.) and any subquery expressions or other incompatible code, and using <code class="language-plaintext highlighter-rouge">disable_joins: true</code>, removing subquery expressions and table references that spanned the boundary.</p>

<h2 id="from-sql-joins-to-multiple-selects">From SQL Joins to Multiple SELECTs</h2>
<p>The key parts of Ruby on Rails and Active Record that made this possible were Multiple Databases launched in 6.0, and the <code class="language-plaintext highlighter-rouge">disable_joins</code> feature for <code class="language-plaintext highlighter-rouge">has_many :through</code> and <code class="language-plaintext highlighter-rouge">has_one :through</code> relationships to query across databases <a href="https://www.bigbinary.com/blog/rails-7-adds-disable-joins-for-associations">launched in Rails 7.0</a> (2021).</p>

<p>Both of these were possible with custom code or third party library code (Ruby gems) prior to those releases, but having native support in Rails was a differentiator. Native support meant more real world use, bug fixes, improved documentation, and a longer term commitment to support.</p>

<p>Having <code class="language-plaintext highlighter-rouge">disable_joins</code> as a consistent pattern also helped with comprehension by the team, enabling “learn how it works once, then re-use it all over the codebase.”</p>

<p>Due to the increase in SELECT queries (and loss of join efficiency), the team had concerns about additional read query volume. Fortunately the team had a load testing tool in place and was able to verify through load testing that the additional read queries performed would not be a problem. With that said, over time we have replaced certain usages of disable_joins associations code with more targeted queries based on slow query logs or query cancellations. These queries are index supported, select minimal fields, and narrow ranges of rows by using batching.</p>

<p>Here’s a simple example using <code class="language-plaintext highlighter-rouge">Author</code> and <code class="language-plaintext highlighter-rouge">Post</code> models illustrating how <code class="language-plaintext highlighter-rouge">disable_joins: true</code> works:</p>
<ul>
  <li>Author (table_name: <code class="language-plaintext highlighter-rouge">authors</code>)</li>
  <li>Post (table_name: <code class="language-plaintext highlighter-rouge">posts</code>)</li>
  <li>AuthorPost (table_name: <code class="language-plaintext highlighter-rouge">author_posts</code>)</li>
</ul>

<p>Author model has an existing association defined as: <code class="language-plaintext highlighter-rouge">has_many :posts, through: :author_posts</code>.</p>

<p>To change this association, the <code class="language-plaintext highlighter-rouge">disable_joins: true</code> option is added like this:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">Author</span> <span class="o">&lt;</span> <span class="no">ApplicationRecord</span>
  <span class="n">has_many</span> <span class="ss">:posts</span><span class="p">,</span> <span class="ss">through: :author_posts</span><span class="p">,</span> <span class="ss">disable_joins: </span><span class="kp">true</span>
<span class="k">end</span>
</code></pre></div></div>

<p>What’s happening in SQL? Previously to get an Author’s posts, we’d query the <code class="language-plaintext highlighter-rouge">author_posts</code> table and join to the posts table on the author’s id.</p>

<p>Instead of that, there will now be two SELECT queries. One queries <code class="language-plaintext highlighter-rouge">author_posts</code> by <code class="language-plaintext highlighter-rouge">author_id</code> (an important foreign key column to index) to get post <code class="language-plaintext highlighter-rouge">id</code> values. Then a second query to the <code class="language-plaintext highlighter-rouge">posts</code> table by <code class="language-plaintext highlighter-rouge">id</code> (which uses the primary key index) gets the rows from the second table.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">select</span> <span class="o">*</span> <span class="k">from</span> <span class="n">author_posts</span> <span class="k">where</span> <span class="n">author_id</span> <span class="o">=</span> <span class="s1">'&lt;some id&gt;'</span><span class="p">;</span>
<span class="k">select</span> <span class="o">*</span> <span class="k">from</span> <span class="n">posts</span> <span class="k">where</span> <span class="n">id</span> <span class="k">IN</span> <span class="p">(</span><span class="o">?</span><span class="p">);</span>
</code></pre></div></div>

<p>Active Record handles the query change and presents the objects and collections in the same way to the developer.</p>

<p>Besides the query changes, what else needed to change?</p>

<h2 id="new-database-configuration">New Database Configuration</h2>
<p>Although we rolled out the query changes on the single primary DB architecture initially, that was intended to be temporary to further validate the changes without needing the new DBs in place.</p>

<p>The main plan was to use separate DB server instances, relocating the largest, busiest tables to their own instances in order to add more capacity and distribute the load.</p>

<p>For that we’d need to provision all the new DBs and connect to them from Rails. The first thing we needed was new YML config entries (<code class="language-plaintext highlighter-rouge">config/database.yml</code>) for each of them. The <a href="https://guides.rubyonrails.org/active_record_multiple_databases.html">Multiple Databases Documentation</a> uses “animals” and <code class="language-plaintext highlighter-rouge">my_animals_db</code> as the second primary database, so we’ll use that too for examples here.</p>

<p>This configuration is where we’ll store the Postgres connection string details and other application config like whether migrations are used, the schema dump path, etc.</p>

<p>Second, Active Record classes that previously inherited (OOP style) from <code class="language-plaintext highlighter-rouge">ApplicationRecord &lt; ActiveRecord::Base</code> would get a new parent class.</p>

<p>The new parent class would introduce the new DB config for <code class="language-plaintext highlighter-rouge">my_animals_db</code> and have the concept of “writing” and “reading” roles, shown below.</p>

<p>The new class is <code class="language-plaintext highlighter-rouge">AnimalsRecord</code>, which is a child class that inherits from <code class="language-plaintext highlighter-rouge">ApplicationRecord</code>. Extending this new parent class becomes the “interface” for any additional Active Record classes that wish to read or write to this new DB.</p>

<p>Examples from Rails’ Documentation:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">AnimalsRecord</span> <span class="o">&lt;</span> <span class="no">ApplicationRecord</span>
  <span class="nb">self</span><span class="p">.</span><span class="nf">abstract_class</span> <span class="o">=</span> <span class="kp">true</span>

  <span class="n">connects_to</span> <span class="ss">database: </span><span class="p">{</span>
    <span class="ss">writing: :animals</span><span class="p">,</span>
    <span class="ss">reading: :animals_replica</span>
  <span class="p">}</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Models/tables inherit from <code class="language-plaintext highlighter-rouge">AnimalsRecord</code> to work with that database. For example a <code class="language-plaintext highlighter-rouge">Dog</code> class:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">Dog</span> <span class="o">&lt;</span> <span class="no">AnimalsRecord</span>
  <span class="c1"># Talks automatically to the animals database.</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Eventually all new DBs and infra (PgBouncer, config vars) were set up, and could be switched over to. In the Rails app, the new DBs were named generically as they didn’t really correspond to a particular grouping of activity like a service, we just wanted a bunch of DBs with unique names.</p>

<p>The names of the DBs were part of the parent model, now the parent of the original model. Since the original model doesn’t change apart from having a new parent class, the new DB details are nicely encapsulated.</p>

<p><code class="language-plaintext highlighter-rouge">disable_joins</code> for <code class="language-plaintext highlighter-rouge">has_many :through</code> relationships ended up covering a lot of what was needed for query database separation, however there were other issues encountered on the way.</p>

<p>What were they?</p>

<h2 id="post-split-subquery-expressions">Post-split: Subquery Expressions</h2>
<p>Multiple tables exist in subquery expressions (aka “subqueries”), and these tables need to be in the same database for the statement to be valid.</p>

<p>When we found those, they needed to be restructured so that the DBs containing the table could be queried.</p>

<h2 id="post-split-exists-clauses">Post-split: EXISTS Clauses</h2>
<p>Post-split, the SQL below doesn’t work when <code class="language-plaintext highlighter-rouge">users</code> and <code class="language-plaintext highlighter-rouge">posts</code> (example models) aren’t in the same DB.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">users</span><span class="p">.</span><span class="o">*</span>
<span class="k">FROM</span> <span class="n">users</span>
<span class="k">WHERE</span> <span class="k">EXISTS</span> <span class="p">(</span>
  <span class="k">SELECT</span> <span class="mi">1</span> <span class="k">FROM</span> <span class="n">posts</span> <span class="k">WHERE</span> <span class="n">posts</span><span class="p">.</span><span class="n">user_id</span> <span class="o">=</span> <span class="n">users</span><span class="p">.</span><span class="n">id</span>
<span class="p">)</span>
</code></pre></div></div>

<h2 id="post-split-aggregating-and-grouping-multiple-tables">Post-split: Aggregating And Grouping Multiple Tables</h2>
<p>Post-split, there can be SQL fragments like this lurking, and this code needs to be changed when these tables are moved to separate databases.</p>

<p>SQL fragments are wrapped in <code class="language-plaintext highlighter-rouge">Arel.sql('')</code>.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Users</span><span class="p">.</span><span class="k">select</span><span class="p">(</span><span class="nv">"users.*, COUNT(posts.id) AS posts_count"</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="post-split-merging-scopes">Post-split: Merging Scopes</h2>
<p>If the tables for <code class="language-plaintext highlighter-rouge">User</code> and <code class="language-plaintext highlighter-rouge">Post</code> aren’t in the same database, we can’t merge a scope like this:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">User</span><span class="p">.</span><span class="n">merge</span><span class="p">(</span><span class="n">Post</span><span class="p">.</span><span class="n">recent</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="post-split-references-method">Post-split: References Method</h2>
<p><code class="language-plaintext highlighter-rouge">references</code> <a href="https://api.rubyonrails.org/classes/ActiveRecord/QueryMethods.html#method-i-references">API Documentation</a> which adds a SQL join, is used in conjunction with <code class="language-plaintext highlighter-rouge">includes()</code> to specify a table. However, this won’t work if the table is no longer in the same database.</p>

<h2 id="other-associations-has_and_belongs_to_many">Other Associations: has_and_belongs_to_many</h2>
<p>We did have a handful of <code class="language-plaintext highlighter-rouge">has_and_belongs_to_many</code> (HABTM) relationships (<a href="https://guides.rubyonrails.org/association_basics.html#has-and-belongs-to-many">API Documentation</a>). With these there is still a join table, but there is no Active Record model for it. The tables are also slim, no primary key or timestamp columns.</p>

<p>For HABTM relationships that would span a DB boundary, we decided to keep the table definitions as is, but introduce a model class and convert the code-level relationship from HABTM to <code class="language-plaintext highlighter-rouge">has_many :through</code> (HMT) so that we could use <code class="language-plaintext highlighter-rouge">disable_joins: true</code>.</p>

<p>Not all HABTM relationships were changed. When the HABTM relationship tables stayed in the same DB, we left those untouched.</p>

<p>Let’s shift gears into some general additional data layer scaling tactics.</p>

<h2 id="scaling-inserts-and-updates">Scaling Inserts and Updates</h2>
<p>With Multiple Databases and <code class="language-plaintext highlighter-rouge">disable_joins: true</code> covered, what other database scalability tactics are used?</p>

<p>Rails supports bulk inserts and <em>upserts</em> (either an insert or an update), however the helper method for mass-inserting data didn’t support what we needed. A limitation was that the ON CONFLICT clause couldn’t be customized for <code class="language-plaintext highlighter-rouge">insert_all()</code> (<a href="https://api.rubyonrails.org/v7.0/classes/ActiveRecord/Persistence/ClassMethods.html#method-i-insert_all">API Documentation</a>), which we needed.</p>

<p>For example attempting an INSERT and specifying the DO NOTHING option for handling unique constraint violations.</p>

<p>However, <code class="language-plaintext highlighter-rouge">upsert_all()</code> did get support for an <code class="language-plaintext highlighter-rouge">:on_duplicate</code> option.</p>

<p>Aura Frames has custom code for mass insert with direct control over the ON CONFLICT clause. Being able to batch inserts like this is a critical part of write scalability, consolidating the overhead of a batch of row insertions (e.g. 1000) into a single commit.</p>

<h2 id="scaling-reads-with-batching">Scaling Reads With Batching</h2>
<p>Rails supports batched read queries with a few Active Record methods: <code class="language-plaintext highlighter-rouge">find_each()</code>, <code class="language-plaintext highlighter-rouge">in_batches()</code>, and <code class="language-plaintext highlighter-rouge">find_in_batches()</code>.</p>

<p>Aura Frames has custom code for batched finding, specifying an arbitrary column on the table and a sorting direction.</p>

<p>Rails 6.1 did add support for <code class="language-plaintext highlighter-rouge">find_in_batches()</code> (<a href="https://api.rubyonrails.org/classes/ActiveRecord/Batches.html#method-i-find_in_batches">API Documentation</a> to control ordering, but only the primary key column was supported for ordering in ascending or descending order. We needed to order on arbitrary columns.</p>

<p>Chedli Bourguiba pointed out that Rails 8 added a <code class="language-plaintext highlighter-rouge">:cursor</code> option to support cursor pagination on a non-primary key column. See more at: <a href="https://jetthoughts.com/blog/ruby-on-rails-8-how-batch-with-custom-columns">JetThoughts - Ruby on Rails 8: How to Batch with Custom Columns</a>. I will be evaluating this in the future.</p>

<p>Reading a batch of rows using keyset pagination is a critical tactic for stable query execution times with varying result set sizes.</p>

<h2 id="scaling-reads-with-paginated-queries">Scaling Reads With Paginated Queries</h2>
<p>Aura Frames has custom code to perform keyset pagination, and generally does not use LIMIT and OFFSET style pagination built-in to Active Record. LIMIT and OFFSET pagination works for smaller amounts of data, but doesn’t scale well for deep pagination levels or when working with tables with billions of rows.</p>

<p>Keyset pagination with a high cardinality indexed column works well for fetching batches at a time, even when querying multi-billion row tables given they have good supporting indexes. The trick is to index a high cardinality column like a timestamp column, then filter on that with a WHERE clause and use LIMIT for a batch of rows. Note that timestamps can be duplicated, so you may need an additional column in that case.</p>

<p>An example fetch might be from a value with a <code class="language-plaintext highlighter-rouge">&gt;=</code> or <code class="language-plaintext highlighter-rouge">&lt;</code> operator and a LIMIT of 1000 as a batch size. The last accessed value then becomes the cursor position to start from.</p>

<p>This is an incredibly useful pattern and commonly used for API requests and other spots. To my knowledge Active Record doesn’t have a generic keyset style pagination helper.</p>

<h2 id="counter-cache-maintenance-for-frequently-updated-counters">Counter Cache Maintenance for Frequently Updated Counters</h2>
<p>Rails supports counter_cache columns (<a href="https://blog.appsignal.com/2018/06/19/activerecords-counter-cache.html">Blog post</a>) as a running counter, which is kept updated at write time.</p>

<p>Caveats are row churn and possible lock contention. Even updates of a single column create a new immutable row version behind the scenes. This adds dead row versions and more work for Vacuum, but this trade-off may be worth it.</p>

<p>Aura Frames does something similar but keeps counter cache columns in a separate but related table (plus counters in Memcached, see below). This reduces contention and places the churn more on a separate utility table.</p>

<h2 id="random-values-and-sampling">Random Values and Sampling</h2>
<p>Ordering by <code class="language-plaintext highlighter-rouge">RANDOM()</code> is slow. To avoid that, the Aura codebase uses TABLESAMPLE in Postgres (a contrib module which means no extensions are needed to install). A tablesample can be specified in a FROM clause (<a href="https://www.postgresql.org/docs/current/sql-select.html">Postgres Documentation</a>).</p>

<p>As a quick example from <a href="https://github.com/andyatkinson/rideshare">Rideshare</a> using the <code class="language-plaintext highlighter-rouge">Trip</code> model (<code class="language-plaintext highlighter-rouge">trips</code> table) as SQL:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">Trip</span><span class="p">.</span><span class="nf">connection</span><span class="p">.</span><span class="nf">select_all</span><span class="p">(</span><span class="s2">"SELECT * FROM trips TABLESAMPLE SYSTEM (10)"</span><span class="p">).</span><span class="nf">to_a</span>
</code></pre></div></div>

<p>Or as more conventional Active Record, requesting 5% of rows (1000 rows in this table):</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">Trip</span><span class="p">.</span><span class="nf">from</span><span class="p">(</span><span class="s2">"trips TABLESAMPLE SYSTEM (5)"</span><span class="p">).</span><span class="nf">count</span>
<span class="no">Trip</span><span class="p">.</span><span class="nf">from</span><span class="p">(</span><span class="s2">"trips TABLESAMPLE BERNOULLI (5)"</span><span class="p">).</span><span class="nf">count</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">sampling_method</code> options (built-in) above were <code class="language-plaintext highlighter-rouge">SYSTEM</code> and <code class="language-plaintext highlighter-rouge">BERNOULLI</code>. With 1000 rows in my local table, I should get about 50 rows by specifying 5%, but if you run this you’ll notice it’s only approximate. System is faster, but neither are fully accurate.</p>

<p>To get a precise amount of rows, enable the <code class="language-plaintext highlighter-rouge">tsm_system_rows</code> extension (<a href="https://www.postgresql.org/docs/current/tsm-system-rows.html">Postgres Documentation</a>) and specify a row count like this:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">Trip</span><span class="p">.</span><span class="nf">from</span><span class="p">(</span><span class="s2">"trips TABLESAMPLE SYSTEM_ROWS(50)"</span><span class="p">).</span><span class="nf">count</span>
  <span class="no">Trip</span> <span class="no">Count</span> <span class="p">(</span><span class="mf">11.9</span><span class="n">ms</span><span class="p">)</span>  <span class="no">SELECT</span> <span class="no">COUNT</span><span class="p">(</span><span class="o">*</span><span class="p">)</span> <span class="no">FROM</span> <span class="n">trips</span> <span class="no">TABLESAMPLE</span> <span class="no">SYSTEM_ROWS</span><span class="p">(</span><span class="mi">50</span><span class="p">)</span>
  <span class="o">=&gt;</span> <span class="mi">50</span>
</code></pre></div></div>
<p>You’ll notice above we got exactly 50 rows.</p>

<p>This tactic is used in various scripts and utilities where samples are needed from tables with millions of rows.</p>

<h2 id="using-memory-key-value-cache-stores">Using Memory Key Value Cache Stores</h2>
<p>Aura Frames makes use of the <a href="https://api.rubyonrails.org/classes/ActiveSupport/Cache/Store.html">Active Support Cache Store</a> via Memcached with HAProxy performing connection management.</p>

<p>Keeping certain values in Memcached is a key part of the scaling strategy, values like per-user counters, per-feature rate limiting, or cached environment variable values with TTLs.</p>

<h2 id="managing-schema-changes-with-multiple-databases">Managing Schema Changes with Multiple Databases</h2>
<p>With the 7 new DBs and configs in <code class="language-plaintext highlighter-rouge">config/database.yml</code>, we wanted to continue managing DDL changes via Rails Migrations like normal.</p>

<p>Fortunately this is supported. Each DB has its own <code class="language-plaintext highlighter-rouge">schema.rb</code>, a Ruby representation of the schema definition, a directory for migration files, and a place for config options.</p>

<p>Since each “new” database was not actually new, but based on an existing table definition, we started a new “first” migration for it using the existing table definition dumped via <code class="language-plaintext highlighter-rouge">pg_dump</code>.</p>

<p>This migration version was written to be <em>idempotent</em> meaning the table was added only when it didn’t exist. Initially the table would <em>not exist</em> in dev, test, and staging, but based on how we planned to migrate the tables in production, the table would exist there.</p>

<p><strong>Brief recap from Part 1</strong>: The plan was to use physical replication from the original primary instance to create a read only replica, then promote it to become a writer database. The replication was used as the means of moving all of the row data. This approach proved very reliable, but it did mean we had the former table copy on the original DB to clean up later, plus a ton of unneeded tables on all the new DBs to clean up (more on that in the other post).</p>

<p>Imagine the new migration version was <code class="language-plaintext highlighter-rouge">1234567890</code>. Once switched over, we’d <code class="language-plaintext highlighter-rouge">TRUNCATE</code> its <code class="language-plaintext highlighter-rouge">schema_migrations</code> table, then manually insert the new migration version into <code class="language-plaintext highlighter-rouge">schema_migrations</code> to keep the state consistent.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">insert</span> <span class="k">into</span> <span class="n">schema_migrations</span> <span class="p">(</span><span class="k">version</span><span class="p">)</span> <span class="k">values</span> <span class="p">(</span><span class="s1">'1234567890'</span><span class="p">);</span>
</code></pre></div></div>

<p>That was repeated for each new DB. Once that was done, schema management via migrations worked like normal, each seeded with their initial create table DDL as of that moment in time.</p>

<p>Migrations could be generated with their own directory for files, applied with <code class="language-plaintext highlighter-rouge">rails db:migrate</code> and <code class="language-plaintext highlighter-rouge">schema.rb</code> kept updated.</p>

<p>Some example commands:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rails g migration <span class="nt">--database</span> new_db

rails db:migrate <span class="nt">--database</span> my_animals_db
<span class="c"># or rails db:migrate for all databases</span>

rails db:schema:cache:dump
</code></pre></div></div>

<h2 id="wrap-up">Wrap Up</h2>
<p>Ruby on Rails has been a critical technology for Aura Frames to build with for more than a decade, enabling a small team to continually ship improvements to customers from the same codebase, with the expanded capacity of many primary databases.</p>

<p>Enhancements in the last handful of versions like Multiple Databases support, <code class="language-plaintext highlighter-rouge">disable_joins: true</code> for associations have helped the team expand DB capacity, and still ship quickly to continue to deliver higher performance, and more reliable solutions to customers.</p>

<p>If these types of posts are interesting to you, please consider subscribing to my blog or buying my book.</p>

<p>If you’re an engineer interested in working on these types of challenges, please get in touch.</p>

<p>Thanks for reading!</p>

<h3 id="updates">Updates</h3>
<p>2026-06-18 Chedli Bourguiba</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">:cursor</code> option for <a href="https://api.rubyonrails.org/classes/ActiveRecord/Batches.html#method-i-find_in_batches">find_in_batches()</a></li>
  <li>Replaced two instances of documentation with <a href="https://api.rubyonrails.org">Edge Rails documentation</a></li>
</ul>

<div style="
  max-width: 420px;
  margin: 2rem auto;
  padding: 1.25rem 1.5rem;
  background: #fff8b3;
  color: #333;
  border-left: 6px solid #f4d03f;
  border-radius: 3px;
  box-shadow: 3px 4px 10px rgba(0,0,0,0.15);
  font-family: sans-serif;
  transform: rotate(-1deg);
  position: relative;
">

  <div style="
    position: absolute;
    top: -10px;
    right: 20px;
    width: 70px;
    height: 22px;
    background: rgba(255,255,255,0.5);
    transform: rotate(4deg);
    border: 1px solid rgba(0,0,0,0.05);
  "></div>

  <strong style="display:block; margin-bottom:0.5rem;">
    Related Reading
  </strong>

  <p style="margin:0; line-height:1.5;">
    If you're interested in the PostgreSQL details for peak traffic on Christmas Day 2025,
    you may also enjoy
    <a href="https://andyatkinson.com/postgresql-rds-scaling-aws-christmas-day-peak" style="color:#005bbb; font-weight:600; text-decoration:none;">
      From Christmas Outage to #1 App Store Ranking: An Aura Frames Postgres Scaling Retrospective
    </a>.
  </p>
</div>]]></content><author><name>Andrew Atkinson</name></author><category term="Ruby on Rails" /><category term="Ruby" /><category term="PostgreSQL" /><category term="Performance" /><summary type="html"><![CDATA[📌 Overview Ruby on Rails has helped make it possible to scale out the database layer, meeting the demands of millions of Aura Frames customers enjoying their digital photo frames. In late 2025, the team added additional primary databases to expand capacity for peak write and read load ahead of Christmas Day, the busiest day of the year for the company. Rails manages queries and schema changes for each primary database within the same codebase, and now with the additional capacity of many primary databases. With 8 primary databases in total, each server instance can be vertically scaled ahead of peak load. When load returns to normal levels, instances are scaled down for cost savings. The team leveraged native support for Multiple Databases and the disable_joins: true feature in Active Record, the ORM for Ruby on Rails. The disable_joins feature replaces SQL joins, issuing multiple SELECT statements to combine data in the application from different databases. This post looks back at the technical details of that plan, as well as a variety of additional data layer scaling tactics, that culminated in a successful Christmas 2025 season, with peak U.S. and Canadian Apple App Store and Google Play Store rankings of #1.]]></summary></entry><entry><title type="html">Beta Testing PostgreSQL 19 With Docker</title><link href="https://andyatkinson.com/postgresql-beta-testing-docker" rel="alternate" type="text/html" title="Beta Testing PostgreSQL 19 With Docker" /><published>2026-06-05T20:15:00+00:00</published><updated>2026-06-05T20:15:00+00:00</updated><id>https://andyatkinson.com/postgresql-beta-docker-testing</id><content type="html" xml:base="https://andyatkinson.com/postgresql-beta-testing-docker"><![CDATA[<p>The Postgres community releases Beta versions, and with Docker it’s been easier than ever to configure pre-release versions to use and test.</p>

<p>With the <a href="https://www.postgresql.org/about/news/postgresql-19-beta-1-released-3313/">recent announcement of PostgreSQL 19 Beta 1</a>, it’s a great time to do that. Let’s get an instance up and running and test some of the new capabilities in Postgres 19.</p>

<h2 id="pre-release-versions-of-postgres-with-docker">Pre-Release Versions of Postgres with Docker</h2>
<p>First, you’ll need to install <a href="https://www.docker.com">Docker</a> for your OS! Grab the version needed for your OS and processor architecture, for example ARM or AMD/Intel/x86.</p>

<p>On MacOS run <code class="language-plaintext highlighter-rouge">uname -m</code> or <code class="language-plaintext highlighter-rouge">sw_vers</code> in your Terminal to learn more about your hardware details.</p>

<p>For Windows check <a href="https://docs.docker.com/desktop/setup/install/windows-install/">Install Docker Desktop on Windows</a></p>

<h2 id="building-and-running">Building and Running</h2>
<p><a href="https://hub.docker.com/_/postgres">Official Postgres images</a> for Docker Postgres are limited to fully released versions.</p>

<p>Fortunately <a href="https://github.com/yosifkit">@yosifkit</a> created a PR to add 19 Beta 1 (merged by @<a href="https://github.com/tianon">tianon</a>) with instructions for how to use <code class="language-plaintext highlighter-rouge">docker buildx</code> to build pre-release versions.</p>

<p>This command downloads and builds <code class="language-plaintext highlighter-rouge">postgres:19beta1-trixie</code>:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker buildx build <span class="nt">-t</span> postgres:19beta1-trixie <span class="se">\</span>
    <span class="s1">'https://github.com/infosiftr/postgres.git#19-rc:19/trixie'</span>
</code></pre></div></div>

<p>With that built, I could invoke <code class="language-plaintext highlighter-rouge">docker run</code> with <code class="language-plaintext highlighter-rouge">postgres:19beta1-trixie</code>. I named mine <code class="language-plaintext highlighter-rouge">pg19</code>.</p>

<p>I also passed the env vars below based on how I run other Docker Postgres containers (these options may not be necessary).</p>

<p>The final command:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker run <span class="se">\</span>
<span class="nt">--name</span> pg19 <span class="se">\</span>
<span class="nt">--env</span> <span class="nv">POSTGRES_USER</span><span class="o">=</span>postgres <span class="se">\</span>
<span class="nt">--env</span> <span class="nv">POSTGRES_PASSWORD</span><span class="o">=</span>postgres <span class="se">\</span>
<span class="nt">--detach</span> postgres:19beta1-trixie
</code></pre></div></div>

<p>To check if it’s running, I run <code class="language-plaintext highlighter-rouge">docker ps -a</code>. For logs I’d run: <code class="language-plaintext highlighter-rouge">docker logs -f postgres:19beta1-trixie</code>.</p>

<h2 id="released-versions">Released Versions</h2>
<p>Shortly after writing the initial post on June 5th, the <code class="language-plaintext highlighter-rouge">postgres:beta1</code> image became available for download without any special steps:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker run <span class="nt">--detach</span> postgres:19beta1
</code></pre></div></div>

<h2 id="connect-via-psql">Connect via psql</h2>
<p>The container is running and the logs have what we want: “database system is ready to accept connections”.</p>

<p>Let’s connect to the <code class="language-plaintext highlighter-rouge">postgres</code> database using psql on the container:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker container <span class="nb">exec</span> <span class="nt">-it</span> pg19 psql <span class="nt">-U</span> postgres
</code></pre></div></div>

<p>We should see output like showing version 19:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>psql (19beta1 (Debian 19~beta1-1.pgdg13+1))
Type "help" for help.
</code></pre></div></div>

<h2 id="new-feature-testing-in-19">New Feature Testing in 19</h2>
<p>Great. Let’s try out some things in 19.</p>

<p>19 Added a new system view for checking out locks. Let’s try it out:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">select</span> <span class="o">*</span> <span class="k">from</span> <span class="n">pg_stat_lock</span><span class="p">;</span>
</code></pre></div></div>

<p>We get a lot of new data like <code class="language-plaintext highlighter-rouge">waits</code> counts, <code class="language-plaintext highlighter-rouge">wait_time</code> and more.</p>

<p>What about the new <code class="language-plaintext highlighter-rouge">pg_plan_advice</code> extension? First let’s load it and then create a table <code class="language-plaintext highlighter-rouge">t</code> to experiment with:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">LOAD</span> <span class="s1">'pg_plan_advice'</span><span class="p">;</span>
<span class="n">postgres</span><span class="o">=#</span> <span class="k">create</span> <span class="k">table</span> <span class="n">t</span> <span class="p">(</span><span class="n">id</span> <span class="nb">int</span><span class="p">);</span>
</code></pre></div></div>

<p>With that in place we can show the output via <code class="language-plaintext highlighter-rouge">EXPLAIN</code> with a new <code class="language-plaintext highlighter-rouge">PLAN_ADVICE</code> parameter:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">EXPLAIN</span> <span class="p">(</span><span class="n">PLAN_ADVICE</span><span class="p">)</span> <span class="k">SELECT</span> <span class="o">*</span> <span class="k">FROM</span> <span class="n">t</span><span class="p">;</span>
                     <span class="n">QUERY</span> <span class="n">PLAN</span>
<span class="c1">-----------------------------------------------------</span>
 <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">t</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">35</span><span class="p">.</span><span class="mi">50</span> <span class="k">rows</span><span class="o">=</span><span class="mi">2550</span> <span class="n">width</span><span class="o">=</span><span class="mi">4</span><span class="p">)</span>
 <span class="k">Generated</span> <span class="n">Plan</span> <span class="n">Advice</span><span class="p">:</span>
   <span class="n">SEQ_SCAN</span><span class="p">(</span><span class="n">t</span><span class="p">)</span>
   <span class="n">NO_GATHER</span><span class="p">(</span><span class="n">t</span><span class="p">)</span>
<span class="p">(</span><span class="mi">4</span> <span class="k">rows</span><span class="p">)</span>
</code></pre></div></div>

<p>I wonder why the rows estimate is 2550 by default? Let’s run <code class="language-plaintext highlighter-rouge">analyze t;</code>.</p>

<p>After doing that, it looks more sensible with a <code class="language-plaintext highlighter-rouge">rows</code> estimate of 1:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">EXPLAIN</span> <span class="p">(</span><span class="n">PLAN_ADVICE</span><span class="p">)</span> <span class="k">SELECT</span> <span class="o">*</span> <span class="k">FROM</span> <span class="n">t</span><span class="p">;</span>
                   <span class="n">QUERY</span> <span class="n">PLAN</span>
<span class="c1">-------------------------------------------------</span>
 <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">t</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">4</span><span class="p">)</span>
 <span class="k">Generated</span> <span class="n">Plan</span> <span class="n">Advice</span><span class="p">:</span>
   <span class="n">SEQ_SCAN</span><span class="p">(</span><span class="n">t</span><span class="p">)</span>
   <span class="n">NO_GATHER</span><span class="p">(</span><span class="n">t</span><span class="p">)</span>
<span class="p">(</span><span class="mi">4</span> <span class="k">rows</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="additions-to-pg_stat_statements">Additions to pg_stat_statements</h2>
<p>The extension <code class="language-plaintext highlighter-rouge">pg_stat_statements</code> gained new capabilities in 19.</p>

<p>Let’s try it out:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">select</span> <span class="o">*</span> <span class="k">from</span> <span class="n">pg_stat_statements</span><span class="p">;</span>
<span class="n">ERROR</span><span class="p">:</span>  <span class="n">relation</span> <span class="nv">"pg_stat_statements"</span> <span class="n">does</span> <span class="k">not</span> <span class="n">exist</span>
</code></pre></div></div>

<p>Oops, we need to add it to <code class="language-plaintext highlighter-rouge">shared_preload_libraries</code> first. We can see that’s currently not the case:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">show</span> <span class="n">shared_preload_libraries</span><span class="p">;</span>
 <span class="n">shared_preload_libraries</span>
<span class="c1">--------------------------</span>

<span class="p">(</span><span class="mi">1</span> <span class="k">row</span><span class="p">)</span>
</code></pre></div></div>

<p>One way to do that with <code class="language-plaintext highlighter-rouge">docker run</code> is the <code class="language-plaintext highlighter-rouge">-c</code> parameter as follows:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker run <span class="se">\</span>
<span class="nt">--name</span> pg19 <span class="se">\</span>
<span class="nt">--env</span> <span class="nv">POSTGRES_USER</span><span class="o">=</span>postgres <span class="se">\</span>
<span class="nt">--env</span> <span class="nv">POSTGRES_PASSWORD</span><span class="o">=</span>postgres <span class="se">\</span>
<span class="nt">--detach</span> postgres:19beta1-trixie <span class="se">\</span>
<span class="nt">-c</span> <span class="nv">shared_preload_libraries</span><span class="o">=</span>pg_stat_statements
</code></pre></div></div>

<p>Now we see what we want in <code class="language-plaintext highlighter-rouge">shared_preload_libraries</code>:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">show</span> <span class="n">shared_preload_libraries</span><span class="p">;</span>
 <span class="n">shared_preload_libraries</span>
<span class="c1">--------------------------</span>
 <span class="n">pg_stat_statements</span>
<span class="p">(</span><span class="mi">1</span> <span class="k">row</span><span class="p">)</span>
</code></pre></div></div>

<p>We have not yet enabled the extension though given <code class="language-plaintext highlighter-rouge">\dx</code> doesn’t list it. Let’s do that:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">psql</span><span class="o">&gt;</span> <span class="k">create</span> <span class="n">extension</span> <span class="n">if</span> <span class="k">not</span> <span class="k">exists</span> <span class="n">pg_stat_statements</span><span class="p">;</span>
</code></pre></div></div>
<p>Now <code class="language-plaintext highlighter-rouge">\dx</code> shows it, and we’re ready to query it.</p>

<p>One of the additions is tracking the use of prepared statements. Let’s create a basic table and prepared statement.</p>

<p>Create table again if needed:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">create</span> <span class="k">table</span> <span class="n">if</span> <span class="k">not</span> <span class="k">exists</span> <span class="n">t</span> <span class="p">(</span><span class="n">id</span> <span class="nb">int</span><span class="p">);</span>
</code></pre></div></div>

<p>Create a simple prepared statement <code class="language-plaintext highlighter-rouge">get_t</code> and execute it. The goal here is for <code class="language-plaintext highlighter-rouge">pg_stat_statements</code> to increment the <code class="language-plaintext highlighter-rouge">generic_plan_calls</code> field.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">PREPARE</span> <span class="n">get_t</span> <span class="k">AS</span>
<span class="k">SELECT</span> <span class="o">*</span>
<span class="k">FROM</span> <span class="n">t</span><span class="p">;</span>
</code></pre></div></div>

<p>Now let’s execute it:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">EXECUTE</span> <span class="n">get_t</span><span class="p">;</span>
</code></pre></div></div>

<p>Did it work?</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">postgres</span><span class="o">=#</span> <span class="k">select</span> <span class="k">left</span><span class="p">(</span><span class="n">query</span><span class="p">,</span><span class="mi">100</span><span class="p">),</span><span class="n">generic_plan_calls</span> <span class="k">from</span> <span class="n">pg_stat_statements</span> <span class="k">limit</span> <span class="mi">1</span><span class="p">;</span>
       <span class="k">left</span>       <span class="o">|</span> <span class="n">generic_plan_calls</span>
<span class="c1">------------------+--------------------</span>
 <span class="k">PREPARE</span> <span class="n">get_t</span> <span class="k">AS</span><span class="o">+|</span>                  <span class="mi">1</span>
 <span class="k">SELECT</span> <span class="o">*</span>        <span class="o">+|</span>
 <span class="k">FROM</span> <span class="n">t</span>           <span class="o">|</span>
</code></pre></div></div>

<p>It worked! We see <code class="language-plaintext highlighter-rouge">generic_plan_calls</code> was incremented.</p>

<p>This looks very useful to monitor the use of prepared statements.</p>

<h2 id="repack-concurrently-for-tables">Repack Concurrently for Tables</h2>
<p>We’ve had the ability to use <code class="language-plaintext highlighter-rouge">reindex concurrently</code> to rebuild indexes since Postgres 12, but have lacked the ability to rebuild tables.</p>

<p>That changes in 19, with the introduction of <code class="language-plaintext highlighter-rouge">repack concurrently</code> for tables.</p>

<p>Let’s try it out quick and bloat a table by updating every row. We’ll compare the size before and after repacking it.</p>

<p>Run these examples using psql:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">create</span> <span class="k">table</span> <span class="n">bloat</span> <span class="p">(</span><span class="n">id</span> <span class="nb">int</span> <span class="k">primary</span> <span class="k">key</span><span class="p">);</span>
<span class="k">CREATE</span> <span class="k">TABLE</span>

<span class="k">insert</span> <span class="k">into</span> <span class="n">bloat</span> <span class="p">(</span><span class="n">id</span><span class="p">)</span> <span class="k">select</span> <span class="n">i</span> <span class="k">from</span> <span class="n">generate_series</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="mi">1</span><span class="n">_000_000</span><span class="p">)</span> <span class="k">as</span> <span class="n">t</span><span class="p">(</span><span class="n">i</span><span class="p">);</span>
<span class="k">INSERT</span> <span class="mi">0</span> <span class="mi">1000000</span>

<span class="k">SELECT</span> <span class="n">pg_size_pretty</span><span class="p">(</span><span class="n">pg_total_relation_size</span><span class="p">(</span><span class="s1">'bloat'</span><span class="p">));</span>
 <span class="n">pg_size_pretty</span>
<span class="c1">----------------</span>
 <span class="mi">56</span> <span class="n">MB</span>

<span class="k">analyze</span> <span class="n">bloat</span><span class="p">;</span>
<span class="k">ANALYZE</span>

<span class="c1">-- Update every row</span>
<span class="k">update</span> <span class="n">bloat</span> <span class="k">set</span> <span class="n">id</span> <span class="o">=</span> <span class="n">id</span><span class="p">;</span>
<span class="k">UPDATE</span> <span class="mi">1000000</span>

<span class="k">analyze</span> <span class="n">bloat</span><span class="p">;</span>
<span class="k">ANALYZE</span>

<span class="c1">-- The table size has doubled</span>
<span class="k">SELECT</span> <span class="n">pg_size_pretty</span><span class="p">(</span><span class="n">pg_total_relation_size</span><span class="p">(</span><span class="s1">'bloat'</span><span class="p">));</span>
 <span class="n">pg_size_pretty</span>
<span class="c1">----------------</span>
 <span class="mi">112</span> <span class="n">MB</span>

<span class="n">repack</span> <span class="p">(</span><span class="n">concurrently</span><span class="p">,</span> <span class="k">verbose</span><span class="p">)</span> <span class="n">bloat</span><span class="p">;</span>
<span class="n">INFO</span><span class="p">:</span>  <span class="n">repacking</span> <span class="nv">"public.bloat"</span> <span class="k">in</span> <span class="n">physical</span> <span class="k">order</span>
<span class="n">INFO</span><span class="p">:</span>  <span class="nv">"public.bloat"</span><span class="p">:</span> <span class="k">found</span> <span class="mi">0</span> <span class="n">removable</span><span class="p">,</span> <span class="mi">1000000</span> <span class="n">nonremovable</span> <span class="k">row</span> <span class="n">versions</span> <span class="k">in</span> <span class="mi">8850</span> <span class="n">pages</span>
<span class="n">DETAIL</span><span class="p">:</span>  <span class="mi">0</span> <span class="n">dead</span> <span class="k">row</span> <span class="n">versions</span> <span class="n">cannot</span> <span class="n">be</span> <span class="n">removed</span> <span class="n">yet</span><span class="p">.</span>
<span class="n">CPU</span><span class="p">:</span> <span class="k">user</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">21</span> <span class="n">s</span><span class="p">,</span> <span class="k">system</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">04</span> <span class="n">s</span><span class="p">,</span> <span class="n">elapsed</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">28</span> <span class="n">s</span><span class="p">.</span>
<span class="n">REPACK</span>

<span class="c1">-- Returns to original table size</span>
<span class="k">SELECT</span> <span class="n">pg_size_pretty</span><span class="p">(</span><span class="n">pg_total_relation_size</span><span class="p">(</span><span class="s1">'bloat'</span><span class="p">));</span>
 <span class="n">pg_size_pretty</span>
<span class="c1">----------------</span>
 <span class="mi">56</span> <span class="n">MB</span>
</code></pre></div></div>

<p>Very useful! Check out the <a href="https://www.postgresql.org/docs/19/sql-repack.html">repack</a> documentation for more info.</p>

<h2 id="wrapping-up">Wrapping Up</h2>
<p>Please give this a shot and experiment with new features in Postgres 19!</p>

<ul>
  <li><a href="https://github.com/docker-library/postgres/pull/1415">Add 19.x builds (currently beta 1)</a></li>
</ul>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><summary type="html"><![CDATA[The Postgres community releases Beta versions, and with Docker it’s been easier than ever to configure pre-release versions to use and test.]]></summary></entry><entry><title type="html">What are SLRUs and MultiXacts in Postgres? What can go wrong?</title><link href="https://andyatkinson.com/postgresql-slru-multixact-what-can-go-wrong" rel="alternate" type="text/html" title="What are SLRUs and MultiXacts in Postgres? What can go wrong?" /><published>2025-09-25T11:15:00+00:00</published><updated>2025-09-25T11:15:00+00:00</updated><id>https://andyatkinson.com/postgresql-slru-multixact-what-can-go-wrong</id><content type="html" xml:base="https://andyatkinson.com/postgresql-slru-multixact-what-can-go-wrong"><![CDATA[<p>In this post we’ll cover two types of Postgres internals.</p>

<p>The first internal item is an “SLRU.” The acronym stands for “simple least recently used.” The LRU portion refers to caches and how they work, and SLRUs in Postgres are a collection of these caches.</p>

<p>SLRUs are small in-memory item stores. Since they need to persist across restarts, they’re also saved into files on disk. Álvaro Herrera<sup id="fnref:alvaro" role="doc-noteref"><a href="#fn:alvaro" class="footnote" rel="footnote">1</a></sup> calls SLRUs “poorly named for a user-facing feature.” If they’re internal, why are they worth knowing about as Postgres users?</p>

<p>They’re worth knowing about because there can be a couple of possible failure points with them, due their fixed size. We’ll look at those later in this post.</p>

<p>Before getting into that, let’s cover some basics about what they are and look at a specific type.</p>

<h2 id="main-purpose-of-slrus">Main purpose of SLRUs</h2>
<p>The main purpose of SLRUs is to track metadata about Postgres transactions.</p>

<p>SLRUs are a general mechanism used by multiple types. Like a lot of things in Postgres, the SLRU system is extensible which means extensions can create new types.</p>

<p>The “least recently used” aspect might be recognizable from cache systems. LRU refers to how the oldest items are evicted from the cache when it’s full, and newer items take their place.
This is because the cache has a fixed amount of space (measured in 8KB pages) and thus can only store a fixed amount of items.</p>

<p>Old SLRU cache items are periodically cleaned up by the Vacuum process.</p>

<h2 id="what-about-the-buffer-cache">What about the buffer cache?</h2>
<p>The buffer cache (sized by configuring <a href="https://www.postgresql.org/docs/current/runtime-config-resource.html">shared_buffers</a>) is another form of cache in Postgres. Thomas Munro proposed unifying the SLRUs and buffer cache mechanisms.</p>

<p>However, as of Postgres 17 and the upcoming 18 release (Update: PostgreSQL 18 released September 25, 2025), SLRUs are still their own distinct type of cache.</p>

<p>What types of data is stored in SLRUs?</p>

<h2 id="what-type-of-data-is-tracked-in-slrus">What type of data is tracked in SLRUs?</h2>
<p>Transactions are a core concept for relational databases like Postgres. Transactions are abbreviated “Xact,” and Xacts are one of the types of data stored in SLRUs.</p>

<p>Besides regular transactions, there are variations of transactions. Transactions can be created inside other transactions, which are called “nested transactions.”</p>

<p>Whether parent or nested transactions, they each get their own 32-bit integer identifier once they begin modifying something, and these are all tracked while they’re in use. The <a href="https://www.postgresql.org/docs/current/sql-savepoint.html">SAVEPOINT</a> keyword (blog post: <a href="https://andyatkinson.com/blog/2024/07/22/postgresql-savepoints">You make a good point! — PostgreSQL Savepoints</a> saves the incremental status for a transaction.</p>

<p>Another variation of a transaction is a “multi-transaction,” (multiple transactions in a group) or “MultiXact” in Postgres speak.</p>

<h2 id="what-are-multixacts">What are MultiXacts?</h2>
<p>A MultiXact gets a separate number from the transaction identifier. I think of it like a “group” number. The group might be related to a table row, but each transaction in the group is doing something different. Think of multiple transactions all doing a foreign key referential integrity check on the same referenced primary key.</p>

<p>Here’s a definition of MultiXact IDs:</p>
<blockquote>
  <p>A MultiXact ID is a secondary data structure that tracks multiple transactions holding locks on the same row.</p>
</blockquote>

<p>When MultiXacts are created, their identifier is stored in tuple header info, replacing the transaction id that would normally be stored in the tuple header.</p>

<p>As this buttondown blog post (“Notes on some PostgreSQL implementation details”)<sup id="fnref:buttondown" role="doc-noteref"><a href="#fn:buttondown" class="footnote" rel="footnote">2</a></sup> describes, the tuple (row version) header has a small fixed size. The MultiXact id replaces the transaction id using the same size identifier (but a different one), to keep the tuple header size small (as opposed to adding another identifier).</p>

<p>Transaction IDs and MultiXact IDs are both represented as a circular 32-bit integer space, meaning it’s possible to store a max of around ~4 billion values (See: <a href="https://www.postgresql.org/docs/current/transaction-id.html">Transactions and Identifiers</a>, half in the past, half in the future.</p>

<p>We can get the current transaction id value by running <code class="language-plaintext highlighter-rouge">select pg_current_xact_id();</code>.</p>

<p>What do we mean by transaction metadata? One example is with nested transactions, the parent transaction, the “creator”.</p>

<p>If you’d like to read how AWS introduces MultiXacts, check out this post. This post describes them: What are MultiXacts?
<a href="https://aws.amazon.com/blogs/database/multixacts-in-postgresql-usage-side-effects-and-monitoring/">https://aws.amazon.com/blogs/database/multixacts-in-postgresql-usage-side-effects-and-monitoring/</a></p>

<p>When do MultiXacts get created?</p>

<h2 id="when-do-multixacts-get-created">When do MultiXacts get created?</h2>
<p>MultiXacts get created only for certain types of DML operations and for certain schema definitions. In other words, it’s possible that your particular Postgres database workload does not create MultiXacts at all, or it’s possible they’re heavily used.
Let’s look at what creates MultiXacts:</p>
<ul>
  <li>Foreign key constraint enforcement</li>
  <li><code class="language-plaintext highlighter-rouge">SELECT FOR SHARE</code></li>
</ul>

<p>If you use no foreign key constraints or your application (or ORM) never creates <code class="language-plaintext highlighter-rouge">SELECT FOR SHARE</code>, then your Postgres database may have no MultiXacts.</p>

<p>Let’s go back to SLRUs.</p>

<h2 id="more-about-slrus">More about SLRUs</h2>
<p>SLRUs have a fixed size (prior to Postgres 17) measured in pages. When items are evicted from the SLRU cache, a <a href="https://www.interdb.jp/pg/pgsql08/01.html">page replacement</a> occurs.</p>

<p>The page being replaced is called the “victim” page and Postgres must do a little work to find a victim page.
Since SLRUs survive Postgres restarts, they’re <a href="http://www.postgresql.org/docs/17/storage-file-layout.html#PGDATA-CONTENTS-TABLE">saved in files in the PGDATA directory</a>.</p>

<p>The directory name will depend on the SLRU type. For example for MultiXacts, the directory name is <code class="language-plaintext highlighter-rouge">pg_multixact</code>. SLRU buffer pages are written to the WAL and to disk, meaning that if the primary instance fails, the state can be recovered.</p>

<p>See the <code class="language-plaintext highlighter-rouge">slru.c</code> <code class="language-plaintext highlighter-rouge">SlruPhysicalWritePage</code> function comments which describes writing WAL and writing out data:</p>
<pre>
Honor the write-WAL-before-data rule, if appropriate, so that we do not
write out data before associated WAL records.
</pre>

<p>Each SLRU instance implements a circular buffer of pages in shared memory, evicting the least recently used pages. A circular buffer is another interesting Postgres internal concept but is beyond the scope of this post.
How can we observe what’s happening with SLRUs?</p>

<h2 id="using-pg_stat_slru">Using pg_stat_slru</h2>
<p>Since Postgres 13, we have the system view “pg_stat_slru” to query to inspect cumulative statistics about the SLRUs.
<a href="https://www.postgresql.org/docs/current/monitoring-stats.html#PG-STAT-SLRU-VIEW">https://www.postgresql.org/docs/current/monitoring-stats.html#PG-STAT-SLRU-VIEW</a>
To list only the names of the built-in SLRU types:</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">select</span> <span class="n">name</span> <span class="k">from</span> <span class="n">pg_stat_slru</span><span class="p">;</span>
      <span class="n">name</span>
<span class="c1">-----------------</span>
 <span class="n">CommitTs</span>
 <span class="n">MultiXactMember</span>
 <span class="n">MultiXactOffset</span>
 <span class="k">Notify</span>
 <span class="nb">Serial</span>
 <span class="n">Subtrans</span>
 <span class="n">Xact</span>
 <span class="n">Other</span>
</code></pre></div></div>

<p>To determine if our system is creating MultiXact SLRUs, we can query the pg_stat_slru view. We’d see non-zero numbers in rows below when the system is creating SLRU data.</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">select</span> <span class="n">name</span> <span class="k">from</span> <span class="n">pg_stat_slru</span><span class="p">;</span>
                     <span class="k">View</span> <span class="nv">"pg_catalog.pg_stat_slru"</span>
    <span class="k">Column</span>    <span class="o">|</span>           <span class="k">Type</span>           <span class="o">|</span> <span class="k">Collation</span> <span class="o">|</span> <span class="k">Nullable</span> <span class="o">|</span> <span class="k">Default</span> 
<span class="c1">--------------+--------------------------+-----------+----------+---------</span>
 <span class="n">name</span>         <span class="o">|</span> <span class="nb">text</span>                     <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">blks_zeroed</span>  <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">blks_hit</span>     <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">blks_read</span>    <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">blks_written</span> <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">blks_exists</span>  <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">flushes</span>      <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">truncates</span>    <span class="o">|</span> <span class="nb">bigint</span>                   <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span> 
 <span class="n">stats_reset</span>  <span class="o">|</span> <span class="nb">timestamp</span> <span class="k">with</span> <span class="nb">time</span> <span class="k">zone</span> <span class="o">|</span>           <span class="o">|</span>          <span class="o">|</span>
</code></pre></div></div>

<p>To look at the <code class="language-plaintext highlighter-rouge">pg_xact</code> SLRU:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">select</span> <span class="o">*</span> <span class="k">from</span> <span class="n">pg_stat_slru</span> <span class="k">where</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'Xact'</span><span class="p">;</span>
 <span class="n">name</span> <span class="o">|</span> <span class="n">blks_zeroed</span> <span class="o">|</span> <span class="n">blks_hit</span> <span class="o">|</span> <span class="n">blks_read</span> <span class="o">|</span> <span class="n">blks_written</span> <span class="o">|</span> <span class="n">blks_exists</span> <span class="o">|</span> <span class="n">flushes</span> <span class="o">|</span> <span class="n">truncates</span> <span class="o">|</span>          <span class="n">stats_reset</span>
<span class="c1">------+-------------+----------+-----------+--------------+-------------+---------+-----------+-------------------------------</span>
 <span class="n">Xact</span> <span class="o">|</span>         <span class="mi">460</span> <span class="o">|</span> <span class="mi">30686596</span> <span class="o">|</span>        <span class="mi">44</span> <span class="o">|</span>         <span class="mi">2030</span> <span class="o">|</span>           <span class="mi">0</span> <span class="o">|</span>    <span class="mi">1684</span> <span class="o">|</span>         <span class="mi">0</span> <span class="o">|</span> <span class="mi">2024</span><span class="o">-</span><span class="mi">11</span><span class="o">-</span><span class="mi">19</span> <span class="mi">09</span><span class="p">:</span><span class="mi">52</span><span class="p">:</span><span class="mi">33</span><span class="p">.</span><span class="mi">506794</span><span class="o">-</span><span class="mi">06</span>
</code></pre></div></div>

<p>“Hit” and “read” refer to reads from the SLRU that where the desired pages were already in the SLRU or they were not.</p>

<p>When new pages are allocated, we see this reflected in “blks_zeroed” as they’re written out with zeroes.</p>

<p>When new pages are written (blks_written) into the SLRU this creates “dirtied” pages that eventually will be written out (flushes).</p>

<p>SLRUs can also be truncated (“Truncates” count).</p>

<p>Some of the source code for SLRUs in Postgres is in the file <code class="language-plaintext highlighter-rouge">backend/access/transam/slru.c</code>.
<a href="https://github.com/postgres/postgres/blob/master/src/backend/access/transam/slru.c">https://github.com/postgres/postgres/blob/master/src/backend/access/transam/slru.c</a></p>

<p>Now that we know some basics about SLRUs and a specific type, the MultiXact SLRU, what are some operational concerns or things that can go wrong?</p>

<h2 id="what-can-go-wrong-with-slrus-and-xacts">What can go wrong with SLRUs and Xacts?</h2>
<p>Operational problems can stem from the fact that SLRUs use a 32-bit number and for high scale Postgres, it’s possible to consume these fast enough that the number can “wrap around.”</p>

<p>Two examples with public write-ups related to SLRU operational problems are:</p>

<ul>
  <li>Subtransactions overflow: Using subtransactions, each use of a subtransaction creates an id to track. At a high enough creation rate it’s possible to run out of values.
This was written up in the GitLab post: <a href="https://about.gitlab.com/blog/why-we-spent-the-last-month-eliminating-postgresql-subtransactions/">Why we spent the last month eliminating PostgreSQL subtransactions</a>.</li>
</ul>

<p>MultiXact member space exhaustion: MultiXact or multiple transactions can occur in a few scenarios.</p>
<ul>
  <li>An explicit row lock: <code class="language-plaintext highlighter-rouge">SELECT … FOR SHARE</code></li>
  <li><code class="language-plaintext highlighter-rouge">SELECT … FOR UPDATE</code></li>
</ul>

<p>Written up in the Metronome blog post: <a href="https://metronome.com/blog/root-cause-analysis-postgresql-multixact-member-exhaustion-incidents-may-2025">Root Cause Analysis: PostgreSQL MultiXact member exhaustion incidents (May 2025)</a>.</p>

<p>A scenario for that could be a foreign key constraint lookup on a high insert table referencing a low cardinality table.</p>

<p>Another type of problem in the buttondown post<sup id="fnref:buttondown:1" role="doc-noteref"><a href="#fn:buttondown" class="footnote" rel="footnote">2</a></sup> is the quadratic growth of MultiXacts.</p>

<p>Dilip Kumar talked about: “Long running transaction, system can go fully to cache replacement, TPS drops, with subtransactions ids (need to get parent ids).” See Dilip’s presentation for more info.<sup id="fnref:dilip" role="doc-noteref"><a href="#fn:dilip" class="footnote" rel="footnote">3</a></sup></p>

<h2 id="what-do-we-do-with-info-as-postgres-operators">What do we do with info as Postgres operators?</h2>
<p>This is a huge topic and this post just scratches the surface.</p>

<p>However, let’s wrap this up here a bit with some takeaways.</p>

<p>If operating a high scale Postgres instance when it comes to SLRUs, what’s worth knowing about?</p>

<ul>
  <li>Know about the SLRU system in general, how to monitor it, and don’t forget about extensions</li>
  <li>Learn about SLRUs limitations and possible failure points, for the various types</li>
  <li>Determine whether your workload is using SLRUs, monitor their growth, and learn about the possible failure points based on your use</li>
</ul>

<h2 id="whats-changing-with-slrus-in-new-postgres-versions">What’s changing with SLRUs in new Postgres versions?</h2>
<p>In Postgres 17, the MultiXact member space and offset is now configurable beyond the initial default size. The unit is the number of 8KB pages.</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">multixact_member_buffers</code>, default is 32 8kb pages</li>
  <li><code class="language-plaintext highlighter-rouge">multixact_offset_buffers</code>, default is 16 8kb pages</li>
</ul>

<blockquote>
  <p>In the recent episode of postgres.fm <em>MultiXact member space exhaustion</em>,<sup id="fnref:pgfm" role="doc-noteref"><a href="#fn:pgfm" class="footnote" rel="footnote">4</a></sup> the Metronome engineers discussed working on a patch related to MultiXact member exhaustion.</p>
</blockquote>

<p>Lukas covers changes in Postgres 17 to adjust SLRU cache sizes. Each of the SLRU types can now be configured to be larger in size.
<a href="https://pganalyze.com/blog/5mins-postgres-17-configurable-slru-cache">https://pganalyze.com/blog/5mins-postgres-17-configurable-slru-cache</a></p>

<h2 id="conclusion">Conclusion</h2>
<p>I’m still learning about MultiXacts, SLRUs, and failure modes as a result of these. If you have feedback on this post or additional useful resources, I’d love to hear about them. Please contact me here or on social media.</p>

<p>Thanks for reading!</p>

<h2 id="resources">Resources</h2>
<p>Dilip Kumar presentation 2024 - PostgreSQL Development Conference <a href="https://www.youtube.com/watch?v=74xAqgS2thY">https://www.youtube.com/watch?v=74xAqgS2thY</a></p>

<p>MultiXacts Dan Slimmon
<a href="https://blog.danslimmon.com/2023/12/11/concurrent-locks-and-multixacts-in-postgres/">https://blog.danslimmon.com/2023/12/11/concurrent-locks-and-multixacts-in-postgres/</a></p>

<p>5 minutes of Postgres LWLock Lock Manager
<a href="https://pganalyze.com/blog/5mins-postgres-LWLock-lock-manager-contention">https://pganalyze.com/blog/5mins-postgres-LWLock-lock-manager-contention</a></p>

<p>SLRU Improvements Proposals Wiki
<a href="https://wiki.postgresql.org/wiki/SLRU_improvements">https://wiki.postgresql.org/wiki/SLRU_improvements</a></p>

<h2 id="corrections">Corrections</h2>

<p>September 27, 2025: An earlier version of this post inaccurately described SLRU buffers as not being WAL logged. Thank you to Laurenz Albe for writing in to correct this and providing a pointer into the source code to learn more.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:alvaro" role="doc-endnote">
      <p><a href="https://p2d2.cz/files/p2d2-2025-herrera-slru.pdf">https://p2d2.cz/files/p2d2-2025-herrera-slru.pdf</a> <a href="#fnref:alvaro" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:buttondown" role="doc-endnote">
      <p><a href="https://buttondown.com/nelhage/archive/notes-on-some-postgresql-implementation-details/">https://buttondown.com/nelhage/archive/notes-on-some-postgresql-implementation-details/</a> <a href="#fnref:buttondown" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:buttondown:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:dilip" role="doc-endnote">
      <p><a href="https://www.youtube.com/watch?v=74xAqgS2thY">https://www.youtube.com/watch?v=74xAqgS2thY</a> <a href="#fnref:dilip" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:pgfm" role="doc-endnote">
      <p><a href="https://postgres.fm/episodes/multixact-member-space-exhaustion">https://postgres.fm/episodes/multixact-member-space-exhaustion</a> <a href="#fnref:pgfm" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><summary type="html"><![CDATA[In this post we’ll cover two types of Postgres internals.]]></summary></entry><entry><title type="html">Avoid UUID Version 4 Primary Keys (for Postgres)</title><link href="https://andyatkinson.com/avoid-uuid-version-4-primary-keys" rel="alternate" type="text/html" title="Avoid UUID Version 4 Primary Keys (for Postgres)" /><published>2025-07-02T00:00:00+00:00</published><updated>2025-07-02T00:00:00+00:00</updated><id>https://andyatkinson.com/avoid-uuid-v4-primary-keys</id><content type="html" xml:base="https://andyatkinson.com/avoid-uuid-version-4-primary-keys"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>Over the last decade, when working on databases with UUID Version 4<sup id="fnref:rfc" role="doc-noteref"><a href="#fn:rfc" class="footnote" rel="footnote">1</a></sup> as the primary key data type, these databases have usually had bad performance and excessive IO.</p>

<p>UUID is a native data type in Postgres stored as binary data. Various UUID versions are in the RFC. Version 4 has 128 bits, with 122 being random, obfuscating information like when the value was created or where it was generated.</p>

<p>Version 4 UUIDs are easy to generate in Postgres using the <code class="language-plaintext highlighter-rouge">gen_random_uuid()</code><sup id="fnref:gen" role="doc-noteref"><a href="#fn:gen" class="footnote" rel="footnote">2</a></sup> function since version 13 (released in 2020).</p>

<p>I’ve learned there are misconceptions about UUID Version 4, and sometimes these are the reasons users pick this data type.</p>

<p>Because of the poor performance, misconceptions, and available alternatives, I’ve come around to a simple position: <em>Avoid UUID Version 4 for primary keys</em>.</p>

<p>My more controversial take is to avoid UUIDs in general, but I understand there are some legitimate reasons for them without practical alternatives.</p>

<p>As a database enthusiast, I wanted to have an articulated position on this classic “Integer v. UUID” debate.</p>

<p>Among databases folks, debating this may be tired and clichéd. However, from my consulting work, I can say I work with databases using UUID v4 in 2024 and 2025, and still see the issues discussed in this post.</p>

<p>Let’s dig in.</p>

<h2 id="uuid-context-for-this-post">UUID context for this post</h2>
<ul>
  <li>UUIDs (or GUID in Microsoft speak)<sup id="fnref:ms" role="doc-noteref"><a href="#fn:ms" class="footnote" rel="footnote">3</a></sup>) are long strings of 36 characters, 32 digits, 4 hyphens, stored as 128 bits (16 byte) values, stored using the binary <code class="language-plaintext highlighter-rouge">uuid</code> data type in Postgres</li>
  <li>The RFC documents how the 128 bits are set</li>
  <li>The bits for UUID Version 4 are mostly random values</li>
  <li>UUID Version 7 includes a timestamp in the first 48 bits, which works much better with database indexes compared with random values</li>
</ul>

<p>Although unreleased as of this writing, and pulled from Postgres 17 previously, UUID V7 is part of Postgres 18<sup id="fnref:land" role="doc-noteref"><a href="#fn:land" class="footnote" rel="footnote">4</a></sup> scheduled for release in the Fall of 2025.</p>

<p>What kind of app databases are in scope for this post?</p>

<h2 id="scope-of-web-app-usage-and-their-scale">Scope of web app usage and their scale</h2>
<p>The kinds of web applications I’m thinking of with this post are monolithic web apps, with Postgres as their primary OLTP database. The apps could be in categories like social media, e-commerce, click tracking, or business process automation apps.</p>

<p>The types of performance issues discussed here are related to inefficient storage and retrieval, meaning they happen for all of these types of apps.</p>

<p>What’s the core issue with UUID v4?</p>

<h2 id="randomness-is-the-issue">Randomness is the issue</h2>
<p>The core issue with UUID Version 4, given that the 122 bits they’re made up of are “random or pseudo-randomly generated values”<sup id="fnref:rfc:1" role="doc-noteref"><a href="#fn:rfc" class="footnote" rel="footnote">1</a></sup>, is how the values are maintained in indexes. Since primary keys are backed by indexes by default, each insert is less efficient compared with inserts for sequentially ordered values.</p>

<p>For lookups, each update and delete for individual items or for ranges of items are less efficient, due to increased traversal of non-sequential index pages in Postgres.</p>

<p>Since the randomly generated values aren’t inserted sequentially (or in sequential/adjacent pages), it’s less efficient to find them later for updates or deletes. Each of these workload types use the primary key index.</p>

<p>UUID v4s don’t have a useful natural ordering that aligns with how they’re stored, and thus both storage and retrieval is less efficient.</p>

<p>Later in the post we’ll look at just how many more Postgres pages need to be accessed for equivalent data, and what that means in terms of performance.</p>

<p>Despite the inefficiencies, UUID v4s and UUIDs in general remain (or at least were) popular in the last decade based on my experience consulting in Postgres.</p>

<p>Given the popularity, what use cases for UUID are there?</p>

<h2 id="why-choose-uuids-at-all-generating-values-from-one-or-more-client-applications">Why choose UUIDs at all? Generating values from one or more client applications</h2>
<p>One use case for UUIDs is when there’s a need to generate an identifier on a client or from multiple services, then passed to Postgres for persistence.</p>

<p>For web apps, generally they instantiate objects in memory and don’t expect an identifier to be used for lookups until after an instance is persisted as a row (where the database generates the identifier).</p>

<p>In a microservices architecture where the apps have their own databases, the ability to generate identifiers from each database without collisions is a use case for UUIDs. The UUID could also identify the database a value came from later, vs. an integer.</p>

<p>For collision avoidance (see HN discussion<sup id="fnref:hn" role="doc-noteref"><a href="#fn:hn" class="footnote" rel="footnote">5</a></sup>), we can’t practically make the same guarantee with sequence-backed integers. There are hacks, like generating even and odd integers between two instances, or using different ranges in the int8 range.</p>

<p>There are also alternative identifiers like using composite primary keys (CPKs), however the same set of 2 values wouldn’t uniquely identify a particular table.</p>

<p>The avoidance of collisions is described this way on Wikipedia:<sup id="fnref:wiki" role="doc-noteref"><a href="#fn:wiki" class="footnote" rel="footnote">6</a></sup></p>

<blockquote>
  <p>The number of random version-4 UUIDs which need to be generated in order to have a 50% probability of one collision: 2.71 quintillion</p>
</blockquote>

<p>This number would be equivalent to:</p>

<blockquote>
  <p>Generating 1 billion UUIDs per second for about 86 years.</p>
</blockquote>

<p>Are UUIDs secure?</p>

<h2 id="misconceptions-uuids-are-secure">Misconceptions: UUIDs are secure</h2>
<p>One misconception about UUIDs is that they’re secure. However, the RFC describes that they shouldn’t be considered secure “capabilities.”</p>

<p>From RFC 4122<sup id="fnref:rfc:2" role="doc-noteref"><a href="#fn:rfc" class="footnote" rel="footnote">1</a></sup> Section 6 Security Considerations:</p>
<blockquote>
  <p>Do not assume that UUIDs are hard to guess; they should not be used
  as security capabilities</p>
</blockquote>

<p>How can we create obfuscated codes from integers?</p>

<h2 id="creating-obfuscated-values-using-integers">Creating obfuscated values using integers</h2>
<p>While UUID V4s obfuscate their creation time, the values can’t be ordered to see when they were created relative to each other. We can  achieve those properties with integers with a little more work.</p>

<p>One option is to generate a pseudo-random code from an integer, then use that value externally, while still using integers internally.</p>

<p>To see the full details of this solution, please check out: <em>Short alphanumeric pseudo random identifiers in Postgres</em><sup id="fnref:alpha" role="doc-noteref"><a href="#fn:alpha" class="footnote" rel="footnote">7</a></sup></p>

<p>We’ll summarize it here.</p>

<ul>
  <li>Convert a decimal integer like “2” into binary bits. E.g. a 4 byte, 32 bit integer: 00000000 00000000 00000000 00000010</li>
  <li>Perform an exclusive OR (XOR) operation on all the bits using a key</li>
  <li>Encode each bit using a base62 alphabet</li>
</ul>

<p>The obfuscated id is stored in a generated column. By reviewing the generated values, they are similar, but aren’t ordered by their creation order.</p>

<p>The values in insertion order were <code class="language-plaintext highlighter-rouge">01Y9I</code>, <code class="language-plaintext highlighter-rouge">01Y9L</code>, then <code class="language-plaintext highlighter-rouge">01Y9K</code>.</p>

<p>With alphabetical order, the last two would be flipped: <code class="language-plaintext highlighter-rouge">01Y9I</code> first, then <code class="language-plaintext highlighter-rouge">01Y9K</code> second, then <code class="language-plaintext highlighter-rouge">01Y9L</code> third, sorting on the fifth character.</p>

<p>If I wanted to use this approach for all tables, I’d try a centralized table that was polymorphic, storing a record for each table that’s using a code (and a foreign key constraint).</p>

<p>That way I’d know where the code was used.</p>

<p>Why else might we want to skip UUIDs?</p>

<h2 id="reasons-against-uuids-in-general-they-consume-a-lot-of-space">Reasons against UUIDs in general: they consume a lot of space</h2>
<p>UUIDs are 16 bytes (128 bits) per value, which is double the space of bigint (8 bytes), or quadruple the space of 4-byte integers. This extra space adds up once many tables have millions of rows, and copies of a database are being moved around as backups and restores.</p>

<p>A more considerable impact to performance though is the poor characteristics of writing and reading random data into indexes.</p>

<h2 id="reasons-against-uuid-v4s-add-insert-latency-due-to-index-page-splits-fragmentation">Reasons against: UUID v4s add insert latency due to index page splits, fragmentation</h2>
<p>For random UUID v4s, Postgres incurs more latency for every insert operation.</p>

<p>For integer primary key rows, their values are maintained in index pages with “append-mostly” operations on “leaf nodes,” since their values are orderable, and since B-Tree indexes store entries in sorted order.</p>

<p>For UUID v4s, primary key values in B-Tree indexes are problematic.</p>

<p>Inserts are not appended to the right most leaf page. They are placed into a random page, and that could be mid-page or an already-full page, causing a page split that would have been unnecessary with an integer.</p>

<p>Planet Scale has a nice visualization of index page splits and rebalancing.<sup id="fnref:ps" role="doc-noteref"><a href="#fn:ps" class="footnote" rel="footnote">8</a></sup></p>

<p>Unnecessary splits and rebalancing add space consumption and processing latency to write operations. This extra IO shows up in Write Ahead Log (WAL) generation as well.</p>

<p>Given fixed size pages, we want high density within the pages. Later on we’ll use <em>pageinspect</em> to check the average leaf density between integer and UUID to help compare the two.</p>

<h2 id="excessive-io-for-lookups-even-with-orderable-uuids">Excessive IO for lookups even with orderable UUIDs</h2>
<p>B-Tree page layout means you can fit fewer UUIDs per 8KB page. Since we have the limitation of fixed page sizes, we at least want them to be as densely packed as possible.</p>

<p>Since UUID indexes are ~40% larger in leaf pages than bigint (int8) for the same logical number of rows, they can’t be as densely packed with values. As Lukas says, “<em>All in all, the physical data structure matters as much as your server configuration to achieve the best I/O performance in Postgres</em>.”<sup id="fnref:pga5" role="doc-noteref"><a href="#fn:pga5" class="footnote" rel="footnote">9</a></sup></p>

<p>This means that for individual lookups, range scans, or UPDATES, we will incur ~40% more I/O on UUID indexes, as more pages are scanned. Remember that even to access one row, in Postgres the whole page is accessed where the row is, and copied into a shared memory buffer.</p>

<p>Let’s insert and query data and take a look at numbers between these data types.</p>

<h2 id="working-with-integers-uuid-v4-and-uuid-v7">Working with integers, UUID v4, and UUID v7</h2>
<p>Let’s create integer, UUID v4, and UUID v7 fields, index them, load them into the buffer cache with <em>pg_prewarm</em>.</p>

<p>I will use the schema examples from the Cybertec post <a href="https://www.cybertec-postgresql.com/en/unexpected-downsides-of-uuid-keys-in-postgresql/">Unexpected downsides of UUID keys in PostgreSQL</a> by Ants Aasma.</p>

<p>View <a href="https://github.com/andyatkinson/pg_scripts/pull/20">andyatkinson/pg_scripts PR #20</a>.</p>

<p>On my Mac, I compiled the <code class="language-plaintext highlighter-rouge">pg_uuidv7</code> extension. Once compiled and enabled for Postgres, I could use the extension functions to generate UUID V7 values.</p>

<p>Another extension <code class="language-plaintext highlighter-rouge">pg_prewarm</code> is used. It’s a module included with Postgres, so it just needs to be enabled per database where it’s used.</p>

<p>The difference in latency and the enormous difference in buffers from the post was reproducible in my testing.</p>

<blockquote>
  <p>“Holy behemoth buffer count batman”
<small>- Ants Aasma</small></p>
</blockquote>

<p>Cybertec post results:</p>
<ul>
  <li>27,332 buffer hits, index only scan on the <code class="language-plaintext highlighter-rouge">bigint</code> column</li>
  <li>8,562,960 buffer hits, index only scan on the UUID V4 index scan</li>
</ul>

<p>Since these are buffer <em>hits</em> we’re accessing them from memory, which is faster than disk. We can focus then on only the difference in latency based on the data types.</p>

<p>How many more pages are accessed for the UUID index? 8,535,628 (8.5 million!) more 8KB pages were accessed, a 31229.4% increase.</p>
<ul>
  <li>68,285,024 KB or ~68.3 GB! more data that’s accessed</li>
</ul>

<p>Calculating a low and high estimate of access speeds for memory:</p>
<ul>
  <li>Low estimate: 20 GB/s</li>
  <li>High estimate: 80 GB/s</li>
</ul>

<p>Accessing 68.3 GB of data from memory (<code class="language-plaintext highlighter-rouge">shared_buffers</code> in PostgreSQL) would add:</p>
<ul>
  <li>~3.4 seconds of latency (low speed)</li>
  <li>~0.86 seconds of latency (high speed)</li>
</ul>

<p>That’s between ~1 and ~3.4 seconds of additional latency solely based on the data type using this simplistic method of calculation.</p>

<p>Please note this is not a rigorous calculation method, just something to do some comparisons.</p>

<p>Here we used 10 million rows and performed 1 million updates, but the latencies will get worse as data and query volumes increase.</p>

<h2 id="inspecting-density-with-the-pageinspect-extension">Inspecting density with the pageinspect extension</h2>
<p>We can inspect the average fill percentage (density) of leaf pages using the <em>pageinspect</em> extension.</p>

<p>The <code class="language-plaintext highlighter-rouge">uuid_experiments/page_density.sql</code> (<a href="https://github.com/andyatkinson/pg_scripts/pull/20">andyatkinson/pg_scripts PR #20</a>) query in the repo gets the indexes for the integer and v4 and v7 uuid columns, their total page counts, their page stats, and the number of leaf pages.</p>

<p>Using the leaf pages, the query calculates an average fill percentage.</p>

<p>After performing the 1 million updates on the 10 million rows mentioned in the example, I got these results from that query:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">idxname</span>             <span class="o">|</span> <span class="n">avg_leaf_fill_percent</span>
<span class="c1">---------------------+-----------------------</span>
 <span class="n">records_id_idx</span>      <span class="o">|</span>                 <span class="mi">97</span><span class="p">.</span><span class="mi">64</span>
 <span class="n">records_uuid_v4_idx</span> <span class="o">|</span>                 <span class="mi">79</span><span class="p">.</span><span class="mi">06</span>
 <span class="n">records_uuid_v7_idx</span> <span class="o">|</span>                 <span class="mi">90</span><span class="p">.</span><span class="mi">09</span>
<span class="p">(</span><span class="mi">3</span> <span class="k">rows</span><span class="p">)</span>
</code></pre></div></div>

<p>This shows the <code class="language-plaintext highlighter-rouge">integer</code> index had an average fill percentage of nearly 98%, while the UUID v4 index was around 79%.</p>

<h2 id="uuid-downsides-worse-cache-hit-ratio">UUID Downsides: Worse cache hit ratio</h2>
<p>The Postgres buffer cache is a critical part of good performance.</p>

<p>For good performance, we want our queries to produce cache “hits” as much as possible.</p>

<p>The buffer cache has limited space. Usually 25-40% of system memory is allocated to it, and the total database size including table and index data is usually much larger than that amount of memory. That means we’ll have trade-offs, as all data will not fit into system memory. This is where the challenges come in!</p>

<p>When pages are accessed they’re copied into the buffer cache as buffers. When write operations happen, buffers are dirtied before being flushed.<sup id="fnref:string" role="doc-noteref"><a href="#fn:string" class="footnote" rel="footnote">10</a></sup></p>

<p>Since the UUIDs are randomly located, additional buffers will need to be copied to the cache compared to ordered integers. Buffers might be evicted to make space that are needed, decreasing hit rates.</p>

<h2 id="mitigations-rebuilding-indexes-with-uuid-values">Mitigations: Rebuilding indexes with UUID values</h2>
<p>Since the tables and indexes are more likely to be fragmented, it makes sense to rebuild the tables and indexes periodically.</p>

<p>Rebuilding tables can be done using pg_repack, pg_squeeze, or <code class="language-plaintext highlighter-rouge">VACUUM FULL</code> if you can afford to perform the operation offline.</p>

<p>Indexes can be rebuilt online using <code class="language-plaintext highlighter-rouge">REINDEX CONCURRENTLY</code>.</p>

<p>While the newly laid out data in pages, they will still not have correlation, and thus not be smaller. The space formerly occupied by deletes will be reclaimed for reuse though.</p>

<h2 id="mitigation-shared-buffers-and-work_mem-memory-sizing">Mitigation: Shared buffers and work_mem memory sizing</h2>
<p>If possible, size your primary instance memory to be 4x than the size of database. If your database size is 25GB, run an instance with at least 100GB of memory if its in the budget.</p>

<p>A 128GB memory with 25% of memory allocated to buffer cache provides 32GB (controllable via <code class="language-plaintext highlighter-rouge">shared_buffers</code>) which could be enough to keep all table and index pages in memory cache.</p>

<p>Use <em>pg_buffercache</em><sup id="fnref:pgbc" role="doc-noteref"><a href="#fn:pgbc" class="footnote" rel="footnote">11</a></sup> to inspect the contents, and <em>pg_prewarm</em><sup id="fnref:pgpre" role="doc-noteref"><a href="#fn:pgpre" class="footnote" rel="footnote">12</a></sup> to populate tables into it.</p>

<p>One tactic I’ve used when working with UUID v4 random values where sorting is happening, is to provide more memory to sort operations.</p>

<p>To do that in Postgres, we can change the <code class="language-plaintext highlighter-rouge">work_mem</code> setting. This setting can be changed for the whole database, a session, or even for individual queries.</p>

<p>Check out <a href="https://www.pgmustard.com/blog/work-mem">Configuring work_mem in Postgres</a> on PgMustard for an example of setting this in a session.</p>

<h2 id="mitigation-in-rails-uuid-and-implicit-order-column-active-record">Mitigation in Rails: UUID and implicit order column Active Record</h2>
<p>Since Rails 6, we can control implicit_order_column.<sup id="fnref:bb" role="doc-noteref"><a href="#fn:bb" class="footnote" rel="footnote">13</a></sup> The <a href="https://github.com/djezzzl/database_consistency/issues/197">database_consistency gem even has a checker</a> for folks using UUID primary keys.</p>

<p>When ORDER BY is generated in queries implicitly, it may be worth ordering on a different high cardinality field that’s indexed, like a <code class="language-plaintext highlighter-rouge">created_at</code> timestamp field.</p>

<h2 id="mitigating-poor-performance-by-clustering-on-orderable-field">Mitigating poor performance by clustering on orderable field</h2>
<p>Cluster on a column that’s high cardinality and indexed could be a mitigation option.</p>

<p>For example, imagine your UUID primary table has a <code class="language-plaintext highlighter-rouge">created_at</code> timestamp column that’s indexed with <code class="language-plaintext highlighter-rouge">idx_on_tbl_created_at</code>, and clustering on that.</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">CLUSTER</span> <span class="n">table_with_uuid_ok</span> <span class="k">USING</span> <span class="n">idx_on_tbl_created_at</span><span class="p">;</span>
</code></pre></div></div>
<p>I don’t see CLUSTER used ever really though as it takes an <a href="https://pglocks.org/?pgcommand=CLUSTER">access exclusive</a> lock. The CLUSTER is a one-time operation that would also need to be repeated regularly to maintain its benefits.</p>

<h2 id="recommendation-stick-with-sequences-integers-and-big-integers">Recommendation: Stick with sequences, integers, and big integers</h2>
<p>For new databases that <em>may</em> be small, with unknown growth, I recommend plain old integers and an identity column (backed by a sequence)<sup id="fnref:seq" role="doc-noteref"><a href="#fn:seq" class="footnote" rel="footnote">14</a></sup> for primary keys. These are signed 32 bit (4-byte) values. This provides about 2 billion positive unique values per table.</p>

<p>For many business apps, they will never reach 2 billion unique values per table, so this will be adequate for their entire life. I’ve also recommended always using bigint/int8 in other contexts.</p>

<p>I guess it comes down to what you know about your data size, how you can project growth. There are plenty of low growth business apps out there, in constrained industries, and constrained sets of business users.</p>

<p>For Internet-facing consumer apps with expected high growth, like social media, click tracking, sensor data, telemetry collection types of apps, or when migrating an existing medium or large database with 100s of millions or billions of rows, then it makes sense to start with <code class="language-plaintext highlighter-rouge">bigint</code> (int8), 64-bit, 8-byte integer primary keys.</p>

<h2 id="uuid-v4-alternatives-use-time-ordered-uuids-like-version-7">UUID v4 alternatives: Use time-ordered UUIDs like Version 7</h2>
<p>Since Postgres 18 is not yet released, generating UUID V7s now in Postgres is possible using the <code class="language-plaintext highlighter-rouge">pg_uuidv7</code> extension.</p>

<p>If you have an existing UUID v4 filled database and can’t afford a costly migration to another primary key data type, then starting to populate new values using UUID v7 will help somewhat.</p>

<p>Fortunately the binary <code class="language-plaintext highlighter-rouge">uuid</code> data type in Postgres can be used whether you’re storing V4 or V7 UUID values.</p>

<p>Another alternative that relies on an extension is <em>sequential_uuids</em>.<sup id="fnref:sequ" role="doc-noteref"><a href="#fn:sequ" class="footnote" rel="footnote">15</a></sup></p>

<h2 id="summary">Summary</h2>
<ul>
  <li>UUID v4s increase latency for lookups, as they can’t take advantage of fast ordered lookups in B-Tree indexes</li>
  <li>For new databases, don’t use <code class="language-plaintext highlighter-rouge">gen_random_uuid()</code> for primary key types, which generates random UUID v4 values</li>
  <li>UUIDs consume twice the space of <code class="language-plaintext highlighter-rouge">bigint</code></li>
  <li>UUID v4 values are not meant to be secure per the UUID RFC</li>
  <li>UUID v4s are random. For good performance, the whole index must be in buffer cache for index scans, which is increasingly unlikely for bigger data.</li>
  <li>UUID v4s cause more page splits, which increase IO for writes with increased fragmentation, and increased size of WAL logs</li>
  <li>For non-guessable, obfuscated pseudo-random codes, we can generate those from integers, which could be an alternative to using UUIDs</li>
  <li>If you must use UUIDs, use time-orderable UUIDs like UUID v7</li>
</ul>

<p>Do you see any errors or have any suggested improvements? Please <a href="/contact">contact me</a>. Thanks for reading!</p>

<h2 id="learn-more">Learn More</h2>
<ul>
  <li>Franck Pachot for AWS Heroes has an interesting take on <a href="https://dev.to/aws-heroes/uuid-in-postgresql-3n53">UUID in PostgreSQL</a></li>
  <li>Brandur has a great post: <a href="https://brandur.org/nanoglyphs/026-ids">Identity Crisis: Sequence v. UUID as Primary Key</a></li>
  <li>5mins of Postgres: <a href="https://pganalyze.com/blog/5mins-postgres-uuid-vs-serial-primary-keys">UUIDs vs Serial for Primary Keys - what’s the right choice?</a></li>
  <li><a href="https://github.com/andyatkinson/pg_scripts/pull/20">andyatkinson/pg_scripts PR #20</a></li>
</ul>

<h2 id="updates">Updates</h2>
<ul>
  <li>2025-12-15: Appeared on <a href="https://news.ycombinator.com/item?id=46272487">front page of Hacker News</a>. Updating the “Randomness is the issue” section for improved clarity.</li>
</ul>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:rfc" role="doc-endnote">
      <p><a href="https://datatracker.ietf.org/doc/html/rfc4122#section-4.4">https://datatracker.ietf.org/doc/html/rfc4122#section-4.4</a> <a href="#fnref:rfc" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:rfc:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a> <a href="#fnref:rfc:2" class="reversefootnote" role="doc-backlink">&#8617;<sup>3</sup></a></p>
    </li>
    <li id="fn:gen" role="doc-endnote">
      <p><a href="https://www.postgresql.org/docs/current/functions-uuid.html">https://www.postgresql.org/docs/current/functions-uuid.html</a> <a href="#fnref:gen" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:ms" role="doc-endnote">
      <p><a href="https://stackoverflow.com/a/6953207/126688">https://stackoverflow.com/a/6953207/126688</a> <a href="#fnref:ms" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:land" role="doc-endnote">
      <p><a href="https://www.thenile.dev/blog/uuidv7">https://www.thenile.dev/blog/uuidv7</a> <a href="#fnref:land" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:hn" role="doc-endnote">
      <p><a href="https://news.ycombinator.com/item?id=36429986">https://news.ycombinator.com/item?id=36429986</a> <a href="#fnref:hn" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:wiki" role="doc-endnote">
      <p><a href="https://en.wikipedia.org/wiki/Universally_unique_identifier">https://en.wikipedia.org/wiki/Universally_unique_identifier</a> <a href="#fnref:wiki" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:alpha" role="doc-endnote">
      <p><a href="https://andyatkinson.com/generating-short-alphanumeric-public-id-postgres">https://andyatkinson.com/generating-short-alphanumeric-public-id-postgres</a> <a href="#fnref:alpha" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:ps" role="doc-endnote">
      <p><a href="https://planetscale.com/blog/the-problem-with-using-a-uuid-primary-key-in-mysql">https://planetscale.com/blog/the-problem-with-using-a-uuid-primary-key-in-mysql</a> <a href="#fnref:ps" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:pga5" role="doc-endnote">
      <p><a href="https://pganalyze.com/blog/5mins-postgres-io-basics">https://pganalyze.com/blog/5mins-postgres-io-basics</a> <a href="#fnref:pga5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:string" role="doc-endnote">
      <p><a href="https://stringintech.github.io/blog/p/postgresql-buffer-cache-a-practical-guide/">https://stringintech.github.io/blog/p/postgresql-buffer-cache-a-practical-guide/</a> <a href="#fnref:string" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:pgbc" role="doc-endnote">
      <p><a href="https://www.postgresql.org/docs/current/pgbuffercache.html">https://www.postgresql.org/docs/current/pgbuffercache.html</a> <a href="#fnref:pgbc" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:pgpre" role="doc-endnote">
      <p><a href="https://www.postgresql.org/docs/current/pgprewarm.html">https://www.postgresql.org/docs/current/pgprewarm.html</a> <a href="#fnref:pgpre" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:bb" role="doc-endnote">
      <p><a href="https://www.bigbinary.com/blog/rails-6-adds-implicit_order_column">https://www.bigbinary.com/blog/rails-6-adds-implicit_order_column</a> <a href="#fnref:bb" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:seq" role="doc-endnote">
      <p><a href="https://www.cybertec-postgresql.com/en/uuid-serial-or-identity-columns-for-postgresql-auto-generated-primary-keys/">https://www.cybertec-postgresql.com/en/uuid-serial-or-identity-columns-for-postgresql-auto-generated-primary-keys/</a> <a href="#fnref:seq" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:sequ" role="doc-endnote">
      <p><a href="https://pgxn.org/dist/sequential_uuids">https://pgxn.org/dist/sequential_uuids</a> <a href="#fnref:sequ" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><category term="Ruby on Rails" /><summary type="html"><![CDATA[Introduction Over the last decade, when working on databases with UUID Version 41 as the primary key data type, these databases have usually had bad performance and excessive IO. https://datatracker.ietf.org/doc/html/rfc4122#section-4.4 &#8617;]]></summary></entry><entry><title type="html">CORE Database Schema Design: Constraint-driven, Optimized, Responsive, and Efficient</title><link href="https://andyatkinson.com/constraint-driven-optimized-responsive-efficient-core-db-design" rel="alternate" type="text/html" title="CORE Database Schema Design: Constraint-driven, Optimized, Responsive, and Efficient" /><published>2025-06-09T00:00:00+00:00</published><updated>2025-06-09T00:00:00+00:00</updated><id>https://andyatkinson.com/constraint-driven-optimized-responsive-efficient-core-db-design</id><content type="html" xml:base="https://andyatkinson.com/constraint-driven-optimized-responsive-efficient-core-db-design"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>In this post, we’ll cover some database design principles and package them up into a catchy mnemonic acronym.</p>

<p>Software engineering is loaded with acronyms like this. For example, <a href="https://en.wikipedia.org/wiki/SOLID">SOLID principles</a> describe 5 principles, Single responsibility, Open-closed, Liskov substitution, Interface segregation and Dependency inversion, that promote good object-oriented design.</p>

<p>Databases are loaded with acronyms, for example “ACID” for the properties of a transaction, but I wasn’t familiar with one the schema designer could keep in mind while they’re working.</p>

<p>Thus, the motivation for this acronym was to help the schema designer, by packaging up some principles of good design practices for database schema design. It’s not based in research or academia though, so don’t take this too seriously. That said, I’d love your feedback!</p>

<p>Let’s get into it.</p>

<h2 id="picking-a-mnemonic-acronym">Picking a mnemonic acronym</h2>
<p>In picking an acronym, I wanted it to be short and have each letter describe a word that’s useful, practical, and grounded in experience. I preferred a real word for memorability!</p>

<p>The result was “<strong>CORE</strong>.” Let’s explore each letter and the word behind it.</p>

<h2 id="constraint-driven">Constraint-Driven</h2>
<p>The first word (technically two) is “constraint-driven.” Relational databases offer rigid structures, but the ability to be changed while online, a form of flexibility in their evolution. We evolve their structure through <a href="https://en.wikipedia.org/wiki/Data_definition_language">DDL</a>. They use <a href="https://www.postgresql.org/docs/current/datatype.html">data types</a> and <a href="https://www.postgresql.org/docs/current/ddl-constraints.html">constraints</a> to make changes, as entities and relationships evolve.</p>

<p>Constraint-driven refers to leveraging all the constraint objects available, designing for our needs today, but also in a more general sense applying constraints (restrictions) to designs in the pursuit of data consistency and quality.</p>

<p>Let’s look at some examples. Choose the appropriate data types, like a numeric data type and not a character data type when storing a number. Use <code class="language-plaintext highlighter-rouge">NOT NULL</code> for columns by default. Create foreign key constraints for table relationships by default.</p>

<p>Validate expected data inputs using check constraints. For small databases, use <code class="language-plaintext highlighter-rouge">integer</code> primary keys. If tables get huge later, no problem, we can migrate the data into a bigger more suitable structure.</p>

<p>The mindset is to prefer rigidity initially, design for today, then leverage the flexibility available to evolve later, as opposed to designing for a hypothetical future state.</p>

<h2 id="optimized">Optimized</h2>
<p>Databases present loads of optimization opportunities. Relational data is initially stored in a normalized form to eliminate duplication, but later <em>denormalizations</em> can be performed when read access is more important.</p>

<p>When our use cases are not known at the outset, plan to iterate on the design, changing the structure to better support the use cases that emerge. This will mean evolving the schema design.</p>

<p>This applies to tables, columns, constraints, indexes, parameters, queries, and anything that can be optimized to better support real use cases.</p>

<p>Queries are restructured and indexes are added to reduce data access. Strive for highly selective data access (a small proportion of rows) on high cardinality (uniqueness) data to reduce latency.</p>

<p>Critical background processes like <a href="https://www.postgresql.org/docs/current/sql-vacuum.html">VACUUM</a> get optimized too. Resources (workers, memory, parallelization) are increased proportionally.</p>

<h2 id="responsive">Responsive</h2>
<p>When problems emerge like column or row level unexpected data, missing referential integrity, or query performance problems, engineers inspect logs, catalog statistics, and parameters, from the core engine and third party extensions to diagnose issues.</p>

<p>When DDL changes are ready, the engineer applies them in a non-blocking way, in multiple steps as needed. Operations are performed “online” by default when practical.</p>

<p>DDL changes are in a source code file, reviewed, tracked, and a copy of the schema design is kept in sync across environments.</p>

<p>Parameter (GUC) tuning (Postgres: <code class="language-plaintext highlighter-rouge">work_mem</code>, etc.) happens in a trackable way. Parameters are tuned online when possible, and scoped narrowly, to optimize their values for real queries and use cases.</p>

<h2 id="efficient">Efficient</h2>
<p>It’s relatively costly to store data in the database, compared with file storage! The data consumes limited space and accessing data unnecessarily adds latency.</p>

<p>Data that’s stored is queried later or it’s archived.</p>

<p>To minimize space consumption and latency, tables, columns, constraints, and indexes are removed continually by default, when they no longer are required, to reduce system complexity.</p>

<p>Server software is upgraded at least annually so that performance and security benefits can be leveraged.</p>

<p>Huge tables are split into smaller tables using table partitioning for more predictable administration.</p>

<h2 id="core-database-design">CORE Database Design</h2>
<p>There’s lots more to evolving a database schema design, but these principles are a few I keep in mind.</p>

<p>Did you notice anything missing? Do you have other feedback? Please <a href="/contact">contact me</a> with your thoughts.</p>

<h2 id="thank-you">Thank You</h2>
<p>Over the years, I’ve learned a lot from <a href="https://postgres.fm">Postgres.fm</a> hosts <a href="https://postgres.ai">Nikolay</a> and <a href="https://www.pgmustard.com">Michael</a>, and other community leaders like <a href="https://pganalyze.com">Lukas</a> and <a href="https://dev.to/franckpachot">Franck</a>, as they’ve shaped my database design choices.</p>

<p>I’m grateful to them for sharing their knowledge and experience with the community.</p>

<p>Thanks for reading!</p>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Databases" /><summary type="html"><![CDATA[Introduction In this post, we’ll cover some database design principles and package them up into a catchy mnemonic acronym.]]></summary></entry><entry><title type="html">Tip: Put your Rails app on a SQL query diet</title><link href="https://andyatkinson.com/tip-track-sql-queries-quantity-ruby-rails-postgresql" rel="alternate" type="text/html" title="Tip: Put your Rails app on a SQL query diet" /><published>2025-05-29T17:29:00+00:00</published><updated>2025-05-29T17:29:00+00:00</updated><id>https://andyatkinson.com/tip-track-quantity-of-queries-postgresql-ruby-rails</id><content type="html" xml:base="https://andyatkinson.com/tip-track-sql-queries-quantity-ruby-rails-postgresql"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>Much of the time taken processing HTTP requests in web apps is SQL queries. To minimize that, we want to avoid unnecessary and duplicate queries, and generally perform as few queries as possible.</p>

<p>Think of the work that needs to happen for <em>every</em> query. The database engine parses it, creates a query execution plan, executes it, and then sends the response to the client.</p>

<p>When the response reaches the client, there’s even more work to do. The response is transformed into application objects in memory.</p>

<p>How do we see how many queries are being created for our app actions?</p>

<h2 id="count-the-queries">Count the queries</h2>
<p>When doing backend work in a web app like Rails, monitor the number of queries being created directly, by the ORM, or by libraries. ORMs like Active Record can generate more than one query from a given line of code. Libraries can generate queries that are problematic and may be unnecessary.</p>

<p>Over time, developers may duplicate queries unknowingly. These are all real causes of unnecessary queries from my work experience.</p>

<p>Why are excessive queries a problem?</p>

<h2 id="why-reduce-the-number-of-queries">Why reduce the number of queries?</h2>
<p>Besides parsing, planning, executing, and serializing the response, the client is subject to a hard upper limit on the number of TCP connections it can send to the database server.</p>

<p>In Postgres that’s configured as <code class="language-plaintext highlighter-rouge">max_connections</code>. The application will have a variable number of open connections based on use, and its configuration of processes, threads and its connection pool. Keeping the query count low helps avoid exceeding the upper limit.</p>

<p>What about memory use?</p>

<h2 id="what-about-app-server-memory">What about app server memory?</h2>
<p>With Ruby on Rails, the cost of repeated queries is shifted because the <a href="https://guides.rubyonrails.org/caching_with_rails.html#sql-caching">SQL Cache</a> is enabled by default, which stores and serves results for matching repeated queries, at the cost of some memory use.</p>

<p>As an side, from <a href="https://www.shakacode.com/blog/rails-make-active-records-query-cache-an-lru">Rails 7.1 the SQL Cache uses a least recently used (LRU) algorithm</a>. We can also configure the max number of queries to cache, 100 by default, to control how much memory is used.</p>

<h2 id="counting-queries-prior-to-rails-72">Counting queries prior to Rails 7.2</h2>
<p>Prior to Rails 7.2, I recommend adding the <a href="https://github.com/rubysamurai/query_count"><strong>query_count</strong></a> gem which does a simple thing, it shows the count of SQL queries processed for an action.</p>

<p>The count is in the Rails log file like this: <code class="language-plaintext highlighter-rouge">SQL Queries: 100 (50 cached)</code>. In this case, 100 queries were performed and 50 used the SQL Cache.</p>

<h2 id="built-in-from-rails-72-onward">Built-in from Rails 7.2 onward</h2>
<p>From Rails 7.2 onward, the count of queries is now built in, so <a href="https://github.com/rubysamurai/query_count/issues/2">query_count is no longer needed</a>.</p>

<p>Rails 7.2 onward looks like this: <code class="language-plaintext highlighter-rouge">ActiveRecord: 105.5ms (10 queries, 1 cached)</code>. Here 10 queries ran, and 1 used the SQL Cache.</p>

<h2 id="repeated-queries">Repeated queries</h2>
<p>While the SQL Cache saves the roundtrip for a repeated query, ideally we want to eliminate the repeated query. It’s worth hunting for it and considering refactoring or restructuring data access.</p>

<p>Another tactic is using memoization to store results for the duration of processing one controller action. Read more about that: <a href="https://www.honeybadger.io/blog/ruby-rails-memoization/">Speeding up Rails with Memoization</a>.</p>

<p>How do I get started?</p>

<h2 id="finding-the-source-code-location-of-the-queries">Finding the source code location of the queries</h2>
<p>To get started, identify some slow API endpoints in production, run them locally in development, and begin monitoring their quantity of SQL queries. Find the <a href="https://andyatkinson.com/source-code-line-numbers-ruby-on-rails-marginalia-query-logs">Source code locations for database queries in Rails with Marginalia and Query Logs</a>.</p>

<p>Determine how to factor out data access that can be shared.</p>

<h2 id="how-many-queries-are-a-lot">How many queries are “a lot?”</h2>
<p>It’s hard to give a generic number. However, duplicate queries are a category to remove.</p>

<p>Let’s say you’ve got a Book model for your bookstore app. Scan your Rails log file for a pattern like this:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Book</span> <span class="k">Load</span> <span class="p">(</span><span class="mi">4</span><span class="p">.</span><span class="mi">3</span><span class="n">ms</span><span class="p">)</span> <span class="err">…</span>
<span class="n">Book</span> <span class="k">Load</span> <span class="p">(</span><span class="mi">5</span><span class="p">.</span><span class="mi">0</span><span class="n">ms</span><span class="p">)</span> <span class="err">…</span>
<span class="n">Book</span> <span class="k">Load</span> <span class="p">(</span><span class="mi">0</span><span class="p">.</span><span class="mi">5</span><span class="n">ms</span><span class="p">)</span> <span class="err">…</span>
<span class="n">Book</span> <span class="k">Load</span> <span class="p">(</span><span class="mi">2</span><span class="p">.</span><span class="mi">3</span><span class="n">ms</span><span class="p">)</span> <span class="err">…</span>
</code></pre></div></div>

<p>If you see that sort of pattern, track down the source locations, and eliminate any repeated loads. Let’s assume this is not a <a href="https://guides.rubyonrails.org/active_record_querying.html#n-1-queries-problem">N + 1 queries problem</a>, but repeated access to the same data from different source code locations.</p>

<p>You may be able to factor out and consolidate a data load. You may be able to use an existing loaded collection for an existence check, or use memoization to use previously calculated results.</p>

<p>Using these tactics, I’ve reduced controller actions with 250+ SQL queries (a ton!) to 50 or fewer (still a lot), by going through these steps. Monitor the log, find source locations for first party code, ORM generated queries, query code from libraries (gems), Rails controller action “before filters,” and other sources, then eliminate and consolidate.</p>

<p>When faced with a lot of queries, I find it helpful to study the bare minimum of what’s needed by the client, working outside in, then look to see if it’s possible to reduce the tables, rows, and columns to only what’s needed.</p>

<h2 id="wrap-up">Wrap Up</h2>
<ul>
  <li>Track the count of SQL queries performed in different versions of Rails</li>
  <li>Remove unnecessary queries so they don’t use limited system resources</li>
  <li>Eliminate repeated queries to keep the count as low as possible</li>
  <li>Only access data that’s needed for client application use cases</li>
</ul>]]></content><author><name>Andrew Atkinson</name></author><category term="Ruby on Rails" /><category term="PostgreSQL" /><summary type="html"><![CDATA[Introduction Much of the time taken processing HTTP requests in web apps is SQL queries. To minimize that, we want to avoid unnecessary and duplicate queries, and generally perform as few queries as possible.]]></summary></entry><entry><title type="html">Big Problems From Big IN lists with Ruby on Rails and PostgreSQL</title><link href="https://andyatkinson.com/big-problems-big-in-clauses-postgresql-ruby-on-rails" rel="alternate" type="text/html" title="Big Problems From Big IN lists with Ruby on Rails and PostgreSQL" /><published>2025-05-23T14:30:00+00:00</published><updated>2025-05-23T14:30:00+00:00</updated><id>https://andyatkinson.com/big-problems-big-in-clauses-postgresql-ruby-on-rails-orm</id><content type="html" xml:base="https://andyatkinson.com/big-problems-big-in-clauses-postgresql-ruby-on-rails"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>If you’ve created web apps with relational databases and ORMs like Active Record (part of Ruby on Rails), you’ve probably experienced database performance problems after a certain size of data and query volume.</p>

<p>In this post, we’re going to look at a specific type of problematic query pattern that’s somewhat common.</p>

<p>We’ll refer to this pattern as “Big <code class="language-plaintext highlighter-rouge">IN</code>s,” which are queries with an <code class="language-plaintext highlighter-rouge">IN</code> clause that has a big list of values. As data grows, the length of the list of values will grow. These queries tend to perform poorly for big lists, causing user experience problems or even partial outages.</p>

<p>We’ll dig into the origins of this pattern, why the performance of it is poor, and explore some alternatives that you can use in your projects.</p>

<h2 id="in-clauses-with-a-big-list-of-values">IN clauses with a big list of values</h2>
<p>The technical term for values are a <em>parenthesized list of scalar expressions</em>.</p>

<p>For example in the SQL query below, the <code class="language-plaintext highlighter-rouge">IN</code> clause portion is <code class="language-plaintext highlighter-rouge">WHERE author_id IN (1,2,3)</code> and the list of scalar expressions is <code class="language-plaintext highlighter-rouge">(1,2,3)</code>.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="o">*</span> <span class="k">FROM</span> <span class="n">books</span>
<span class="k">WHERE</span> <span class="n">author_id</span> <span class="k">IN</span> <span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">3</span><span class="p">);</span>
</code></pre></div></div>

<p>The purpose of this clause is to perform filtering. Looking at a query execution plan in Postgres, we’ll see something like this fragment below:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">author_id</span> <span class="o">=</span> <span class="k">ANY</span> <span class="p">(</span><span class="s1">'{1,2,3}'</span><span class="p">::</span><span class="nb">integer</span><span class="p">[]))</span>
</code></pre></div></div>

<p>This of course filters the full set of books down to ones that match on <code class="language-plaintext highlighter-rouge">author_id</code>.</p>

<p>Filtering is a typical database operation. Why are these slow?</p>

<h2 id="parsing-planning-and-executing">Parsing, planning, and executing</h2>
<p>Remember that our queries are parsed, planned, and executed. A big list of values are treated like constants, and don’t have associated statistics.</p>

<p>Queries with big lists of values take more time to parse and use more memory.</p>

<p>Without pre-collected table statistics for planning decisions, PostgreSQL is more likely to mis-estimate cardinality and row selectivity.</p>

<p>This can mean the planner chooses a sequential scan over an index scan, causing a big slowdown.</p>

<p>How do we create this pattern?</p>

<h2 id="creating-this-pattern-directly">Creating this pattern directly</h2>
<p>In Active Record, a developer might create this query pattern by using <code class="language-plaintext highlighter-rouge">pluck(:id)</code> to collect some ids in a list, then pass that list as an argument to another query.</p>

<p>Here’s an example of that:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">author_ids</span> <span class="o">=</span> <span class="n">Author</span><span class="p">.</span>
  <span class="k">where</span><span class="p">(</span><span class="nv">"created_at &gt;= ?"</span><span class="p">,</span> <span class="mi">1</span><span class="p">.</span><span class="nb">year</span><span class="p">.</span><span class="n">ago</span><span class="p">).</span>
  <span class="n">pluck</span><span class="p">(:</span><span class="n">id</span><span class="p">)</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">author_ids</code> are supplied as the argument querying <code class="language-plaintext highlighter-rouge">books</code> by <code class="language-plaintext highlighter-rouge">author_id</code> foreign key:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Book</span><span class="p">.</span><span class="k">where</span><span class="p">(</span><span class="n">author_id</span><span class="p">:</span> <span class="n">author_ids</span><span class="p">)</span>
</code></pre></div></div>

<p>Another scenario is when this query is created from ORM methods. What does that look like?</p>

<h2 id="active-record-orm-methods-that-create-this-pattern">Active Record ORM methods that create this pattern</h2>
<p>This query pattern can happen when using eager loading methods like <code class="language-plaintext highlighter-rouge">includes()</code> or <code class="language-plaintext highlighter-rouge">preload()</code>.</p>

<p>This <a href="https://www.crunchydata.com/blog/real-world-performance-gains-with-postgres-17-btree-bulk-scans">Crunchy Data post</a> mentions how eager loading methods produce <code class="language-plaintext highlighter-rouge">IN</code> clause SQL queries.</p>

<p>The post links to the <a href="https://guides.rubyonrails.org/active_record_querying.html#eager-loading-associations">Eager Loading Associations documentation</a> which has examples in Active Record and the resulting SQL that we’ll use here.</p>

<p>Let’s first discuss N+1 with these examples.</p>

<h2 id="fixing-n1s">Fixing N+1s</h2>
<p>Let’s study the examples here. Here’s some Active Record for books and authors:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># N+1</span>
<span class="n">books</span> <span class="o">=</span> <span class="no">Book</span><span class="p">.</span><span class="nf">limit</span><span class="p">(</span><span class="mi">10</span><span class="p">)</span>

<span class="n">books</span><span class="p">.</span><span class="nf">each</span> <span class="k">do</span> <span class="o">|</span><span class="n">book</span><span class="o">|</span>
   <span class="nb">puts</span> <span class="n">book</span><span class="p">.</span><span class="nf">author</span><span class="p">.</span><span class="nf">last_name</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The issue above is the undesirable N+1 query pattern, where a table is repeatedly queried in a loop, instead of bulk loading all of the desired authors.</p>

<p>To fix the N+1, we’ll add the <code class="language-plaintext highlighter-rouge">includes(:author)</code> eager loading method to the code above.</p>

<p>That looks like this:</p>
<pre><code>
books = Book.<strong style="background-color:yellow;">includes(:author)</strong>.limit(10) 👈

books.each do |book|
   puts book.author.last_name
end
</code></pre>

<p>We’ve now eliminated the N+1 queries, but we’ve opened ourselves up to a new possible problem.</p>

<h2 id="eager-loading-with-includes-or-preload">Eager loading with includes or preload</h2>
<p>While the <code class="language-plaintext highlighter-rouge">includes(:author)</code> fixed the N+1 queries, Active Record is now creating two queries, with the second one having an <code class="language-plaintext highlighter-rouge">IN</code> clause.</p>

<p>Here’s the example from above as SQL:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">books</span><span class="p">.</span><span class="o">*</span> <span class="k">FROM</span> <span class="n">books</span> <span class="k">LIMIT</span> <span class="mi">10</span><span class="p">;</span>

<span class="k">SELECT</span> <span class="n">authors</span><span class="p">.</span><span class="o">*</span> <span class="k">FROM</span> <span class="n">authors</span>
  <span class="k">WHERE</span> <span class="n">authors</span><span class="p">.</span><span class="n">id</span> <span class="k">IN</span> <span class="p">(</span><span class="mi">1</span><span class="p">,</span><span class="mi">2</span><span class="p">,</span><span class="mi">3</span><span class="p">,</span><span class="mi">4</span><span class="p">,</span><span class="mi">5</span><span class="p">,</span><span class="mi">6</span><span class="p">,</span><span class="mi">7</span><span class="p">,</span><span class="mi">8</span><span class="p">,</span><span class="mi">9</span><span class="p">,</span><span class="mi">10</span><span class="p">);</span>
</code></pre></div></div>

<p>Here we only have 10 values for the <code class="language-plaintext highlighter-rouge">IN</code> clause, so performance will be fine. However, once we’ve got hundreds or thousands of values, we will run into the problems described above.</p>

<p>Performance will tank if the <code class="language-plaintext highlighter-rouge">authors.id</code> primary key index isn’t used for this filtering operation.</p>

<p>Are there alternatives for eager loading?</p>

<h2 id="eager-loading-using-eager_load">Eager loading using eager_load</h2>
<p>Besides <code class="language-plaintext highlighter-rouge">includes()</code> and <code class="language-plaintext highlighter-rouge">preload()</code> which create two queries with the second having an <code class="language-plaintext highlighter-rouge">IN</code> clause, there’s another way to do eager loading in Active Record.</p>

<p>An alternative method <code class="language-plaintext highlighter-rouge">eager_load</code> works a little bit differently. It produces a single SQL query that uses a <code class="language-plaintext highlighter-rouge">LEFT OUTER JOIN</code>.</p>

<p>Here’s an example of <code class="language-plaintext highlighter-rouge">eager_load</code> from the Active Record documentation:</p>
<div class="language-rb highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">books</span> <span class="o">=</span> <span class="no">Book</span><span class="p">.</span><span class="nf">eager_load</span><span class="p">(</span><span class="ss">:author</span><span class="p">).</span><span class="nf">limit</span><span class="p">(</span><span class="mi">10</span><span class="p">)</span>

<span class="n">books</span><span class="p">.</span><span class="nf">each</span> <span class="k">do</span> <span class="o">|</span><span class="n">book</span><span class="o">|</span>
  <span class="nb">puts</span> <span class="n">book</span><span class="p">.</span><span class="nf">author</span><span class="p">.</span><span class="nf">last_name</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The following single SQL query is produced. Note that it has no <code class="language-plaintext highlighter-rouge">IN</code> clause.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span>
    <span class="nv">"books"</span><span class="p">.</span><span class="nv">"id"</span> <span class="k">AS</span> <span class="n">t0_r0</span><span class="p">,</span>
    <span class="nv">"books"</span><span class="p">.</span><span class="nv">"title"</span> <span class="k">AS</span> <span class="n">t0_r1</span>
<span class="k">FROM</span>
    <span class="nv">"books"</span> <span class="k">LEFT</span> <span class="k">OUTER</span> <span class="k">JOIN</span> <span class="nv">"authors"</span>
    <span class="k">ON</span> <span class="nv">"authors"</span><span class="p">.</span><span class="nv">"id"</span> <span class="o">=</span> <span class="nv">"books"</span><span class="p">.</span><span class="nv">"author_id"</span>
<span class="k">LIMIT</span> <span class="mi">10</span><span class="p">;</span>
</code></pre></div></div>

<p>Since we’re now using a join operation, we’ve got statistics available from both tables. This makes it much more likely PostgreSQL can correctly estimate selectivity and cardinality.</p>

<p>The planner also isn’t needing to parse and store a large list of constant values.</p>

<p>While <code class="language-plaintext highlighter-rouge">IN</code> clauses might perform fine with smaller inputs of 100 values or fewer, for large lists we should try and restructure the query to use a join operation instead.</p>

<p>Besides restructuring the queries into joins, are there other alternatives?</p>

<h2 id="alternative-approaches-using-any">Alternative approaches using ANY</h2>
<p>Crunchy Data’s post <a href="https://www.crunchydata.com/blog/postgres-query-boost-using-any-instead-of-in">Postgres Query Boost: Using ANY Instead of IN</a> describes how <code class="language-plaintext highlighter-rouge">IN</code> is more restrictive on the input.</p>

<p>A more usable alternative to <code class="language-plaintext highlighter-rouge">IN</code> can be <code class="language-plaintext highlighter-rouge">ANY</code> (or synonym <code class="language-plaintext highlighter-rouge">SOME</code>), which has more flexibility in handling the list of values.</p>

<p>Here’s A CTE example using <code class="language-plaintext highlighter-rouge">ANY</code>:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">WITH</span> <span class="n">author_ids</span> <span class="k">AS</span> <span class="p">(</span>
  <span class="k">SELECT</span> <span class="n">id</span> <span class="k">FROM</span> <span class="n">authors</span>
<span class="p">)</span>
<span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span>
<span class="k">WHERE</span> <span class="n">author_id</span> <span class="o">=</span> <span class="k">ANY</span> <span class="p">(</span>
      <span class="k">SELECT</span> <span class="n">id</span>
      <span class="k">FROM</span> <span class="n">author_ids</span><span class="p">);</span>
</code></pre></div></div>

<p>However, <code class="language-plaintext highlighter-rouge">ANY</code> is not generated by Active Record. What if we want to generate these queries using Active Record?</p>

<p>One option is to use the <code class="language-plaintext highlighter-rouge">any</code> method provided by the <a href="https://github.com/GeorgeKaraszi/ActiveRecordExtended">ActiveRecordExtended</a> gem.</p>

<p>Let’s talk at another alternative approach using a <code class="language-plaintext highlighter-rouge">VALUES</code> clause.</p>

<h2 id="a-values-clause">A VALUES clause</h2>
<p>In the comments in the PR above, Vlad and Sean discussed an alternative for <code class="language-plaintext highlighter-rouge">IN</code> using a <code class="language-plaintext highlighter-rouge">VALUES</code> clause.</p>

<p>Let’s look at an example with a CTE and <code class="language-plaintext highlighter-rouge">VALUES</code> clause:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">WITH</span> <span class="n">ids</span><span class="p">(</span><span class="n">author_id</span><span class="p">)</span> <span class="k">AS</span> <span class="p">(</span>
  <span class="k">VALUES</span><span class="p">(</span><span class="mi">1</span><span class="p">),(</span><span class="mi">2</span><span class="p">),(</span><span class="mi">3</span><span class="p">)</span>
<span class="p">)</span>
<span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span>
<span class="k">JOIN</span> <span class="n">ids</span> <span class="k">USING</span> <span class="p">(</span><span class="n">author_id</span><span class="p">);</span>
</code></pre></div></div>

<p>Or we can write this as a subquery:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span>
<span class="k">WHERE</span> <span class="n">author_id</span> <span class="k">IN</span> <span class="p">(</span>
  <span class="k">SELECT</span> <span class="n">id</span>
  <span class="k">FROM</span> <span class="p">(</span><span class="k">VALUES</span><span class="p">(</span><span class="mi">1</span><span class="p">),(</span><span class="mi">2</span><span class="p">),(</span><span class="mi">3</span><span class="p">))</span> <span class="k">AS</span> <span class="n">v</span><span class="p">(</span><span class="n">id</span><span class="p">)</span>
<span class="p">);</span>
</code></pre></div></div>

<p>This is better because the <code class="language-plaintext highlighter-rouge">IN</code> list is a big list of scalar expressions, where the <code class="language-plaintext highlighter-rouge">VALUES</code> clause is treated like a relation (or table). This can help with join strategy selection.</p>

<h2 id="a-temporary-table-of-ids">A temporary table of ids</h2>
<p>Yet another option for big lists of values is to put these into a temporary table for the session. The temporary table can even index the ids.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">CREATE</span> <span class="k">TEMP</span> <span class="k">TABLE</span> <span class="n">temp_ids</span> <span class="p">(</span><span class="n">author_id</span> <span class="nb">int</span><span class="p">);</span>
<span class="k">INSERT</span> <span class="k">INTO</span> <span class="n">temp_ids</span><span class="p">(</span><span class="n">author_id</span><span class="p">)</span> <span class="k">VALUES</span> <span class="p">(</span><span class="mi">1</span><span class="p">),(</span><span class="mi">2</span><span class="p">),(</span><span class="mi">3</span><span class="p">);</span>
<span class="k">CREATE</span> <span class="k">INDEX</span> <span class="k">ON</span> <span class="n">temp_ids</span><span class="p">(</span><span class="n">author_id</span><span class="p">);</span>

<span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span> <span class="n">b</span>
<span class="k">JOIN</span> <span class="n">temp_ids</span> <span class="n">t</span> <span class="k">ON</span> <span class="n">t</span><span class="p">.</span><span class="n">author_id</span> <span class="o">=</span> <span class="n">b</span><span class="p">.</span><span class="n">author_id</span><span class="p">;</span>
</code></pre></div></div>

<h2 id="using-any-and-an-array-of-values">Using ANY and an ARRAY of values</h2>
<p>Another form is using <code class="language-plaintext highlighter-rouge">ANY</code> with an ARRAY:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span>
<span class="k">WHERE</span> <span class="n">author_id</span> <span class="o">=</span> <span class="k">ANY</span> <span class="p">(</span><span class="n">ARRAY</span><span class="p">[</span><span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">3</span><span class="p">]);</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">ANY</code> form can perform better. With an <code class="language-plaintext highlighter-rouge">IN</code> list, the values are parsed like a chain of OR operations, with the planner handling one branch at a time.</p>

<p><code class="language-plaintext highlighter-rouge">ANY</code> is treated like a single functional expression.</p>

<p>This form also supports prepared statements. With prepared statements, the statement is parsed and planned once and then can be reused.</p>

<p>Here’s an example of fetching books by author:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">PREPARE</span> <span class="n">get_books_by_author</span><span class="p">(</span><span class="nb">int</span><span class="p">[])</span> <span class="k">AS</span>
<span class="k">SELECT</span> <span class="n">title</span>
<span class="k">FROM</span> <span class="n">books</span>
<span class="k">WHERE</span> <span class="n">author_id</span> <span class="o">=</span> <span class="k">ANY</span> <span class="p">(</span><span class="err">$</span><span class="mi">1</span><span class="p">);</span>

<span class="k">EXECUTE</span> <span class="n">get_books_by_author</span><span class="p">(</span><span class="n">ARRAY</span><span class="p">[</span><span class="mi">1</span><span class="p">,</span><span class="mi">2</span><span class="p">,</span><span class="mi">3</span><span class="p">,</span><span class="mi">4</span><span class="p">,</span><span class="mi">5</span><span class="p">]);</span>
</code></pre></div></div>

<h2 id="testing-the-alternative-query-structures">Testing the alternative query structures</h2>
<p>Unfortunately generic guidelines here won’t guarantee success in your specific database. Row counts, data distributions, cardinality, or correlation are just some of the factors that affect query execution.</p>

<p>My recommended process is to test on production-like data, work in the SQL layer, then try out restructured queries using these tactics, and study their query execution plans collected using <code class="language-plaintext highlighter-rouge">EXPLAIN (ANALYZE, BUFFERS)</code>.</p>

<p>Query plan collection and analysis is outside the scope of this post, but in brief, you’ll want to compare the plans and look to access fewer buffers, at lower costs, with fewer rows evaluated, fewer loops, for more efficient execution.</p>

<p>If you’re working in Active Record, you’d then translate your SQL back into the Active Record source code location where the queries were generated.</p>

<p>How do we find problematic <code class="language-plaintext highlighter-rouge">IN</code> queries that ran earlier in Postgres?</p>

<h2 id="finding-in-clause-queries-in-pg_stat_statements">Finding IN clause queries in pg_stat_statements</h2>
<p>To find out if your query stats include the problematic <code class="language-plaintext highlighter-rouge">IN</code> queries, let’s search the results of <code class="language-plaintext highlighter-rouge">pg_stat_statements</code> by querying the <code class="language-plaintext highlighter-rouge">query</code> field.</p>

<p>Unfortunately these don’t always group up well, so there can be duplicates or near-duplicates. You may have lots of PGSS results to sift through.</p>

<p>Here’s a basic query to filter on <code class="language-plaintext highlighter-rouge">query</code> for <code class="language-plaintext highlighter-rouge">'%IN \(%'</code>:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span>
    <span class="n">query</span>
<span class="k">FROM</span>
    <span class="n">pg_stat_statements</span>
<span class="k">WHERE</span>
    <span class="n">query</span> <span class="k">LIKE</span> <span class="s1">'%IN </span><span class="se">\(</span><span class="s1">%'</span><span class="p">;</span>
</code></pre></div></div>
<p>See the <a href="https://github.com/andyatkinson/pg_scripts/pull/16">linked PR</a> for a reproduction set of commands to create these tables, queries, and then inspect the query statistics using PGSS.</p>

<p>While you can find and restructure your queries towards more efficient patterns, are there any changes coming to Postgres itself to better handle these?</p>

<h2 id="improvements-in-postgres-17">Improvements in Postgres 17</h2>
<p>As part of the PostgreSQL 17 release in 2024, the developers made improvements to more efficiently work with scalar expressions and indexes, resulting in fewer repeated scans, and thus faster execution.</p>

<p>This reduces latency by reducing IO, and the benefits are available to all Postgres users without the need to change their SQL queries or ORM code!</p>

<h2 id="grouping-similar-query-groups-in-pg_stat_statements">Grouping similar query groups in pg_stat_statements</h2>
<p>There are more usability improvements coming for Postgres users, pg_stat_statements, and <code class="language-plaintext highlighter-rouge">IN</code> clause queries.</p>

<p>One problem with these has been that similar entries aren’t collapsed together when they have a different numbers of scalar array expressions.</p>

<p>For example <code class="language-plaintext highlighter-rouge">IN ('1')</code> was not grouped with <code class="language-plaintext highlighter-rouge">IN ('1','2')</code>. Having the statistics for nearly identical entries split across multiple results makes them less useful.</p>

<p>Fortunately, fixes are coming. On the Ruby on Rails side, Sean Linsley is working on a fix by replacing the use of <code class="language-plaintext highlighter-rouge">IN</code> with <code class="language-plaintext highlighter-rouge">ANY</code> which solves the grouping problem.</p>

<p>Here’s the PR: <a href="https://github.com/rails/rails/pull/49388#issuecomment-2680362607">https://github.com/rails/rails/pull/49388#issuecomment-2680362607</a></p>

<p>On the PostgreSQL side, there are fixes coming for PostgreSQL 18.</p>

<h2 id="improvements-in-postgresql-18">Improvements in PostgreSQL 18</h2>
<p>Related improvements are coming to PostgreSQL 18 for 2025.</p>

<p>This commit<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup> implements the automatic conversion of <code class="language-plaintext highlighter-rouge">x IN (VALUES ...)</code> into ScalarArrayOpExpr.</p>

<p>Another noteworthy commit is: “Squash query list jumbling” from Álvaro Herrera.<sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup></p>

<p>pg_stat_statements produces multiple entries for queries like <code class="language-plaintext highlighter-rouge">SELECT something FROM table WHERE col IN (1, 2, 3, ...)</code> depending on the number of parameters, because every element of ArrayExpr is individually jumbled.
Most of the time that’s undesirable, especially if the list becomes too large.</p>

<p>This commit<sup id="fnref:3" role="doc-noteref"><a href="#fn:3" class="footnote" rel="footnote">3</a></sup> mentions the original design was for a GUC query_id_squash_values, but that was removed in favor of making this the default behavior.</p>

<h2 id="conclusion">Conclusion</h2>
<p>In this post, we looked at a problematic query pattern, big <code class="language-plaintext highlighter-rouge">IN</code> lists. You may have instances of this pattern in your codebase from direct means or from using some ORM methods.</p>

<p>This type of query performs poorly for big lists of values, as they take more resources to parse, plan, and execute. There are fewer indexing options compared with an alternative structured as a join operation. Join queries provide two sets of table statistics from both tables being joined, that help with query planning.</p>

<p>We learned how to find instances of these using pg_stat_statements for PostgreSQL. The post then considers several alternatives.</p>

<p>Our main tactics are to convert these queries to joins when possible. Outside of that, we could consider using the <code class="language-plaintext highlighter-rouge">ANY</code> operator with an array of values, a <code class="language-plaintext highlighter-rouge">VALUES</code> clause, and consider using a prepared statement.</p>

<p>The next time you see big <code class="language-plaintext highlighter-rouge">IN</code> lists causing database performance problems, hopefully you feel more prepared to restructure and optimize them!</p>

<p>Thanks for reading this post. I’d love to hear about any tips or tricks you have for these types of queries!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p><a href="https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=c0962a113d1f2f94cb7222a7ca025a67e9ce3860">https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=c0962a113d1f2f94cb7222a7ca025a67e9ce3860</a> <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p><a href="https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=62d712ecfd940f60e68bde5b6972b6859937c412">https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=62d712ecfd940f60e68bde5b6972b6859937c412</a> <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3" role="doc-endnote">
      <p><a href="https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=9fbd53dea5d513a78ca04834101ca1aa73b63e59">https://git.postgresql.org/gitweb/?p=postgresql.git;a=commit;h=9fbd53dea5d513a78ca04834101ca1aa73b63e59</a> <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><category term="Ruby on Rails" /><summary type="html"><![CDATA[Introduction If you’ve created web apps with relational databases and ORMs like Active Record (part of Ruby on Rails), you’ve probably experienced database performance problems after a certain size of data and query volume.]]></summary></entry><entry><title type="html">Short alphanumeric pseudo random identifiers in Postgres</title><link href="https://andyatkinson.com/generating-short-alphanumeric-public-id-postgres" rel="alternate" type="text/html" title="Short alphanumeric pseudo random identifiers in Postgres" /><published>2025-05-20T16:00:00+00:00</published><updated>2025-05-20T16:00:00+00:00</updated><id>https://andyatkinson.com/postgres-short-alphanumeric-public-id</id><content type="html" xml:base="https://andyatkinson.com/generating-short-alphanumeric-public-id-postgres"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>In this post, we’ll cover a way to generate short, alphanumeric, pseudo random identifiers using native Postgres tactics.</p>

<p>These identifiers can be used for things like transactions or reservations, where users need to read and share them easily. This approach is an alternative to using long, random generated values like <a href="https://en.wikipedia.org/wiki/Universally_unique_identifier">UUID</a> values, which have downsides for usability and performance.</p>

<p>We’ll call the identifier a <code class="language-plaintext highlighter-rouge">public_id</code> and store it in a column with that name. Here are some example values:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span> <span class="n">public_id</span>
<span class="k">FROM</span> <span class="n">transactions</span>
<span class="k">ORDER</span> <span class="k">BY</span> <span class="n">random</span><span class="p">()</span>
<span class="k">LIMIT</span> <span class="mi">3</span><span class="p">;</span>

 <span class="n">public_id</span>
<span class="c1">-----------</span>
 <span class="mi">0359</span><span class="n">Y</span>
 <span class="mi">08</span><span class="n">nAS</span>
 <span class="mi">096</span><span class="n">WV</span>
</code></pre></div></div>

<h2 id="natural-and-surrogate-keys">Natural and Surrogate Keys</h2>
<p>In database design, we can use natural or surrogate keys to identify rows. We won’t cover the differences here as that’s out of scope.</p>

<p>For our <code class="language-plaintext highlighter-rouge">public_id</code> identifier, we’re going to generate it from a conventional surrogate <code class="language-plaintext highlighter-rouge">integer</code> primary key called <code class="language-plaintext highlighter-rouge">id</code>. We aren’t using natural keys here.</p>

<p>The <code class="language-plaintext highlighter-rouge">public_id</code> is intended for use outside the database, while the <code class="language-plaintext highlighter-rouge">id</code> <code class="language-plaintext highlighter-rouge">integer</code> primary key is used inside the database to be referenced by foreign key columns on other tables.</p>

<p>Whle <code class="language-plaintext highlighter-rouge">public_id</code> is short which minimizes space and speeds up access, the main reason for it is for usability.</p>

<p>With that said, the target for total space consumption was to be fewer bytes than a 16-byte UUID. This was achieved with an <code class="language-plaintext highlighter-rouge">integer</code> primary key and this additional 5 character generated value, targeting a smaller database where this provides plenty of unique values now and into the future.</p>

<p>Let’s get into the design details.</p>

<h2 id="design-properties">Design Properties</h2>
<p>Here were the desired design properties:</p>

<ul>
  <li>A fixed size, 5 characters in length, regardless of the size of the input integer (and within the range of the <code class="language-plaintext highlighter-rouge">integer</code> data type)</li>
  <li>Fewer bytes of space than a <code class="language-plaintext highlighter-rouge">uuid</code> data type</li>
  <li>An obfuscated value, pseudo random, not easily guessable. While not easily guessable, this is not meant to be “secure”</li>
  <li>Reversibility back into the original integer</li>
  <li>Only native Postgres capabilities, no extensions, client web app language can be anything as it’s within Postgres</li>
  <li>Non math-heavy implementation</li>
</ul>

<p>Additional details:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">public_id</code> is stored using <code class="language-plaintext highlighter-rouge">text</code> not not <code class="language-plaintext highlighter-rouge">char(5)</code>, following recommendations for best practices</li>
  <li>PL/PgSQL functions, native Postgres data types and constraints are used, like UNIQUE, NOT NULL, and CHECK, and a stored generated column.</li>
  <li>Converts integers to bits, uses exclusive-or (XOR) bitwise operation and modulo operations.</li>
</ul>

<h2 id="limitations">Limitations</h2>
<ul>
  <li>Did not set out to support case insensitivity now, possible future enhancement</li>
  <li>Did not try to exclude similar-looking characters (see: <a href="https://www.crockford.com/base32.html">Base32 Crockford</a> below), possible future enhancement</li>
</ul>

<h2 id="plpgsql-functions">PL/PgSQL Functions</h2>
<p>Here are the functions used:</p>

<p>This function obfuscates the integer value using exclusive or (XOR) obfuscation.</p>
<ul>
  <li>Uses a Hexadecimal key <code class="language-plaintext highlighter-rouge">0x5A3C1</code> (make this any key you want)</li>
  <li>Sets a max value for the data type range <code class="language-plaintext highlighter-rouge">62^5</code>, which is just under 1 billion possible values. This was enough for this system and into the future, but a bigger system would want to use <code class="language-plaintext highlighter-rouge">bigint</code></li>
  <li>Converts integer bytes into bits</li>
</ul>

<p>Main entrypoint function:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">obfuscate_id(id INTEGER)</code></li>
</ul>

<p>This converts the obfuscated value into the <code class="language-plaintext highlighter-rouge">public_id</code> alphanumeric value, used within <code class="language-plaintext highlighter-rouge">obfuscate_id()</code>.</p>

<p>This is “base 62” with the 26 upper and lower case characters, and 10 numbers (0-9).</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">to_base62_fixed(val BIGINT, width INT DEFAULT 5)</code></li>
</ul>

<p>Reverses the <code class="language-plaintext highlighter-rouge">public_id</code> back into the original integer.</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">deobfuscate_id(public_id TEXT)</code></li>
</ul>

<p>Used within <code class="language-plaintext highlighter-rouge">deobfuscate_id()</code>:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">from_base62_fixed(str TEXT)</code></li>
</ul>

<p>For a length of 5 with this system, we can create up to around ~1 billion unique values. This was sufficiently large for the original use case.</p>

<p>For use cases requiring more values, by storing 6 characters for <code class="language-plaintext highlighter-rouge">public_id</code> then up to ~56 billion values could be generated, based on a <code class="language-plaintext highlighter-rouge">bigint</code> primary key.</p>

<h2 id="table-design">Table Design</h2>
<p>Let’s create a sample <code class="language-plaintext highlighter-rouge">transactions</code> table with an <code class="language-plaintext highlighter-rouge">integer</code> primary key with a generated identity column.</p>

<p>Besides the use in the identity column, we’ll again use the <code class="language-plaintext highlighter-rouge">GENERATED</code> keyword to create a <code class="language-plaintext highlighter-rouge">STORED</code> column for the <code class="language-plaintext highlighter-rouge">public_id</code>.</p>

<p>The <code class="language-plaintext highlighter-rouge">public_id</code> column uses the <code class="language-plaintext highlighter-rouge">id</code> column as input, obfuscates it, encodes it to base 62, producing a 5 character value.</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">DROP</span> <span class="k">TABLE</span> <span class="n">IF</span> <span class="k">EXISTS</span> <span class="n">transactions</span><span class="p">;</span>
<span class="k">CREATE</span> <span class="k">TABLE</span> <span class="n">transactions</span> <span class="p">(</span>
  <span class="n">id</span> <span class="nb">INTEGER</span> <span class="k">GENERATED</span> <span class="n">ALWAYS</span> <span class="k">AS</span> <span class="k">IDENTITY</span> <span class="k">PRIMARY</span> <span class="k">KEY</span><span class="p">,</span>  <span class="c1">-- 4-byte integer ID</span>
  <span class="n">public_id</span> <span class="nb">text</span> <span class="k">GENERATED</span> <span class="n">ALWAYS</span> <span class="k">AS</span> <span class="p">(</span><span class="n">obfuscate_id</span><span class="p">(</span><span class="n">id</span><span class="p">))</span> <span class="n">STORED</span> <span class="k">UNIQUE</span> <span class="k">NOT</span> <span class="k">NULL</span><span class="p">,</span> <span class="c1">-- 5-character obfuscated Base62 value</span>
  <span class="n">amount</span> <span class="nb">NUMERIC</span><span class="p">,</span>
  <span class="n">description</span> <span class="nb">TEXT</span>
<span class="p">);</span>
</code></pre></div></div>

<p>How do we guarantee <code class="language-plaintext highlighter-rouge">public_id</code> conforms to our expected data properties? Constraints!</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">public_id</code> gets a <code class="language-plaintext highlighter-rouge">UNIQUE</code> constraint and <code class="language-plaintext highlighter-rouge">NOT NULL</code>, so we know we have a unique value</li>
  <li>A <code class="language-plaintext highlighter-rouge">CHECK</code> constraint is added to validate the length</li>
</ul>

<p>For an existing system, we could add a unique index <code class="language-plaintext highlighter-rouge">CONCURRENTLY</code> first as follows:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">CREATE</span> <span class="k">UNIQUE</span> <span class="k">INDEX</span> <span class="n">CONCURRENTLY</span> <span class="n">IF</span> <span class="k">NOT</span> <span class="k">EXISTS</span> <span class="n">idx_uniq_pub_id</span> <span class="k">ON</span> <span class="n">transactions</span> <span class="p">(</span><span class="n">public_id</span><span class="p">);</span>
</code></pre></div></div>

<p>Then we can add the unique constraint using the unique index, along with the <code class="language-plaintext highlighter-rouge">CHECK</code> constraint:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">ALTER</span> <span class="k">TABLE</span> <span class="n">transactions</span>
    <span class="k">ADD</span> <span class="k">CONSTRAINT</span> <span class="n">uniq_pub_id</span> <span class="k">UNIQUE</span> <span class="k">USING</span> <span class="k">INDEX</span> <span class="n">idx_uniq_pub_id</span><span class="p">,</span> <span class="c1">-- depends on index above</span>
    <span class="k">ADD</span> <span class="k">CONSTRAINT</span> <span class="n">public_id_length</span> <span class="k">CHECK</span> <span class="p">(</span><span class="k">LENGTH</span><span class="p">(</span><span class="n">public_id</span><span class="p">)</span> <span class="o">&lt;=</span> <span class="mi">5</span><span class="p">);</span>
</code></pre></div></div>

<h2 id="insert-data">Insert Data</h2>
<p>Let’s insert data into the <code class="language-plaintext highlighter-rouge">transactions</code> table:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">INSERT</span> <span class="k">INTO</span> <span class="n">transactions</span> <span class="p">(</span><span class="n">amount</span><span class="p">,</span> <span class="n">description</span><span class="p">)</span> <span class="k">VALUES</span>
  <span class="p">(</span><span class="mi">100</span><span class="p">.</span><span class="mi">00</span><span class="p">,</span> <span class="s1">'First transaction'</span><span class="p">),</span>
  <span class="p">(</span><span class="mi">50</span><span class="p">.</span><span class="mi">00</span><span class="p">,</span> <span class="s1">'Second transaction'</span><span class="p">),</span>
  <span class="p">(</span><span class="mi">0</span><span class="p">.</span><span class="mi">25</span><span class="p">,</span> <span class="s1">'Third transaction'</span><span class="p">);</span>
</code></pre></div></div>

<p>Let’s query the data, and also make sure it’s reversed (using the <code class="language-plaintext highlighter-rouge">deobfuscate_id(public_id TEXT)</code> function) properly:</p>

<h2 id="access-the-rows">Access the rows</h2>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SELECT</span>
    <span class="n">id</span><span class="p">,</span>
    <span class="n">public_id</span><span class="p">,</span>
    <span class="n">deobfuscate_id</span><span class="p">(</span><span class="n">public_id</span><span class="p">)</span> <span class="k">AS</span> <span class="n">reversed_id</span><span class="p">,</span>
    <span class="n">description</span>
<span class="k">FROM</span>
    <span class="n">transactions</span><span class="p">;</span>


 <span class="n">id</span> <span class="o">|</span> <span class="n">public_id</span> <span class="o">|</span> <span class="n">reversed_id</span> <span class="o">|</span>    <span class="n">description</span>
<span class="c1">----+-----------+-------------+--------------------</span>
  <span class="mi">1</span> <span class="o">|</span> <span class="mi">01</span><span class="n">Y9I</span>     <span class="o">|</span>           <span class="mi">1</span> <span class="o">|</span> <span class="k">First</span> <span class="n">transaction</span>
  <span class="mi">2</span> <span class="o">|</span> <span class="mi">01</span><span class="n">Y9L</span>     <span class="o">|</span>           <span class="mi">2</span> <span class="o">|</span> <span class="k">Second</span> <span class="n">transaction</span>
  <span class="mi">3</span> <span class="o">|</span> <span class="mi">01</span><span class="n">Y9K</span>     <span class="o">|</span>           <span class="mi">3</span> <span class="o">|</span> <span class="n">Third</span> <span class="n">transaction</span>
</code></pre></div></div>

<h2 id="additional-time-spent-on-inserts">Additional time spent on inserts</h2>
<p>Let’s compare the time spent inserting 1 million rows into an equivalent <code class="language-plaintext highlighter-rouge">transactions</code> table without the <code class="language-plaintext highlighter-rouge">public_id</code> column or value generation.</p>

<p>That took an average of 2037.906 milliseconds, or around 2 seconds on my machine.</p>

<p>Inserting 1 million rows with the <code class="language-plaintext highlighter-rouge">public_id</code> took an average of 6954.070 or around 7 seconds, or about 3.41x slower. Note that these times were with the indexes and constraints in place on the <code class="language-plaintext highlighter-rouge">transactions</code> table in the second example, but not the first, meaning their presence contributed to the total time.</p>

<p>Summary: Creating this identifier made the write operations 3.4x slower for me locally, which was an acceptable amount of overhead for the intended use case.</p>

<h2 id="performance">Performance</h2>
<p>Compared with random values, the pseudo random <code class="language-plaintext highlighter-rouge">public_id</code> remains orderable, which means that lookups for individual rows or ranges of rows can use indexes, running fast and reliably even as row counts grow.</p>

<p>We can add a unique index on the <code class="language-plaintext highlighter-rouge">public_id</code> column like this:</p>
<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">CREATE</span> <span class="k">UNIQUE</span> <span class="k">INDEX</span> <span class="n">CONCURRENTLY</span>
<span class="n">IF</span> <span class="k">NOT</span> <span class="k">EXISTS</span>
<span class="n">idx_uniq_pub_id</span> <span class="k">ON</span> <span class="n">transactions</span> <span class="p">(</span><span class="n">public_id</span><span class="p">);</span>
</code></pre></div></div>

<p>We can verify that individual lookups or range scans use this index, by inspecting query execution plans for this table.</p>

<h2 id="plpgsql-source-code">PL/pgSQL Source Code</h2>
<p><a href="https://github.com/andyatkinson/pg_scripts/pull/15">https://github.com/andyatkinson/pg_scripts/pull/15</a></p>

<h2 id="feedback">Feedback</h2>
<p>Feedback on this approach is welcomed! Please use my contact form to provide feedback or leave comments on the PR.</p>

<p>Future enhancements to this could include unit tests using <a href="https://pgtap.org">pgTAP</a> for the functions, packaging them into an extension, or supporting more features like case insensitivity or a modified input alphabet.</p>

<p>Thanks for reading!</p>

<h2 id="alternatives">Alternatives</h2>
<ul>
  <li><a href="https://www.crockford.com/base32.html">Base32 Crockford</a> - An emphasis ease of use for humans: removing similar looking characters, case insensitivity.</li>
  <li><a href="https://blog.lawrencejones.dev/ulid/">ULID</a> - Also 128 bits/16 bytes like UUIDs, so I had ruled these out for space consumption, and they’re slightly less “usable”</li>
  <li><a href="https://planetscale.com/blog/why-we-chose-nanoids-for-planetscales-api">NanoIDs at PlanetScale</a> - I like aspects of NanoID. This is random generation though like UUID vs. encoding a unique integer.</li>
</ul>]]></content><author><name>Andrew Atkinson</name></author><category term="PostgreSQL" /><summary type="html"><![CDATA[Introduction In this post, we’ll cover a way to generate short, alphanumeric, pseudo random identifiers using native Postgres tactics.]]></summary></entry></feed>